Running LLM batches as Render Workflow tasks instead of web requests
- Source
- x.com
- Date

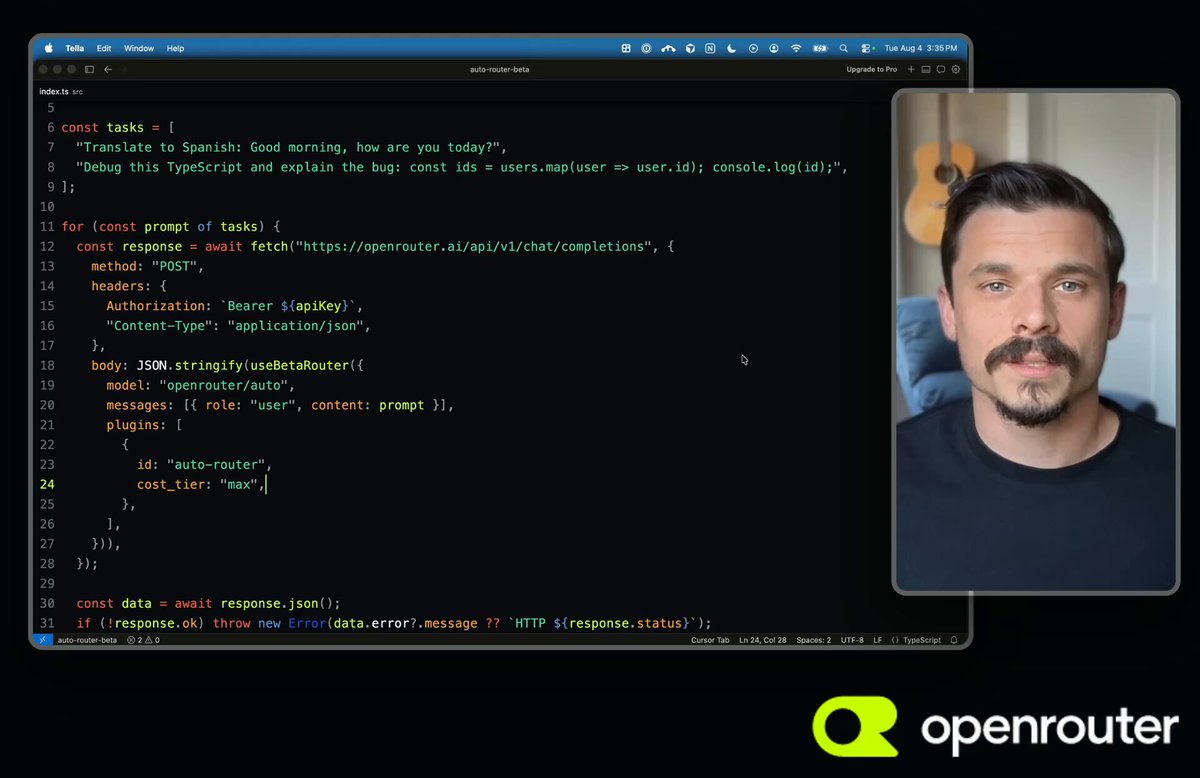
OpenRouter now runs inside @render Workflows. Stop putting LLM batches in your web service. Each prompt becomes its own task run, queued, retried, and fanned out by Render, with the model call routed by OpenRouter.

A web service has to hold an HTTP request open for the whole batch. A Workflow task keeps running after that request ends, retries on its own, and fans out one run per prompt, so a single slow call never blocks the rest.
Render provisions compute for those runs on demand and deprovisions it when they finish, so the fan-out needs no pre-provisioned worker pool.
Each run calls Auto Router with openrouter/auto, and every result keeps completion.model, so you can see which model OpenRouter picked for each prompt. One caveat worth knowing: a retry can repeat a billable call if the first request succeeded but the task failed before returning, so add idempotency for production side effects.
Context
Running a batch of model calls as background tasks lets the work continue after the initiating web request ends. In OpenRouter's integration with Render Workflows, each prompt gets a separate task run. Render handles queuing, retries and compute allocation, while OpenRouter selects and calls the model. A slow or retried prompt can therefore leave the other runs free to proceed. Integration guide.
Retries still need care around charges and external actions. The launch thread notes that a model request can succeed before its enclosing task fails, causing a retry to make another billable call. Actions performed by the task need duplicate protection when repeating them would have consequences. Launch thread.






Checking sign-in…
Loading comments…