Step 3.5 Flash: 196B MoE open weights built for agent workloads
- Source
- x.com
- Date

⚡️ Step 3.5 Flash is coming: Fast Enough to Think. Reliable Enough to Act! We’re dropping our most capable open-source foundation model yet. Frontier reasoning meets extreme efficiency. It leverages a sparse Mixture of Experts (MoE) architecture, 196B total → 11B active. Key Capabilities: ✅Reasoning at Speed: MTP-3 powered throughput at 100–300 tok/s (350 tok/s peak for single-stream coding tasks). ✅Agentic Power: ⚡️ 74.4% SWE-bench Verified ⚡️ 51.0% Terminal-Bench 2.0. Proven stability for complex, long-horizon tasks. ✅256K Efficient Context: 3:1 SWA ratio + Full Attention. Massive datasets or long codebases support with minimal overhead. Consistent performance, hybrid efficiency. ✅Local-First Deployment: Optimized for Mac Studio M4 Max, NVIDIA DGX Spark. Secure, private, and frontier-capable. Your data, your hardware, your agent. You can try Step 3.5 Flash right now: 👉 OpenRouter: https://t.co/MRDG3R4F64 👉 GitHub: https://t.co/qqmpslxK9t 👉 HuggingFace:https://t.co/y70Qzsc8DE 👉 Blog:https://t.co/rMH67kYmvA 👉 ModelScope: https://t.co/T4W7we5GEr 🌌 The Next:Step 4 training is officially LIVE! We're calling on the world's boldest builders to co-creat the Step 4 right now. Let's define the Agentic Era together! Join our Discord:
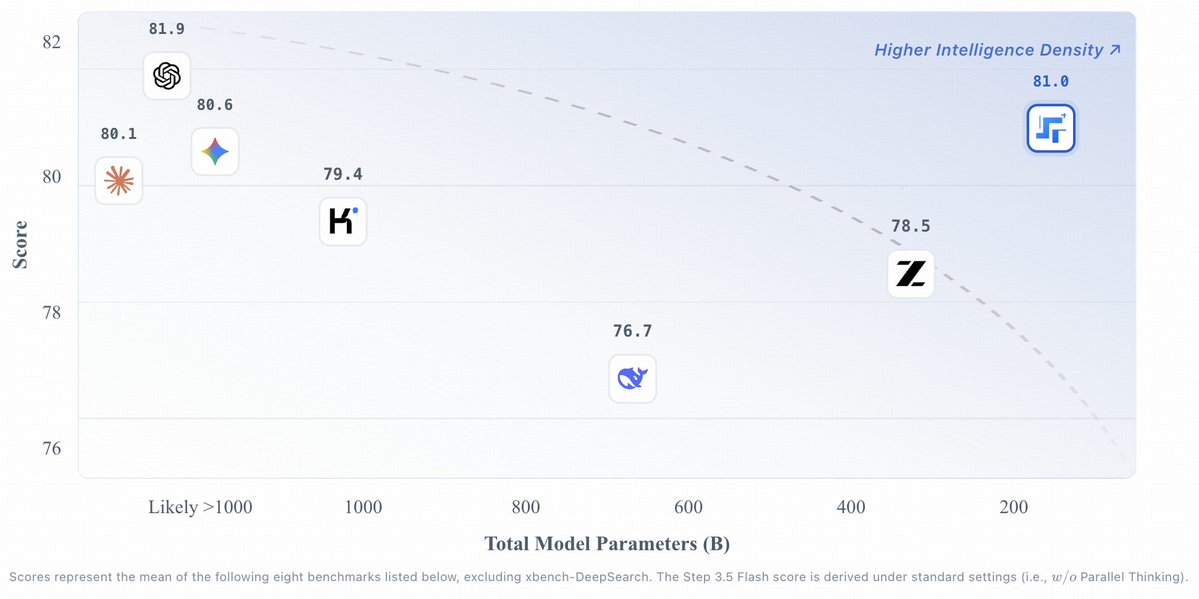
huggingface🤗 mtp3_bf16: https://t.co/0QIM32AlWz mtp3_fp8: https://t.co/5sIaLQ9Ekd int4: https://t.co/PfwfxQLGtK
Context
StepFun released Step 3.5 Flash as an foundation model built for agent and coding workloads. It uses a sparse (MoE) architecture with 196 billion total parameters but only 11 billion active per token, meaning most of the model's parameters sit unused for any given request, which is what lets a model this large run at the 100 to 300 tokens per second StepFun reports, with a 350 tokens per second peak on single-stream coding tasks.
StepFun reports 74.4% on , a benchmark of real GitHub issues that measures whether a model can produce a working code fix, and 51.0% on Terminal-Bench 2.0, which tests command-line agent tasks. Both figures are StepFun's own reported evaluation results rather than scores independently reproduced by a third party. The model also supports a 256K-token , and StepFun says it runs locally on hardware such as a Mac Studio M4 Max or an Nvidia DGX Spark, positioning it for on-device rather than only cloud deployment.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
- SWE-bench — The standard benchmark for AI coding agents: real GitHub issues from real repositories, scored by whether the agent's patch passes the project's own tests.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
 postStepFun Open-Sources Step Code, a CLI Coding Agent Benchmarked on Terminal-Bench
 postStepFun Open-Sources onPanda, Its Internal LLM Annotation and Debug Tool
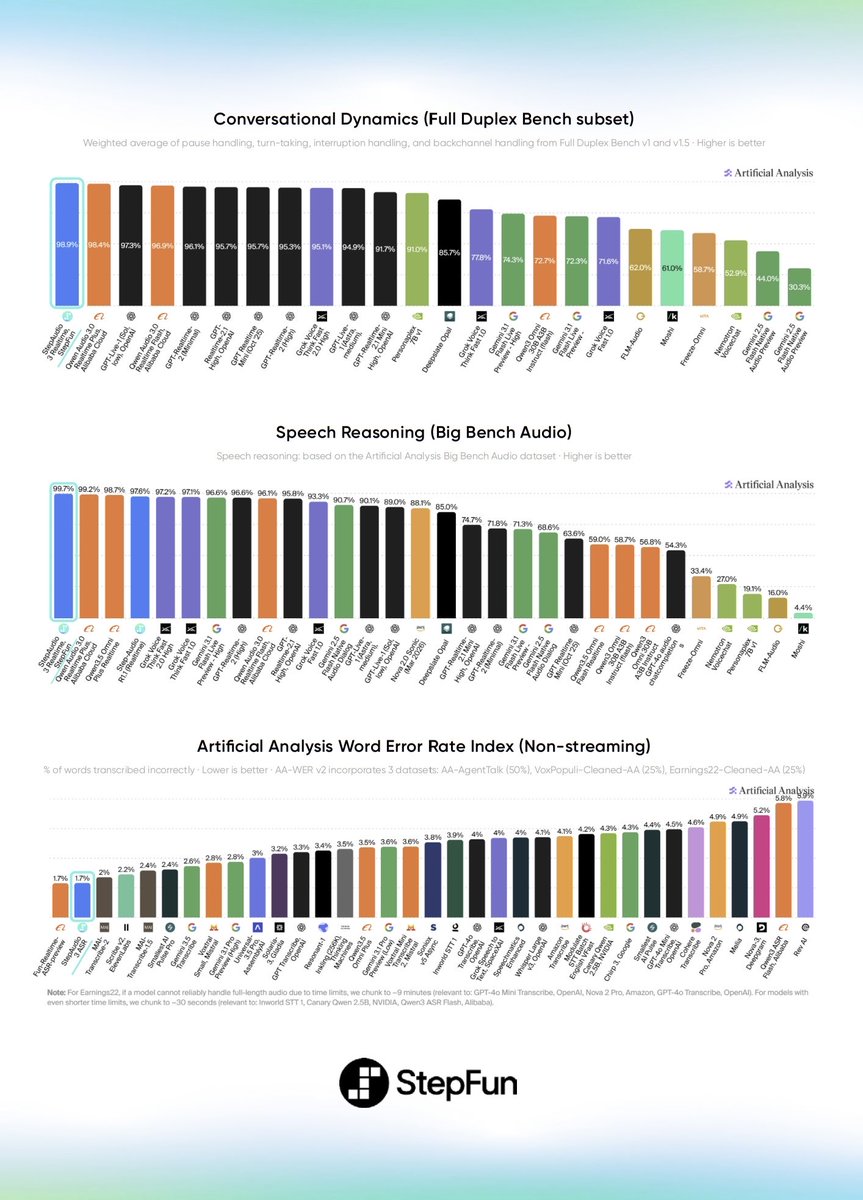 postStepFun debuts StepAudio 3 voice model family, tops real-time benchmarks
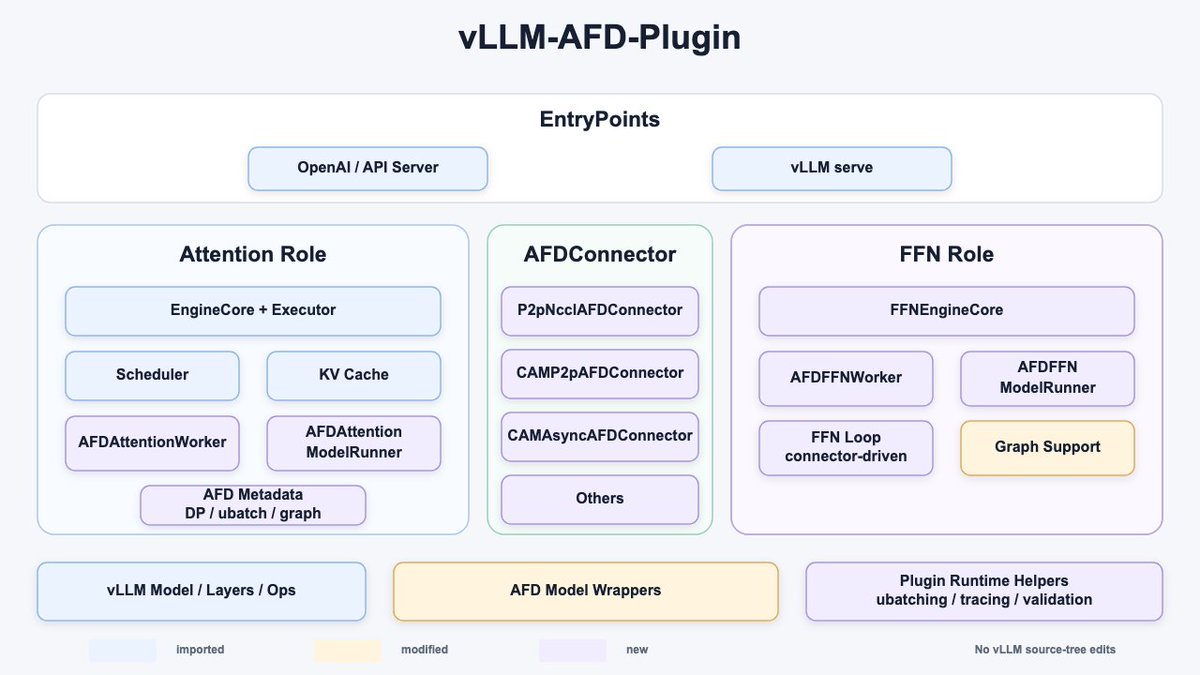 postvLLM gains an experimental Attention-FFN disaggregation plugin for MoE
Checking sign-in…
Loading comments…