Run fast, private agents on-device with LFM2.5-24B-A2B
- Source
- huggingface.co
- Date
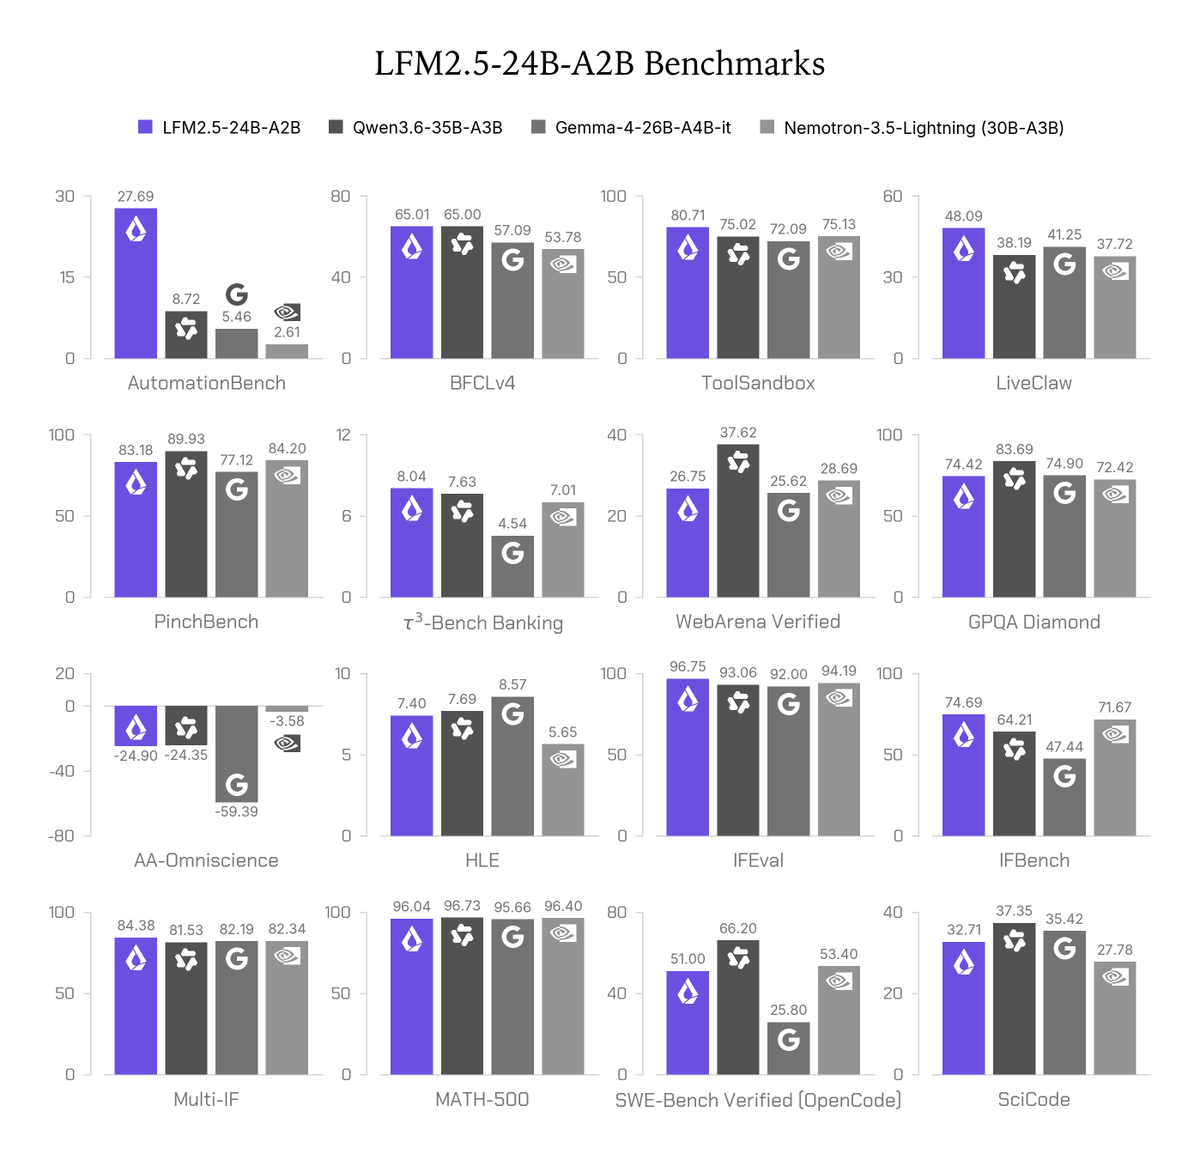
Liquid AI's new model targets multi-step tool use inside agent harnesses on local hardware. It activates only 2B of its 24B parameters per token, supports a 131K context window, and ships both base and post-trained weights on Hugging Face. Liquid reports 184 tokens per second on an M5 Max and says the model works inside popular agent harnesses. The company also reports strong agentic benchmark scores, which have not yet been independently reproduced. The practical point is the active-parameter count: a 2B-active model leaves room for long context and continuous operation on a laptop, which makes private or offline agents more realistic. Test it on your own tool-calling traces before relying on the vendor numbers.
Context
Liquid AI presents LFM2.5-24B-A2B as a for agents running on local hardware. Its release article describes 24 billion learned parameters, with only 2 billion active for each generated text unit. Selecting part of the model at each step is intended to reduce computation while retaining a larger pool of learned capabilities.
The release also expands the from 32,000 to 131,000 text units, allowing more material within one interaction. Liquid's own comparisons show strengths in and instruction following, while larger competitors retain advantages on several coding and knowledge tests. The evidence supports a targeted local-agent option, with workload-dependent tradeoffs.
- reasoning model — A model trained to think — generating extended internal reasoning before answering — trading time and tokens for accuracy on hard problems.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- tool use — A model's ability to call external functions — run code, search the web, edit files — instead of only generating text.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.

Checking sign-in…
Loading comments…