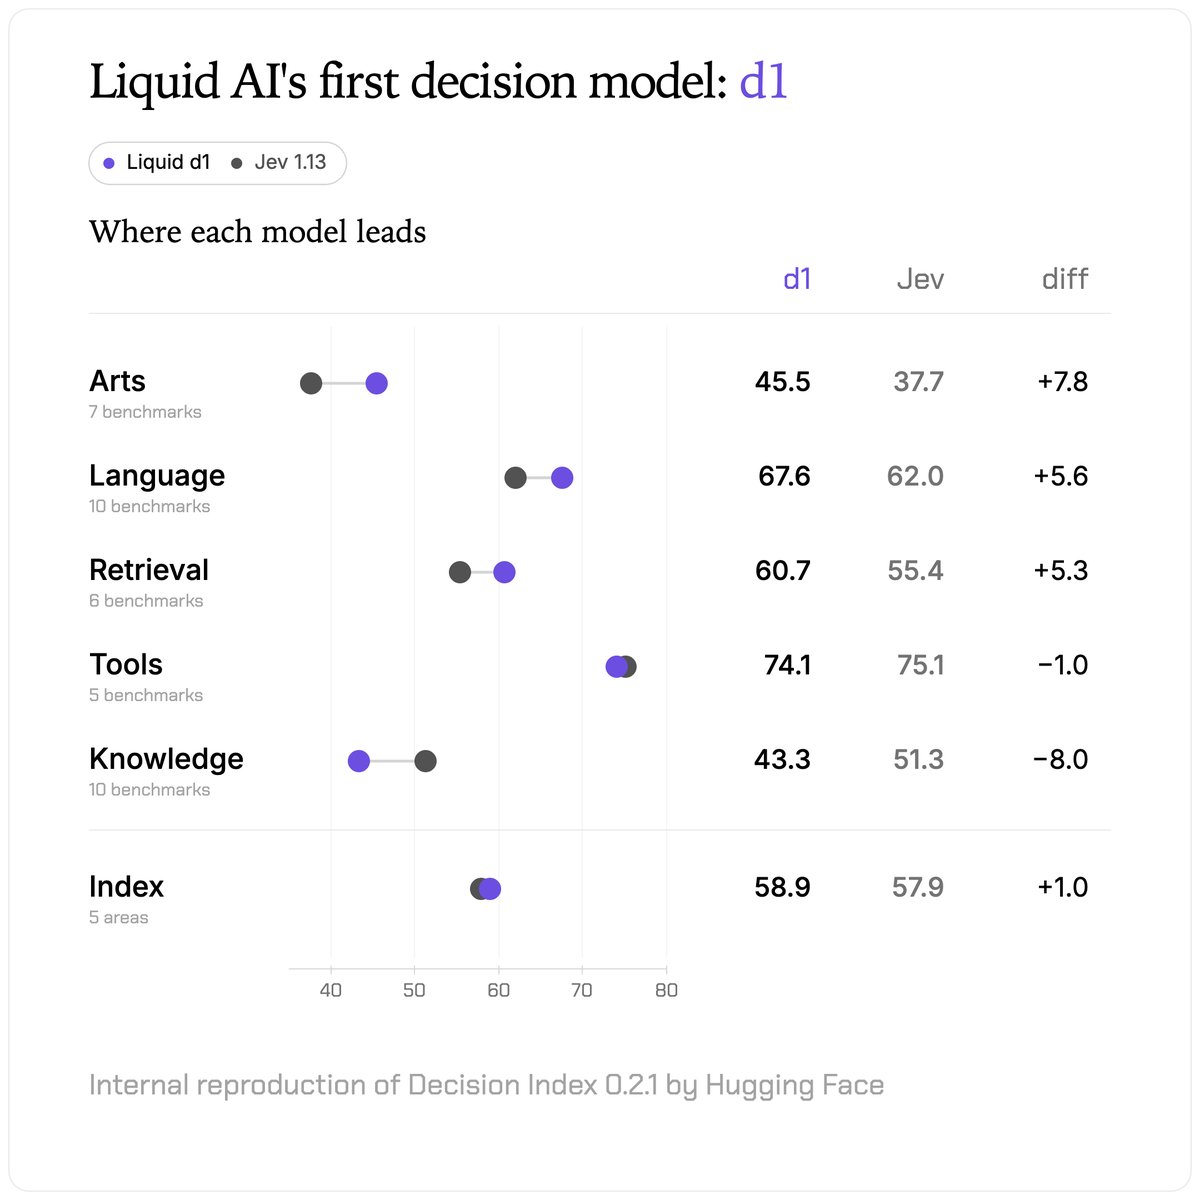
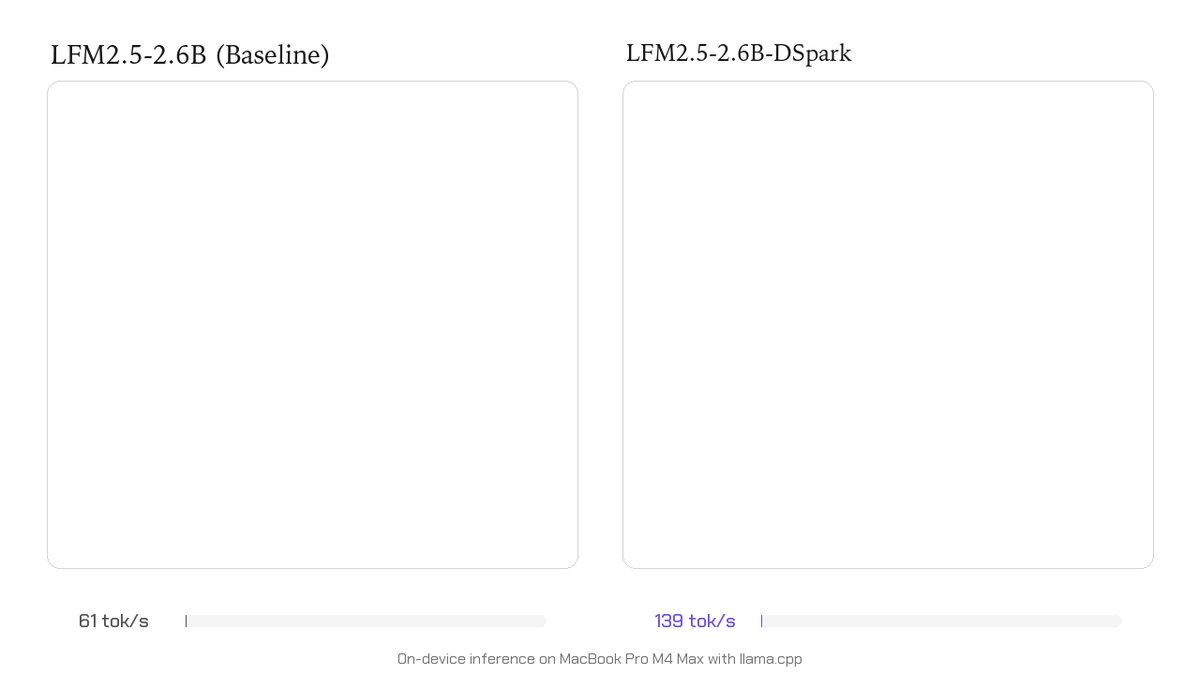
It lets developers run capable tool-calling agents fully on-device (phones/laptops) at up to 220 tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition →/s while matching or beating models 4x larger on agentic benchmarks, cutting cloud dependency and latency for AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition → workflows.
Terms in this piece · Glossary
LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
tool use — A model's ability to call external functions — run code, search the web, edit files — instead of only generating text.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
Key quotes
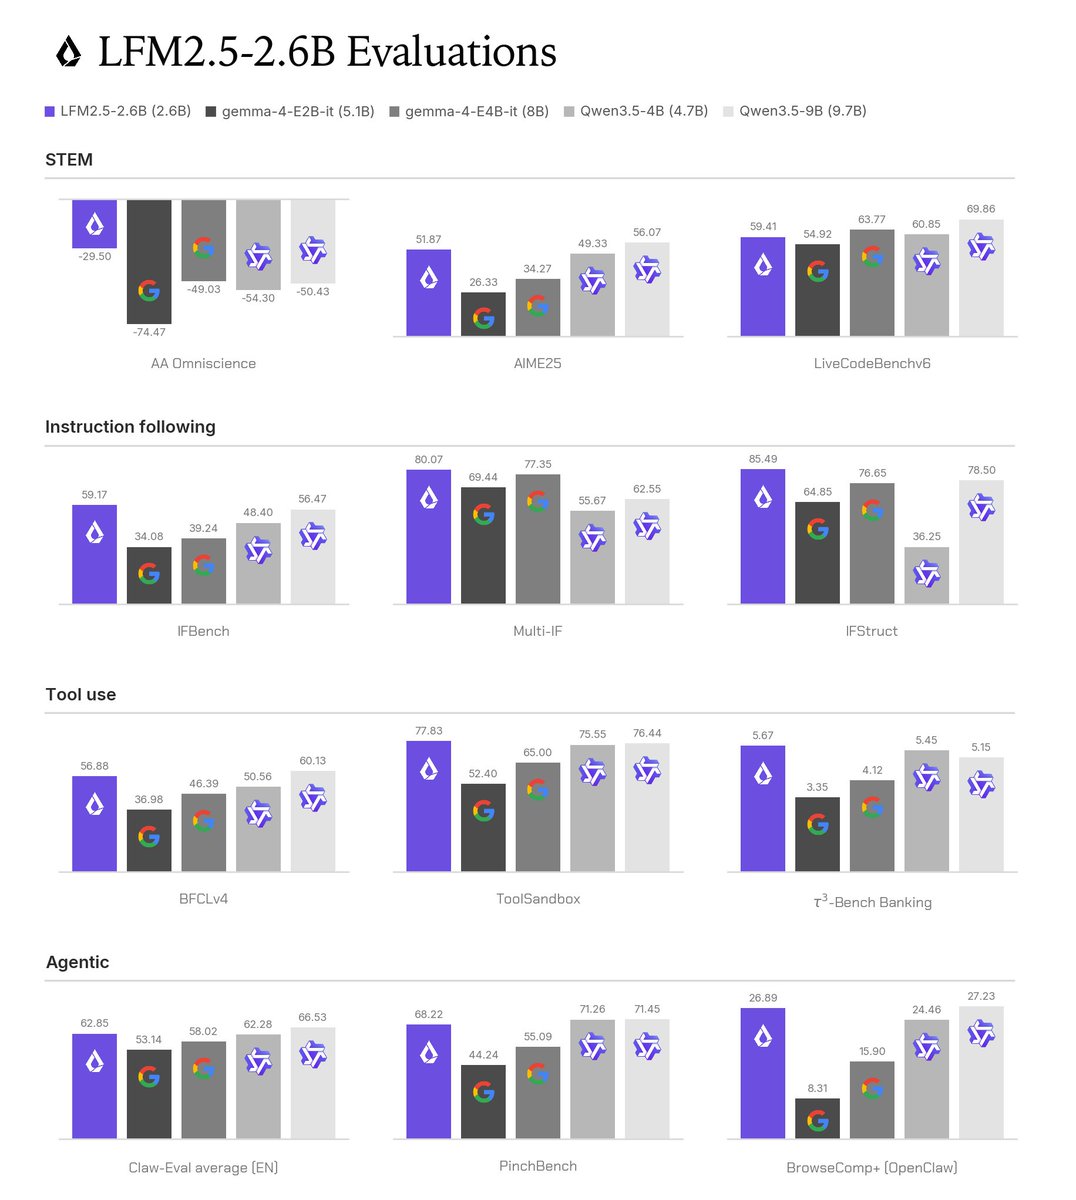
“It supports tool calling and multi-step workflows while staying small and fast enough for everyday hardware, from laptops to phones.”
“LFM2.5-2.6B is pre-trained on ~34T tokens, with a mid-training phase that extends the context window to 128K.”
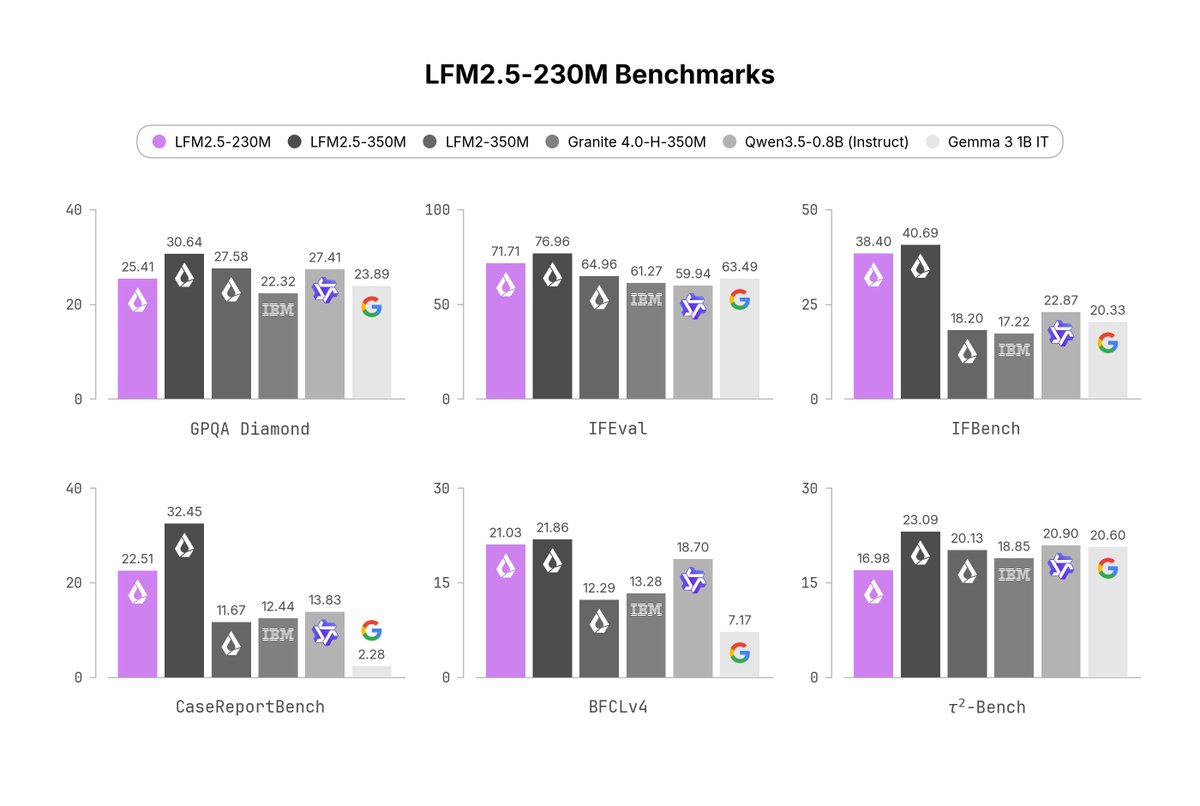
“It is the smallest model in the group, yet it competes with and often beats the rest.”
“Coding is the one place the larger models keep a clear lead, so reach for something bigger there.”