LFM2.5-Encoders for Fast Long-Context Inference on CPU
- Source
- huggingface.co
- Author
- Liquid AI
- Date

Context
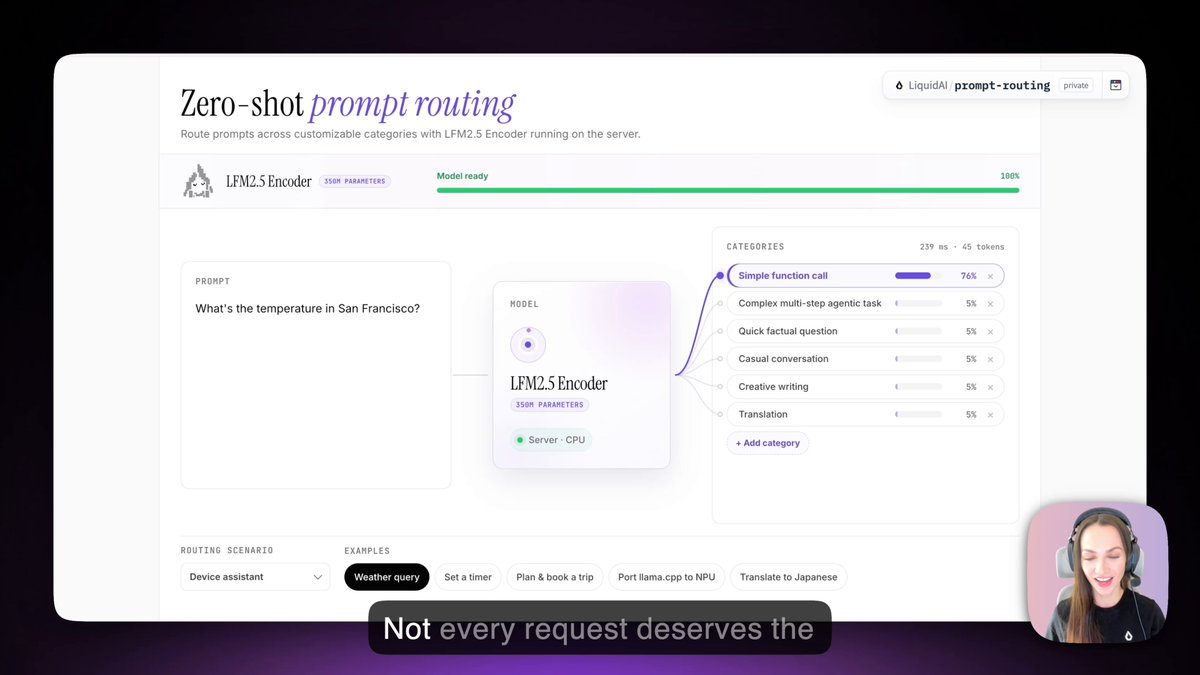
Liquid AI's LFM2.5-Encoders are models developers can adapt to classify documents, route requests or identify information within text. Their design lets each piece of text use surrounding on both sides. They accept up to 8,192 at once, supporting tasks that need to examine long passages. The release article explains their training and intended uses.
The reported quality results come from each model separately for each task. They therefore support evaluating these models as adaptable components for a particular workload. A developer still needs to train and assess the relevant task behavior rather than assume that the base model already performs every demonstrated application.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- fine-tuning — Taking a trained model and training it a bit more on your own examples so it gets better at one specific job.
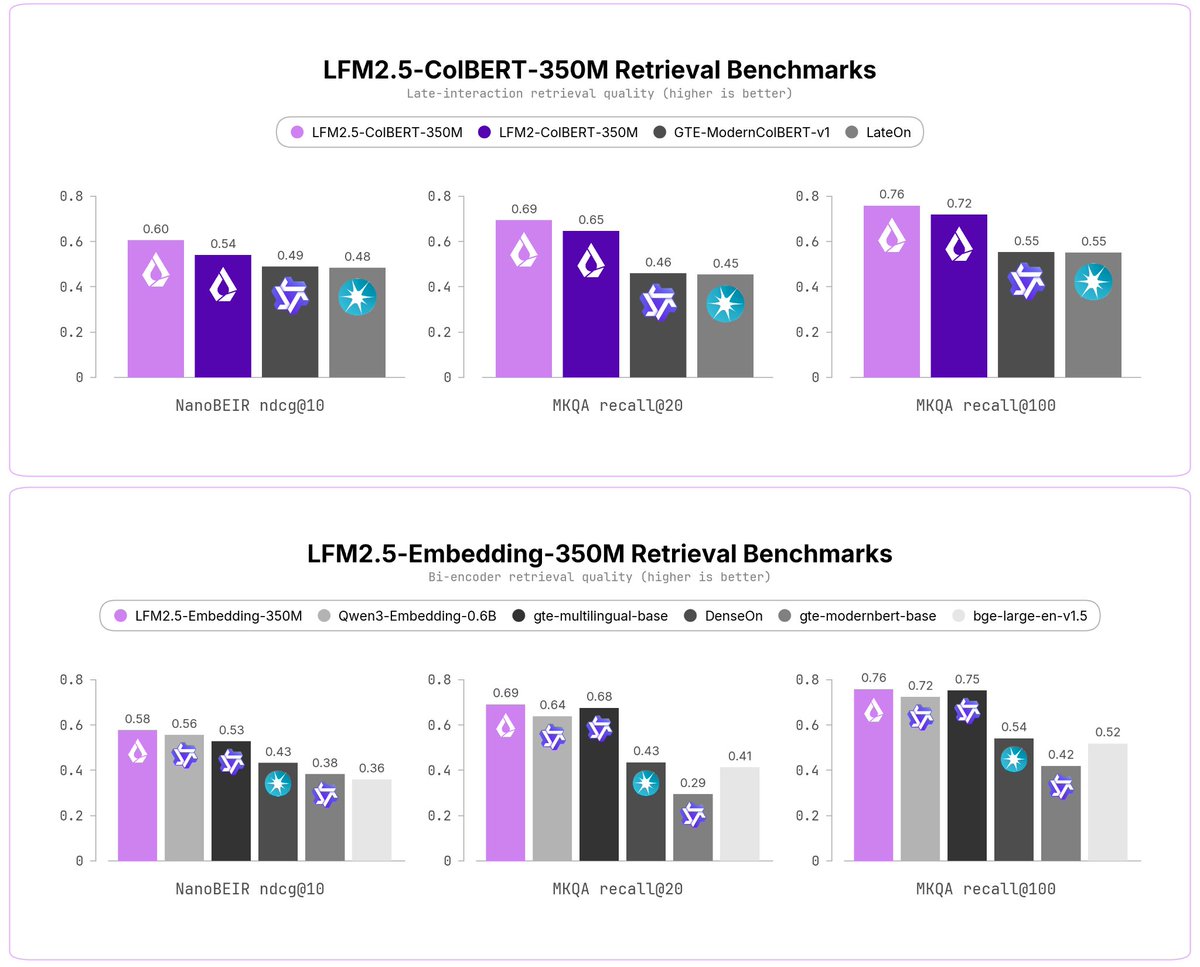
“They match the quality of larger models but stay fast as inputs get longer. This means you can run document-scale jobs on the hardware you already have, even on CPU.”
“LFM2.5-Encoder-350M ranks fourth of the 14 models. The three ahead of it are all larger, including a 3.5B model nearly 10 times its size.”
“At 8,192 tokens, ModernBERT-base takes over a minute and a half per forward pass versus about 28s for LFM2.5-Encoder-230M. This is about 3.7x faster.”
“For developers, that means you can scan or classify a full contract, transcript, or long support thread in under 30 seconds on a laptop CPU.”
Checking sign-in…
Loading comments…