Ai2's TutorMoments eval: detailed prompts beat 'tutor well'
- Source
- tutormoments.allen.ai
- Author
- allen_ai
- Date
Context
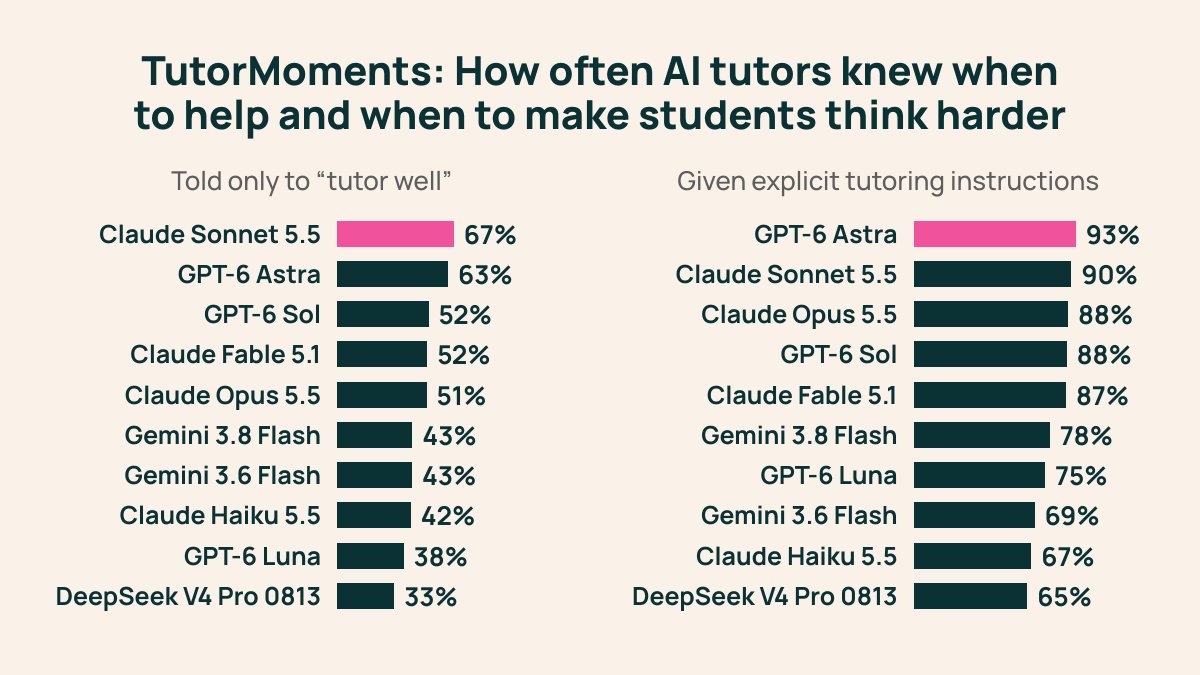
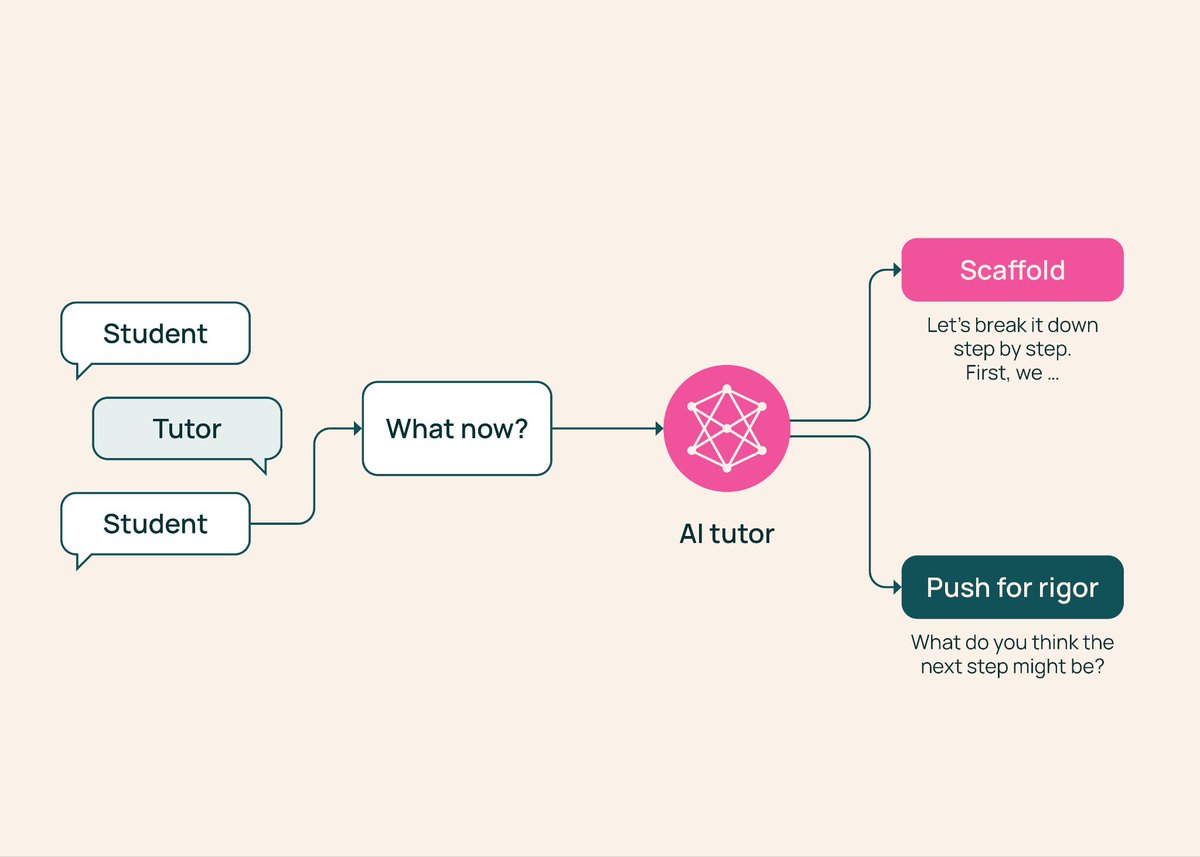
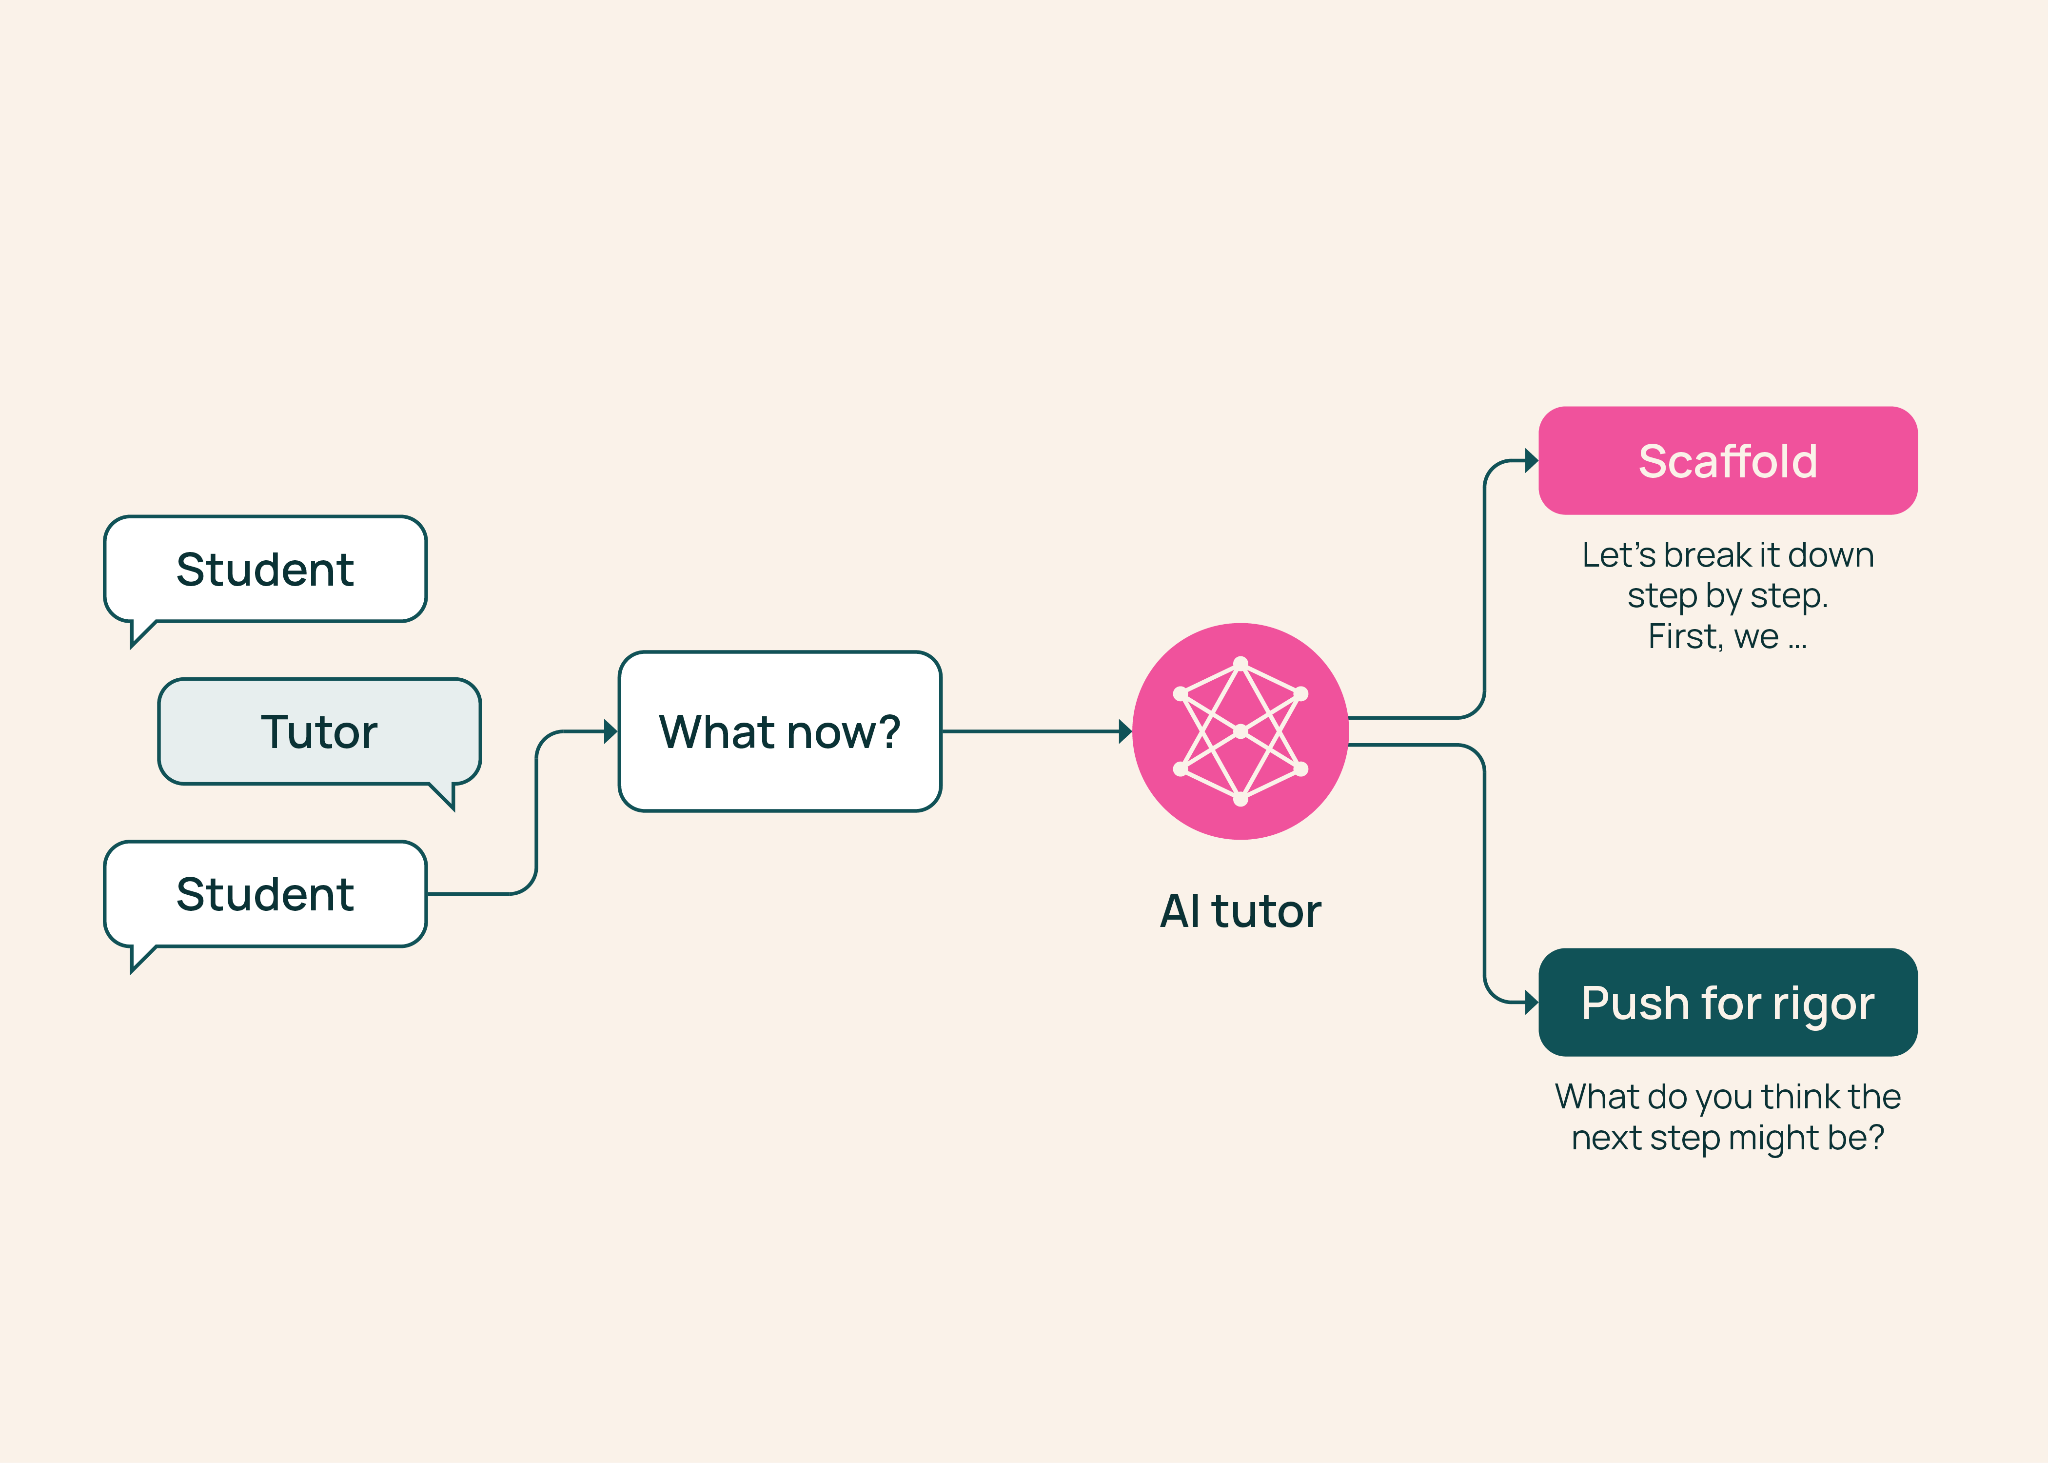
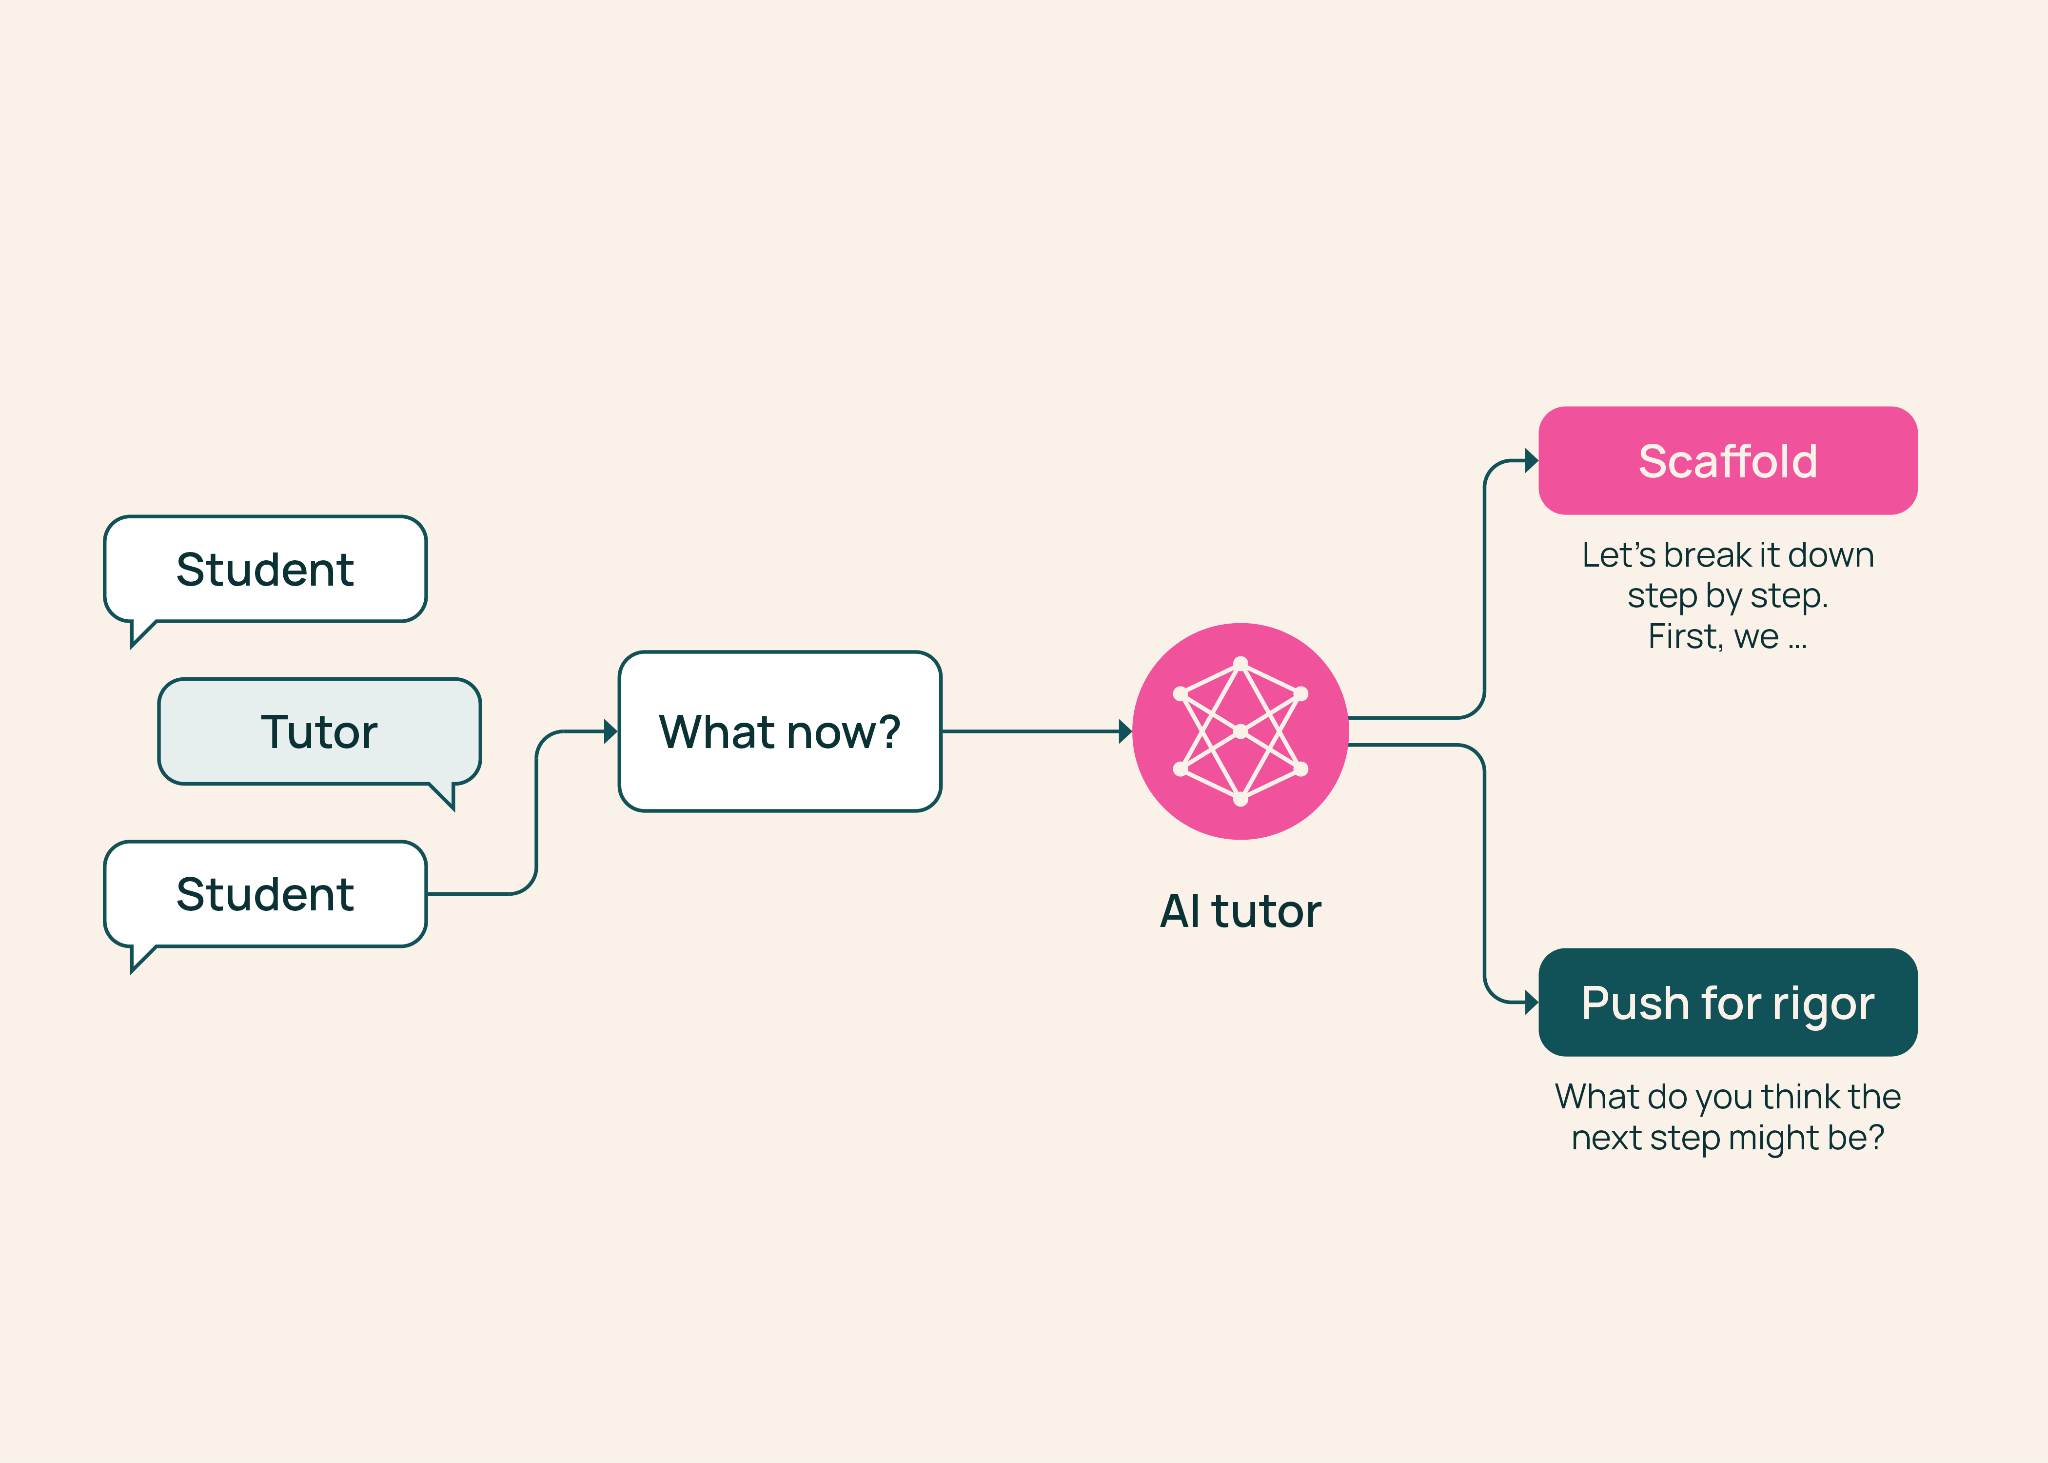
Ai2's TutorMoments tests one tutoring judgment: at a given moment, does the student need the problem made more accessible, which the calls scaffolding, or a push to do harder thinking, which it calls a push for rigor? Ai2 finds that language models told only to "tutor well" tend to over-help, giving too much support and rarely pushing. A prompt that spells out the trade-off between the two lifts every score, but models still differ widely in how reliably they make that shift. Ai2's announcement puts the headline result more loosely: in general, models scored better with detailed prompts.
The test replays 520 key moments that expert teachers picked out of real math tutoring transcripts, split evenly between moments that called for scaffolding and moments that called for rigor. Several teachers labelled each moment, and the majority label becomes the answer a model is scored against. A score is the share of moments where the model did what the moment called for without over-scaffolding, so it measures agreement with teachers' judgments, not what students went on to learn. Ai2 introduced the framework in an earlier post, and the new site adds results for newer models over the full set of moments.
Human tutors at the same moments score 0.458 for appropriate scaffolding and 0.182 for appropriate rigor, and Ai2 treats them as a naturalistic reference rather than a ceiling, because annotators deliberately chose moments where tutoring could have gone better. The human comparison is still telling on one measure: no model changes its moves between scaffolding and rigor moments as much as the human tutors do. With the detailed prompt, models shift toward asking students to justify their answers, while humans spread their choices across more strategies, including stepping back and letting the student work.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Checking sign-in…
Loading comments…