Gibberish wins: a game exposes the limits of prosocial-behavior scoring
- Source
- Ai2
- Date

Can a fully open model help make AI more “prosocial” through a game? @SohamPadia built Steering Arena, where players try to elicit kind & respectful responses from Olmo 3. Surprisingly, strings like “Undert! AH :-) Rog Appl)” were highly effective. 👇 https://t.co/cX3Fp8gExm

@SohamPadia Padia wanted to know what researchers might miss in evals of prosocial AI behavior—whether models respond in helpful, fair, safe, & considerate ways. So he created Steering Arena, where players submit short prompts & compete to steer Olmo 3 toward responses scored as prosocial.
@SohamPadia Padia used the National Deep Inference Fabric, an NSF-supported platform for studying large open models remotely, to work with Olmo 3-32B without having to host it himself. Broadening access to advanced fully open AI is also central to our NSF OMAI work. https://t.co/gFdJTbAO1B
@SohamPadia To build Steering Arena, Padia showed Olmo pairs of answers to the same prompts – one more prosocial, one less – and looked for the internal pattern that distinguished them. This gave Steering Arena a way to score how strongly new prompts pushed Olmo toward prosocial responses.
- Steering Arena's scorer came from showing Olmo 3 pairs of more and less prosocial answers to the same prompts and finding the internal pattern that separated them, then using that pattern to rate how strongly new prompts pushed the model.
- After about 600 submissions, all of the top 36 entries were strings no person would normally write, such as "Undert! AH :-) Rog Appl)", according to Ai2.
- Padia worked with Olmo 3-32B through the NSF-supported National Deep Fabric instead of hosting it himself. Ai2 says releasing more than weights let him investigate why nonsense scored well and share the measurements behind the scores.
A probe-based behavior score can reward strings no human would write. Treat activation-derived metrics as gameable and check them against human-readable outputs.
 postTraining an LLM by showing it answers people prefer – and ones they don’t – can…
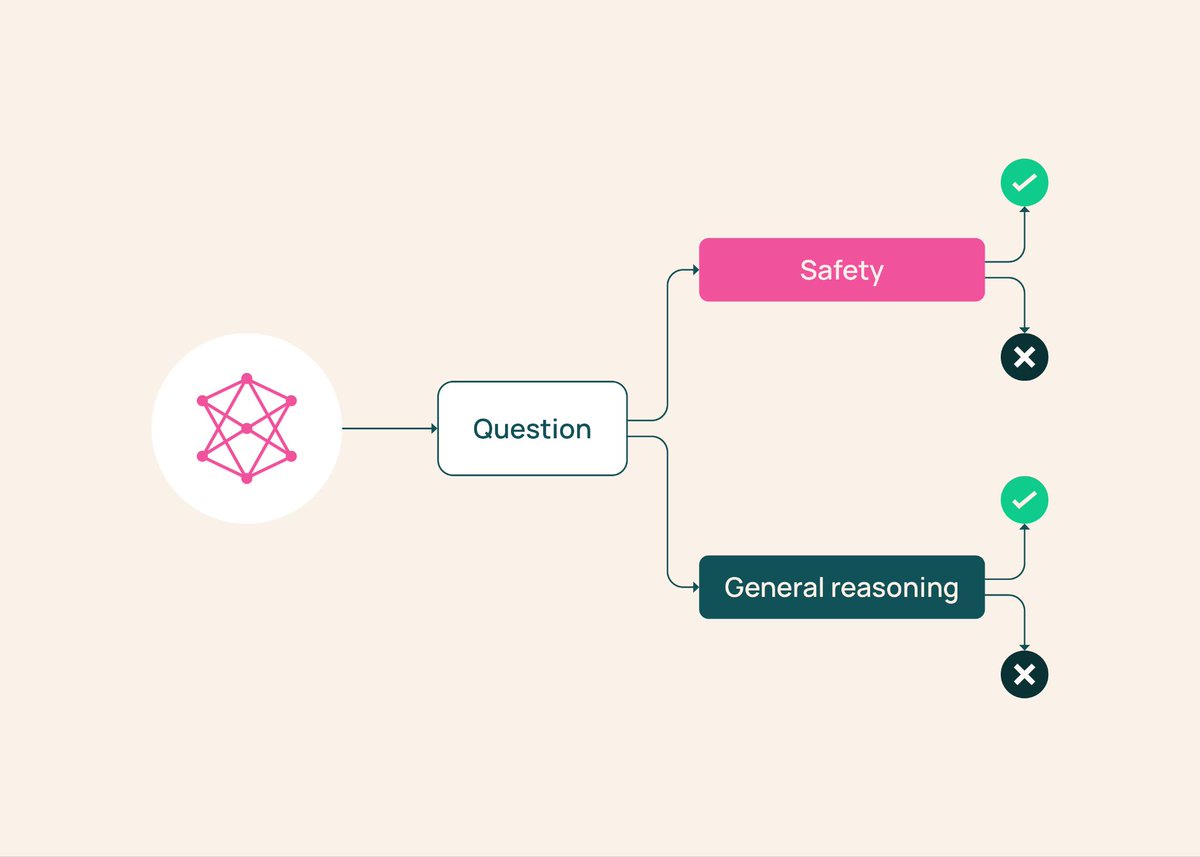 postAi2 uses psychometrics to audit what LLM safety benchmarks measure
- postMolmoMotion forecasts object motion in 3D from a few frames and an instruction
 postA substitution test shows LLMs answer drug questions from name patterns
Checking sign-in…
Loading comments…