attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Why it matters
Gives teams running long-context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition → Qwen3 models a drop-in sparse-attentionThe mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.Full definition → router that cuts decode cost across multiple tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → budgets without retraining the base model.
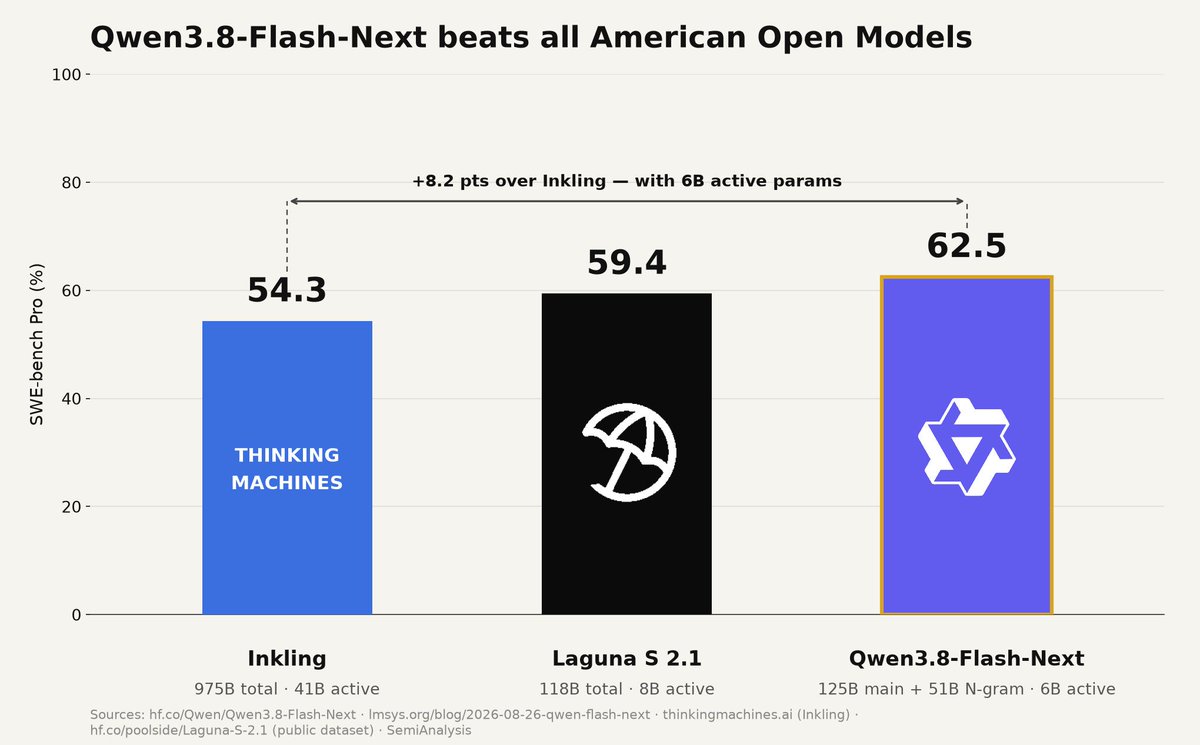 postInside Qwen3.8-Flash-Next: n-gram embeddings, gated residuals, sparse attentionSemiAnalysis
 articleExperiment with Qwen3.8-Flash-Next 176B Model on NVIDIA GB300 NVL72 for Agentic CodingMichelle Horton