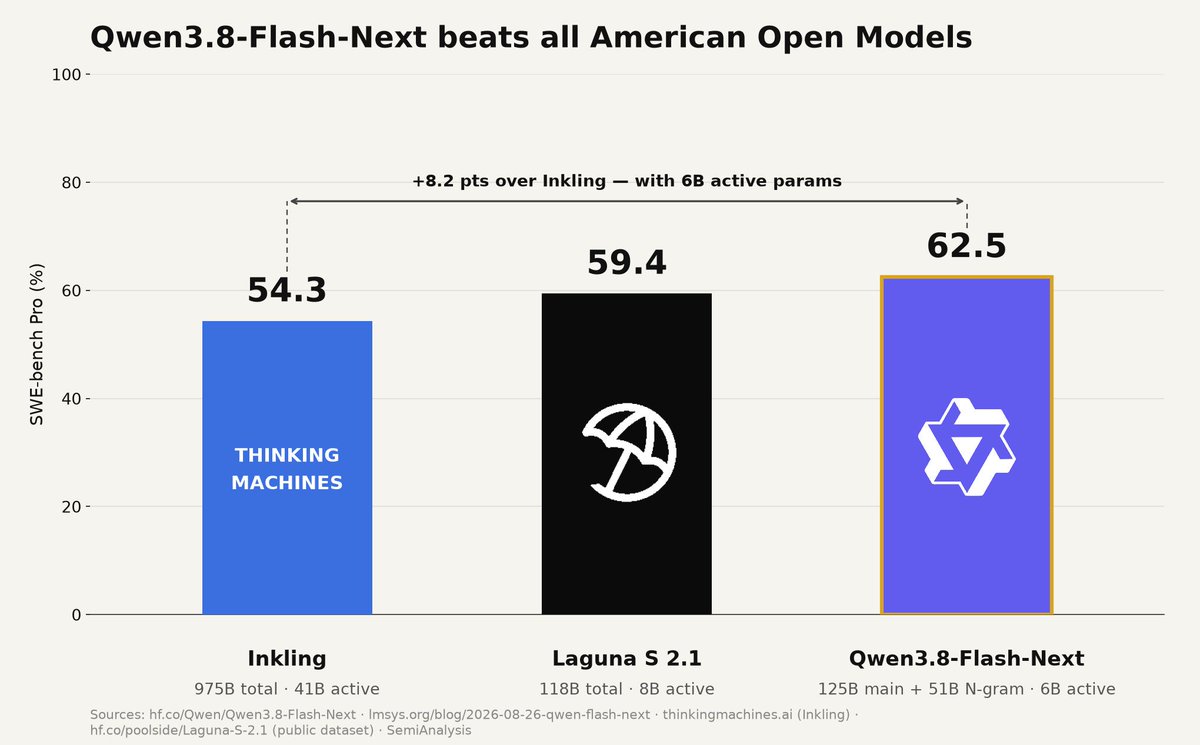
Experiment with Qwen3.8-Flash-Next 176B Model on NVIDIA GB300 NVL72 for Agentic Coding
Source
developer.nvidia.com
Author
Michelle Horton
Date
Why it matters
Concrete numbers for what block-level sparse attentionThe mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.Full definition → buys at million-token contexts, plus the serving paths — SGLang, vLLM, TensorRT-LLMA large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.Full definition →, NeMo — for running the model from workstation to rack scale.
Terms in this piece · Glossary
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.