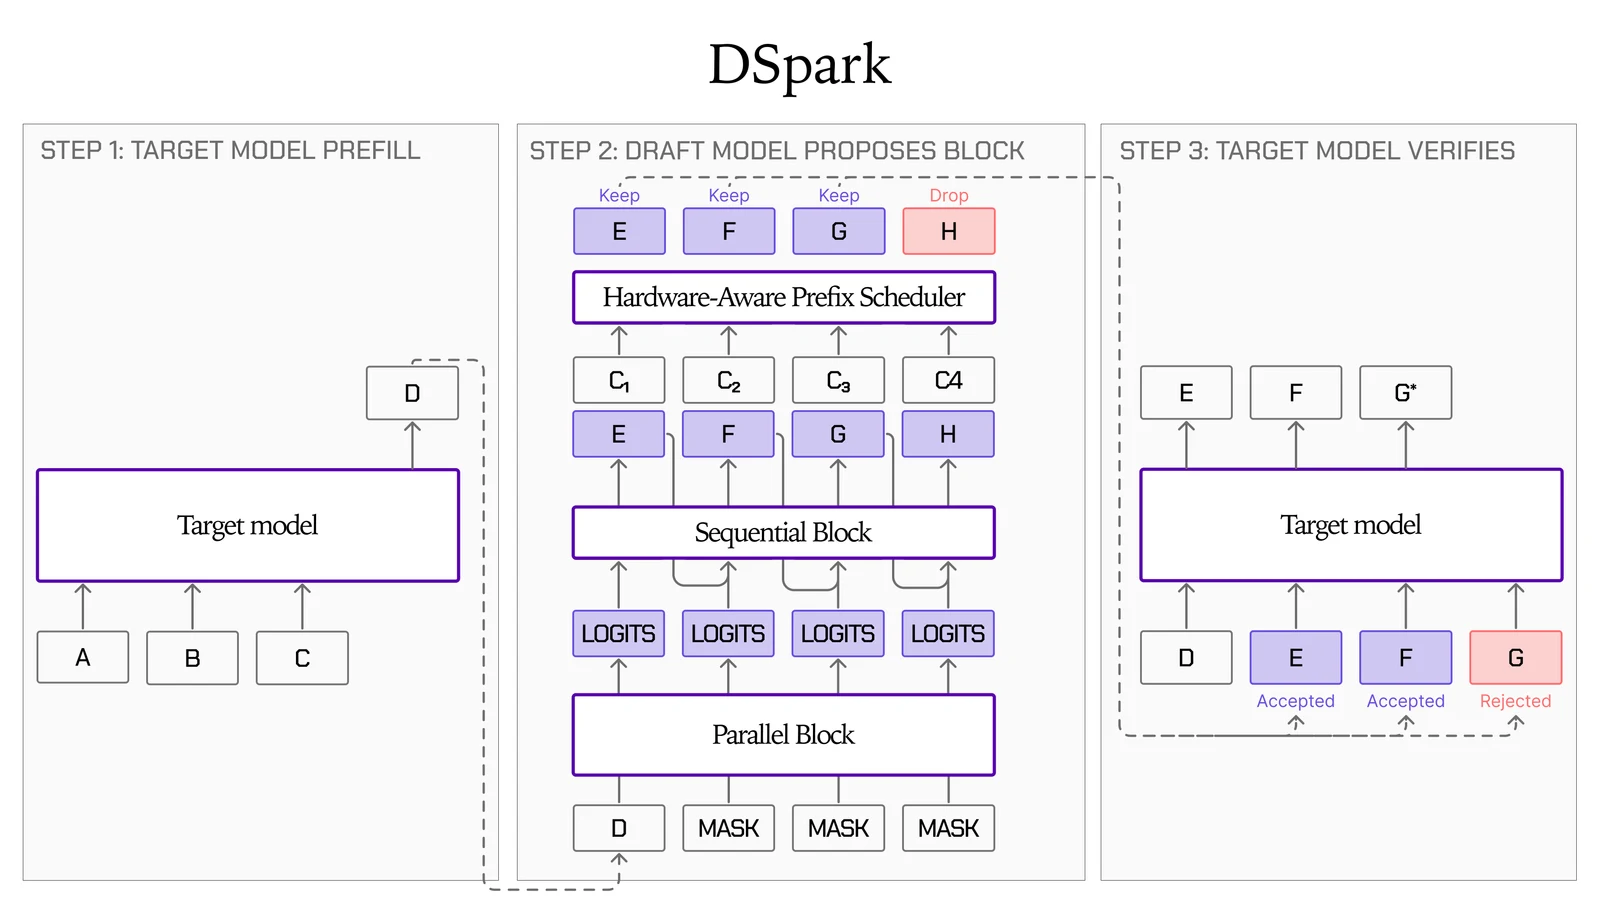
Liquid AI uses a small helper model to propose several pieces of text that an LFM2.5 model checks together. This applies the principle explained in earlier speculative-decoding research: checking several proposals can reduce sequential work. Liquid reports that its DSpark implementation preserves the target model's output under greedy decoding, which always chooses its highest-ranked next text unit.
The largest reported speedup, 3.18 times, came from LFM2.5-8B-A1B on MATH500 using an H100 GPU with one request at a time. That model averaged only 1.18 times faster on the tested M4 Max. Hardware and workload therefore determine how much the extra helper model saves.
Terms in this piece · Glossary
speculative decoding — A speed trick where a small model drafts several tokens ahead and the big model verifies them in one pass, often doubling generation speed.
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.