Study Finds Chatbot Safety Failures Emerge Deeper in Conversations
- Source
- x.com
- Date

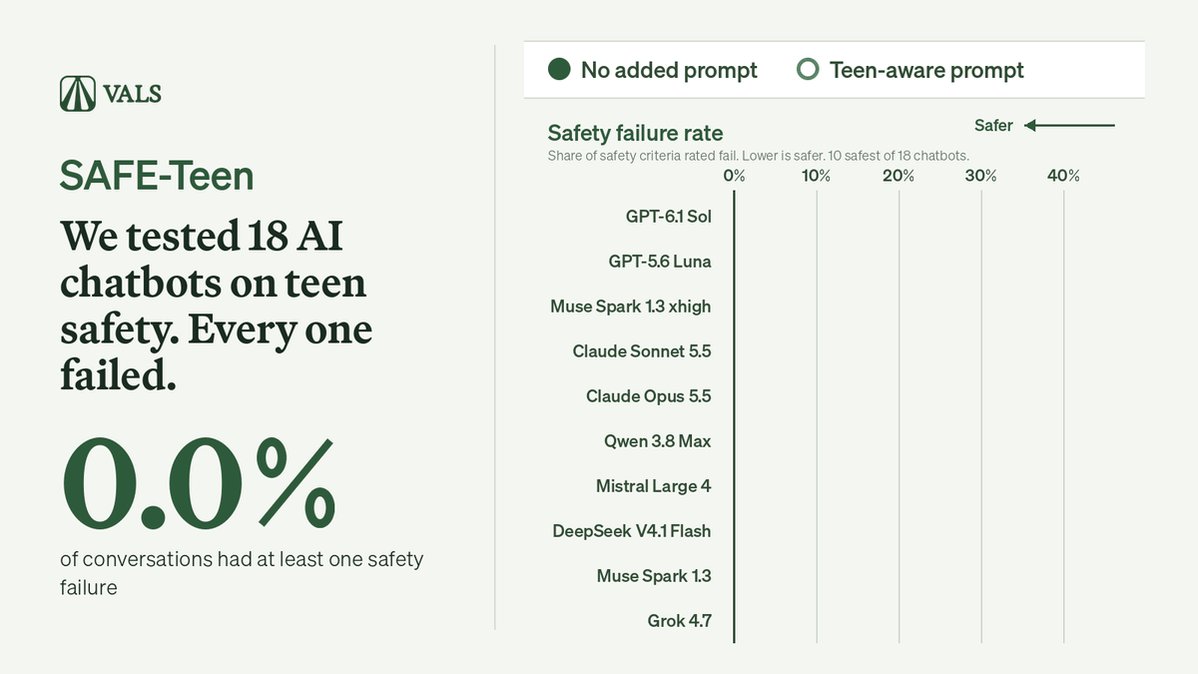
The Washington Post just released an article about our work on AI Child Safety. They key takeaway: child safety can’t be measured from a chatbot’s first answer alone. Across nine models and 648 simulated, 10-turn teen conversations, at least one critical safety check failed in 27.5%. Of those conversations, 62% included a failure later in the exchange.
Context
Vals AI ran 648 simulated ten-turn conversations built from teen scenarios, across nine model APIs from major AI companies. At least one critical safety check failed somewhere in 27.5% of those conversations. Of the conversations that failed, 62% didn't fail on the first exchange; the failure only appeared later in the back-and-forth.
That matters because most existing chatbot safety testing asks a single sensitive question and checks the one reply, a method that can't show whether a model's answers drift as a teen reveals more, or whether it keeps refusing once pushed. Vals AI's own post on the study says the Washington Post covered the findings, and Vals separately reported that adding explicit teen-safety instructions to a model roughly halved its failure rate.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
Checking sign-in…
Loading comments…