OpenAI's GPT-6 Astra on ARC-AGI-3
- Source
- arcprize.org
- Author
- Greg Kamradt
- Date
Context
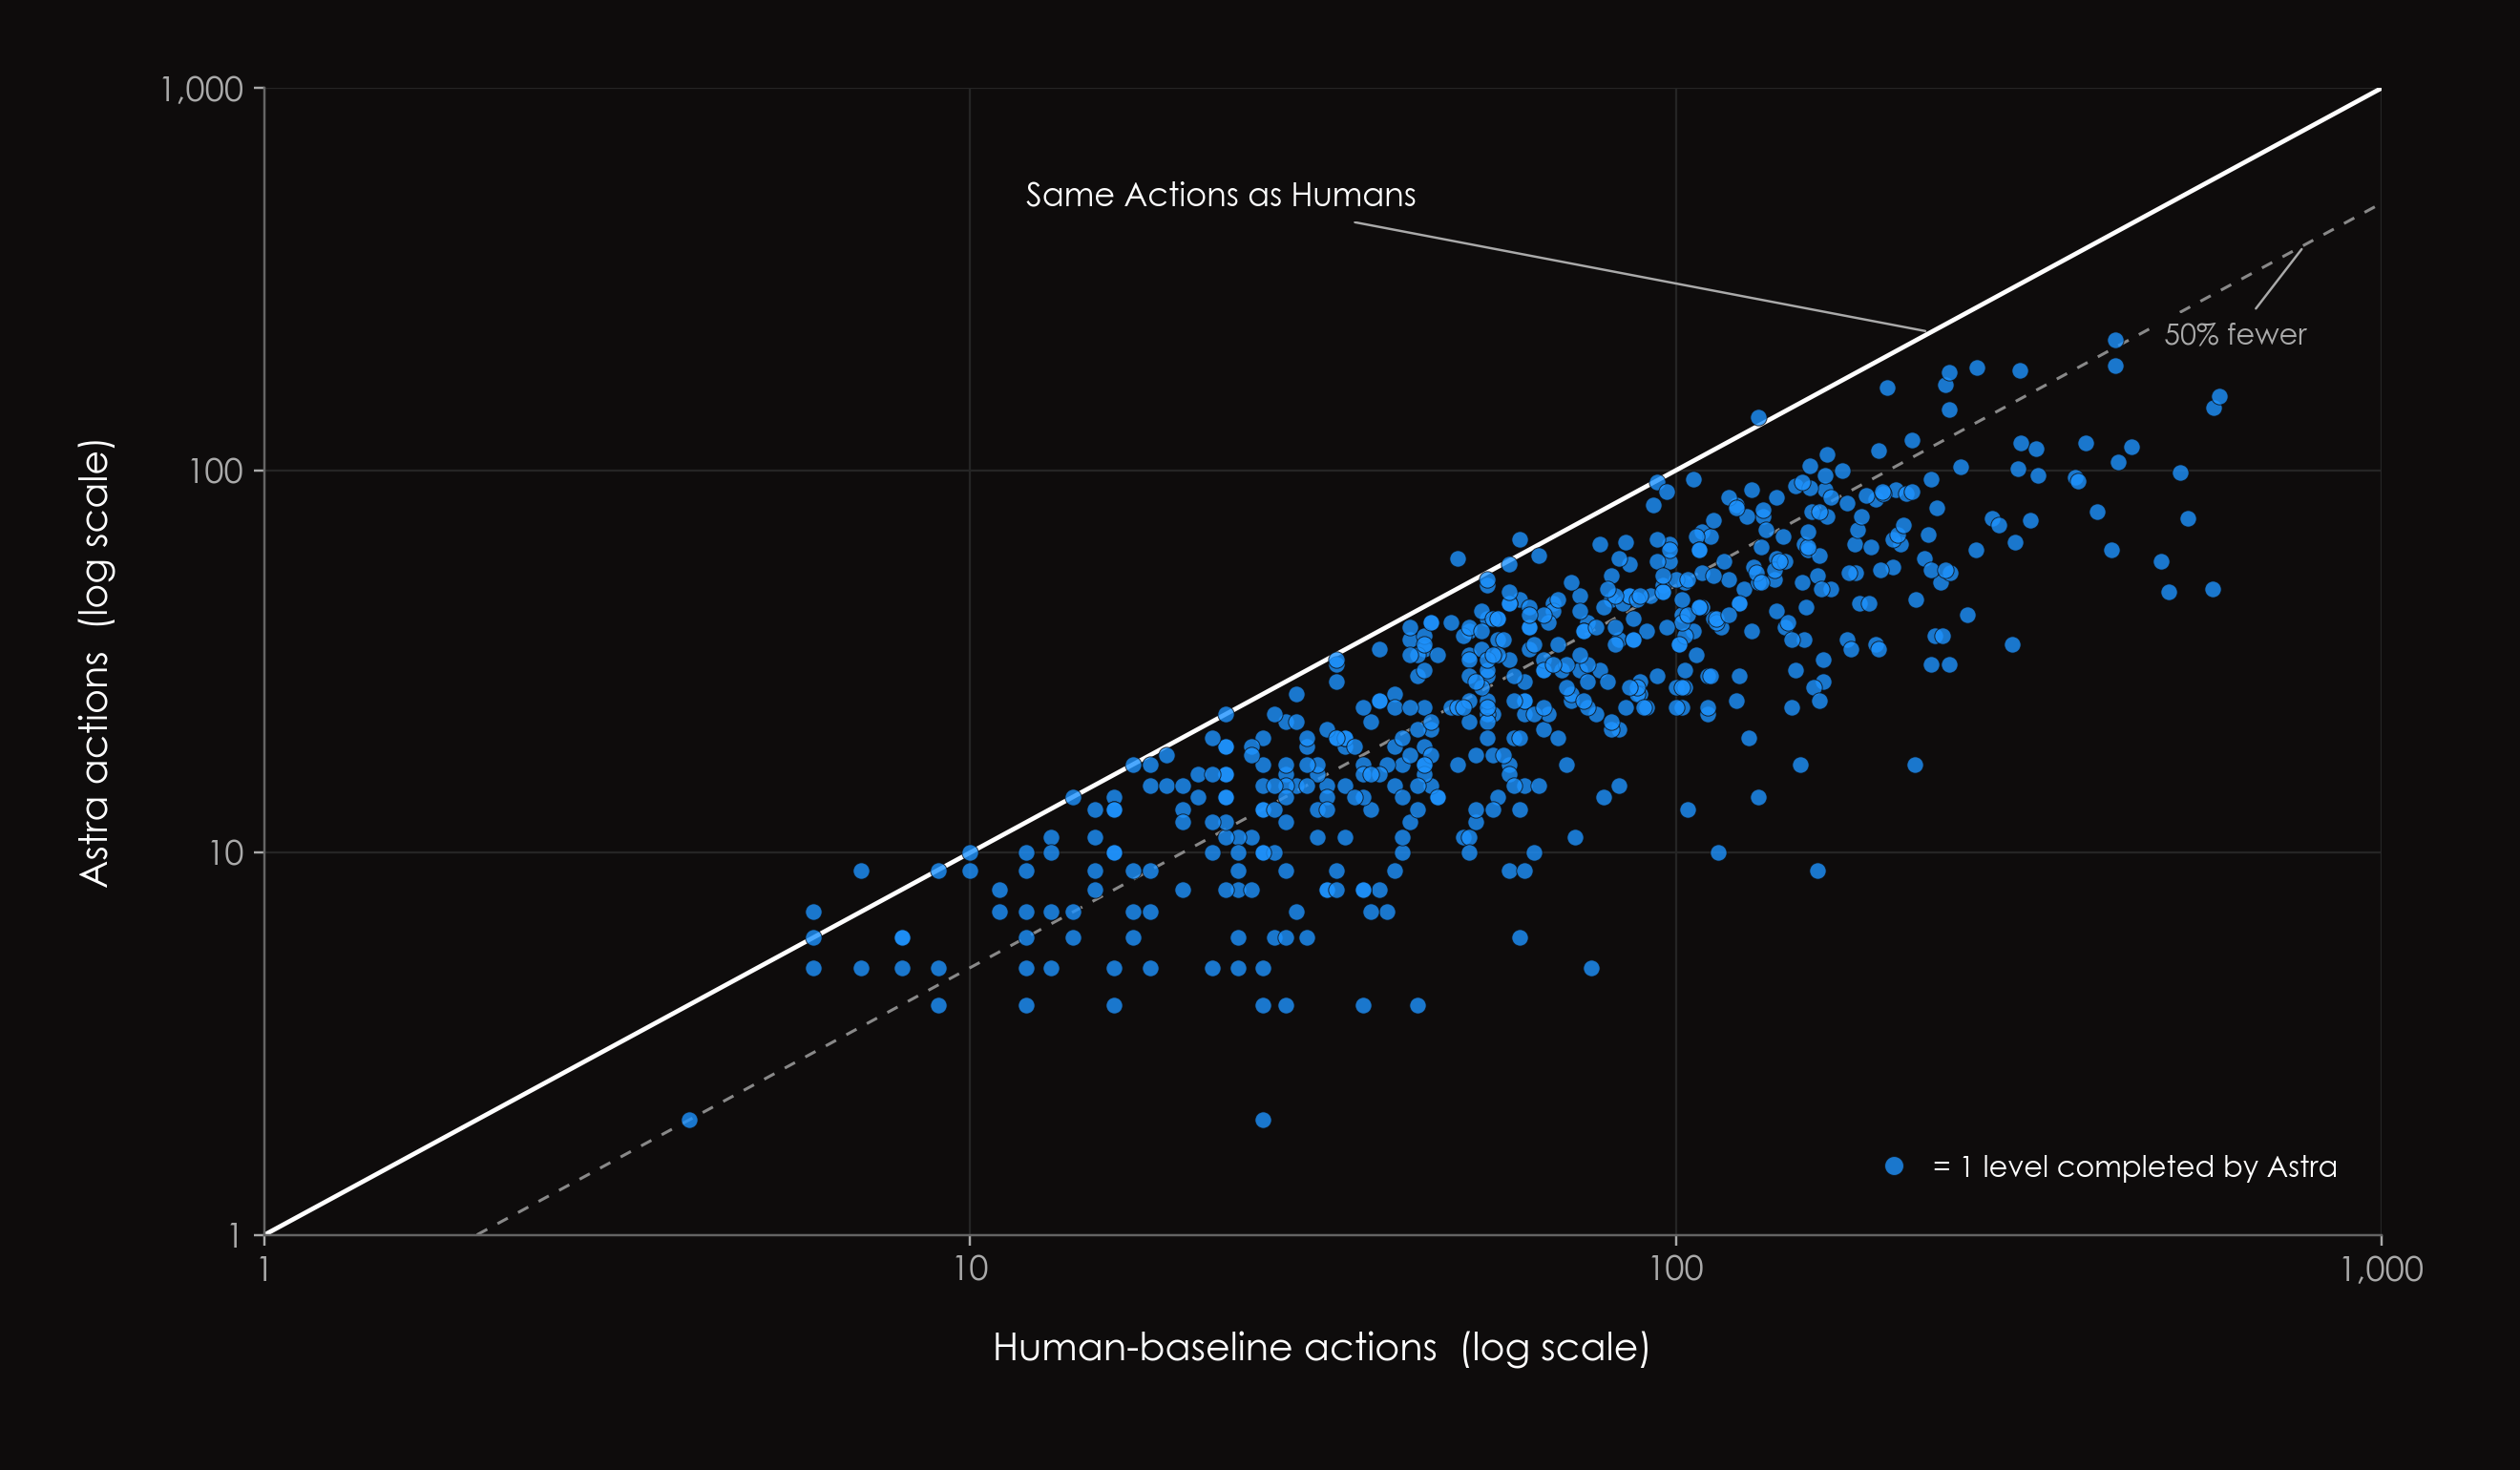
The software surrounding a model can change what its score means. ARC Prize's GPT-6 Astra evaluation tested OpenAI's model on ARC-AGI-3, a set of interactive puzzle games, under a common minimal interface and under an adapter that preserves the provider's reasoning state between requests. Its best observed score on the semi-private test set rose from 62.7% to 99.9% with the adapter.
The first setup asks how models compare with the same basic interface. The second asks what the model can achieve with its provider's -management features. That distinction matters when comparing scores: the adapter is part of the tested system. ARC Prize also separates runs with additional code-execution tools from its human comparison, and explicitly says success on these bounded games is not proof of general intelligence.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
Checking sign-in…
Loading comments…