Mistral Large 4 goes open weights, tops non-Chinese open models
- Source
- x.com
- Date
Mistral has published weights for Large 4, a mixture-of-experts model with 1.05T total and 52B active parameters, a 1M-token context window and image input. Artificial Analysis scores the high reasoning setting at 26 on its Intelligence Index v5, one point above the Preview and one point above Muse Spark Open, the best US-built open model. The final release uses 82K output tokens per index task, 39% fewer than the Preview, and its hallucination rate fell from 41% to 28%. Price dropped by about half to $0.70 input and $2.10 output per million tokens, so cost per index task fell 63% to $2.06. The gap to the leading Chinese open models remains: DeepSeek V4.1 Flash and GLM-5.3 score 6 points higher, and Large 4 reaches 15% on FrontierCode 2.0 against their 29% and 22%. On the Coding Agent Index it scores 48 in Mistral Vibe with about half the tokens GLM-5.3 uses. The MEOW license requires a commercial agreement for any model-as-a-service business.

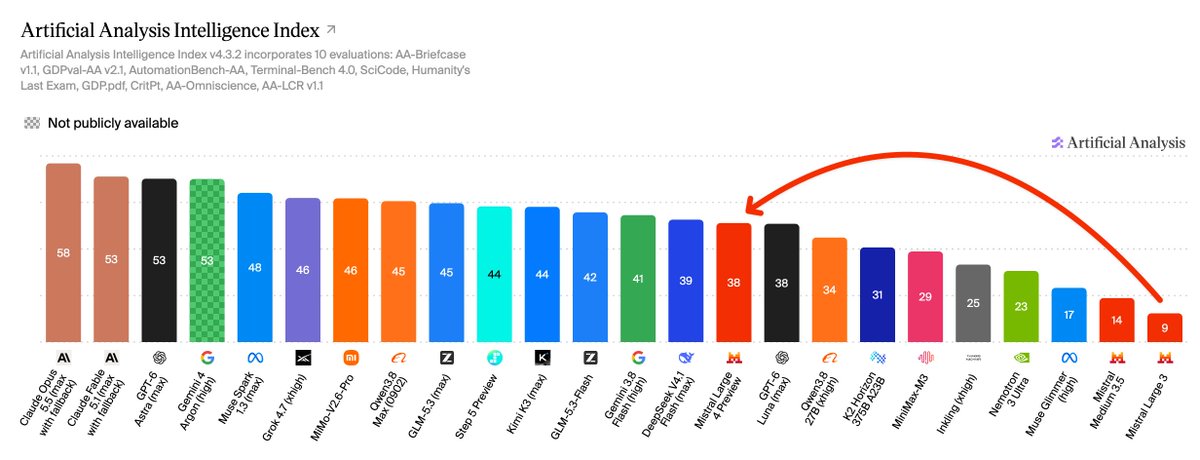
Mistral Large 4 is now open weights, narrowly making it the #1 open weights model developed outside of China @MistralAI has updated and released the weights of their flagship model, Mistral Large 4, with 1.05T total and 52B active parameters. With high reasoning, Mistral Large 4 scores 26 on the Artificial Analysis Intelligence Index v5, up 1 point from Mistral Large 4 Preview (25), with the major differences being increased token efficiency and reduced hallucinations. It sits 1 point ahead of the leading US-developed open weights model, Muse Spark Open (xhigh, 25). On the Artificial Analysis Cyber Index, Mistral Large 4 (high) scores 51, third among current open weights models behind DeepSeek V4.1 Flash 1017 (max, 57) and MiMo-V2.6-Pro (56). Key takeaways: ➤ Narrowly leads non-Chinese open weights models: Mistral Large 4 (high) leads Muse Spark Open (xhigh), the next-best open weights model developed outside China, with the largest gap on Terminal-Bench 4.0 (25% vs. 8%). It trails leading open weights models DeepSeek V4.1 Flash 1017 (max) and GLM-5.3 (max) by 6 points on the Intelligence Index, largely due to weaker coding and agentic knowledge work performance: 15% on…

Context
Mistral AI has released the weights of its flagship model, Mistral Large 4, and independent testing by Artificial Analysis suggests the final version is mostly a cheaper and more reliable model than the Preview it replaces, not a much smarter one. In the Artificial Analysis thread, the model scores 26 on the Intelligence Index v5 with high reasoning, one point above the Preview's 25. Artificial Analysis names increased token efficiency and reduced hallucinations as the main differences.
The efficiency gain is large. Mistral Large 4 produces 82,000 output tokens per Index task, 39% fewer than the Preview's 135,000, while the seven open-weights models that score higher use between 113,000 and 225,000. Mistral also cut the price roughly in half, to $0.70 per million input tokens and $2.10 per million output tokens, from $1.36 and $4.18. Fewer tokens at a lower price bring the cost of running one Index task to $2.06, down 63% from $5.54. That is about the same as Muse Spark Open, but still well above DeepSeek V4.1 Flash 1017 at $0.60 and MiMo-V2.6-Pro at $0.26. On the AA-Omniscience v1.1 knowledge test, the rate fell from 41% to 28%, though accuracy stays low at 26%, against 40% for DeepSeek V4.1 Flash 1017 and 42% for Muse Spark Open.
The headline claim that it is the best open-weights model developed outside China rests on a one-point margin over Muse Spark Open, the leading US-developed open model, which scores 25. The widest gap between the two is on Terminal-Bench 4.0, 25% against 8%. Against the strongest open models, DeepSeek V4.1 Flash 1017 and GLM-5.3, Mistral Large 4 is six points behind, and Artificial Analysis attributes most of that to coding and agentic knowledge work: 15% on FrontierCode 2.0 against 29% and 22%, and an AA-Briefcase rating of 1349 against 1570 and 1504. Coding agents are a partial exception. On the Coding Agent Index it scores 48 running in Mistral Vibe, one point behind GLM-5.3 running in Opencode, while using 8.5 million tokens per task to GLM-5.3's 15.9 million. Each model was measured in a different , so that comparison covers the model and its tooling together.
The weights come under Mistral's MEOW license (Mistral Ecosystem License). According to the thread, operating a Model-as-a-Service business on them requires a separate commercial license from Mistral, so a company that wants to resell access needs a deal with Mistral first. The thread does not describe the license's other terms.
- hallucination — When a model states something false with full confidence — inventing facts, citations, or APIs that don't exist.
- agent harness — The scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.




Checking sign-in…
Loading comments…