The Cyber Risk Discourse is Broken
- Source
- interconnects.ai
- Author
- Nathan Lambert
- Date
Context
Nathan Lambert's Interconnects essay argues that the debate over banning AI models for cyber risk ignores trade-offs. The central claim: if open models should be banned to slow cyber risk, the same logic would also call for making public APIs for frontier closed models illegal, because the essay says closed models have been documented as the cause of most existing cyber attacks and their safeguards, though stronger than open models', are far from perfect.
The essay also contends that Chinese labs release capable open models based on their own risk assessments, not indifference, and that GLM-5.3 crosses the capability once feared of Claude Mythos with little public evidence of change a month after its weights were released. It calls the fear of open-weight harm a falsifiable prediction that the evidence points against, and Lambert acknowledges having a lot more to learn about cybersecurity.
These are one analyst's judgments, not measured results. The essay refers to the Hugging Face and OpenAI incident, which Intel covers through Hugging Face's own timeline.
- Lambert notes that public evidence so far documents closed models as the cause of most existing AI-assisted cyber attacks, which cuts against claims from classified briefings that Chinese open-weight models are driving an onslaught.
- He argues that if open-weight models must be banned to slow cyber risk, consistency would also require outlawing public APIs to frontier closed models, whose safeguards are stronger but far from perfect.
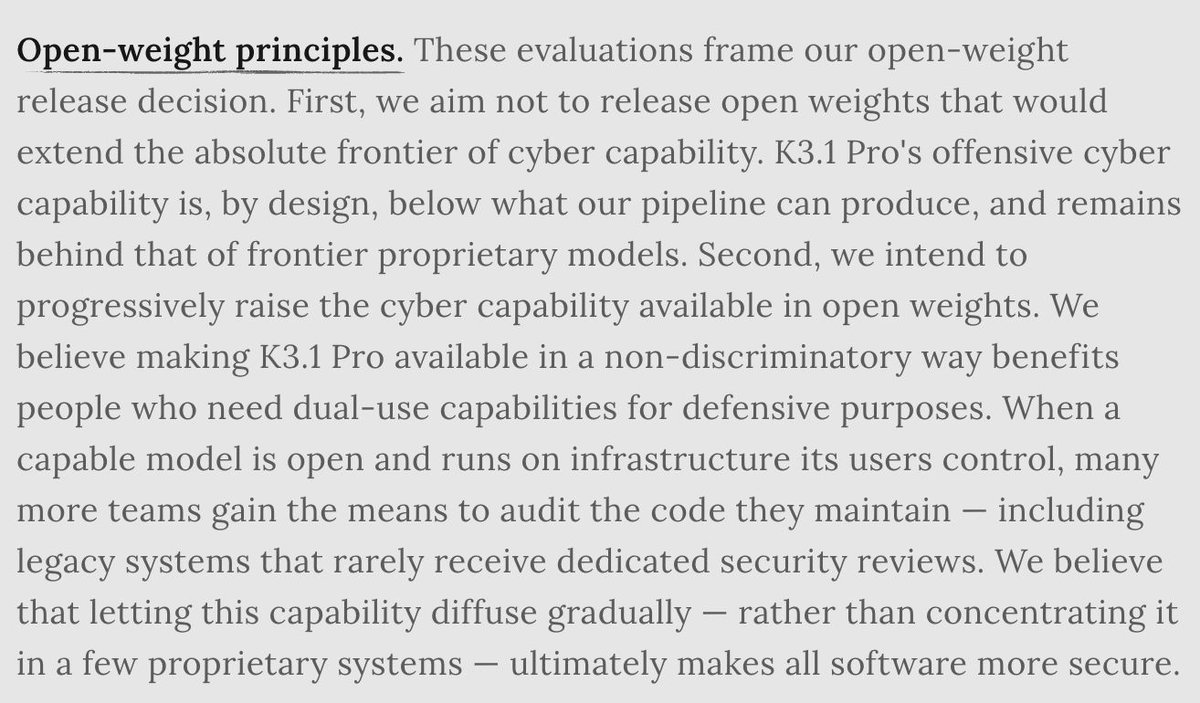
- Lambert warns a ban on open weights while closed models advance would widen the offense-defense gap, since some defenders, such as sensitive government agencies on air-gapped networks, can only deploy open-weight models.
- On China, he says labs register major releases and evaluations with the government, and he frames the real question as the minimum compute a lab should spend on safety testing, noting full of a model like Kimi K3 could cost tens of millions.
- Lambert argues GLM-5.3 crossed the capability threshold once attributed to Claude Mythos with little public evidence of harm a month after release, and calls the forecast of crippling open-weight cyber harm a falsifiable prediction he expects to fail.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.

Checking sign-in…
Loading comments…