Selecting The Right AI Evals Tool
- Source
- hamel.dev
- Author
- Hamel Husain
- Date
Context
An tool earns its place by making it easier to investigate and fix a failed interaction. Hamel Husain's tool-selection article uses vendors' attempts at the same assignment to examine that workflow: inspect a recorded interaction, annotate the problem, experiment with a change and analyze the results.
This supports the error-analysis process in the field guide. Human review, access to underlying data and export options are among the criteria Husain applies when asking whether a team can investigate beyond a score. The mid-2025 vendor comparisons illustrate those criteria; they do not establish a permanent winner among products.
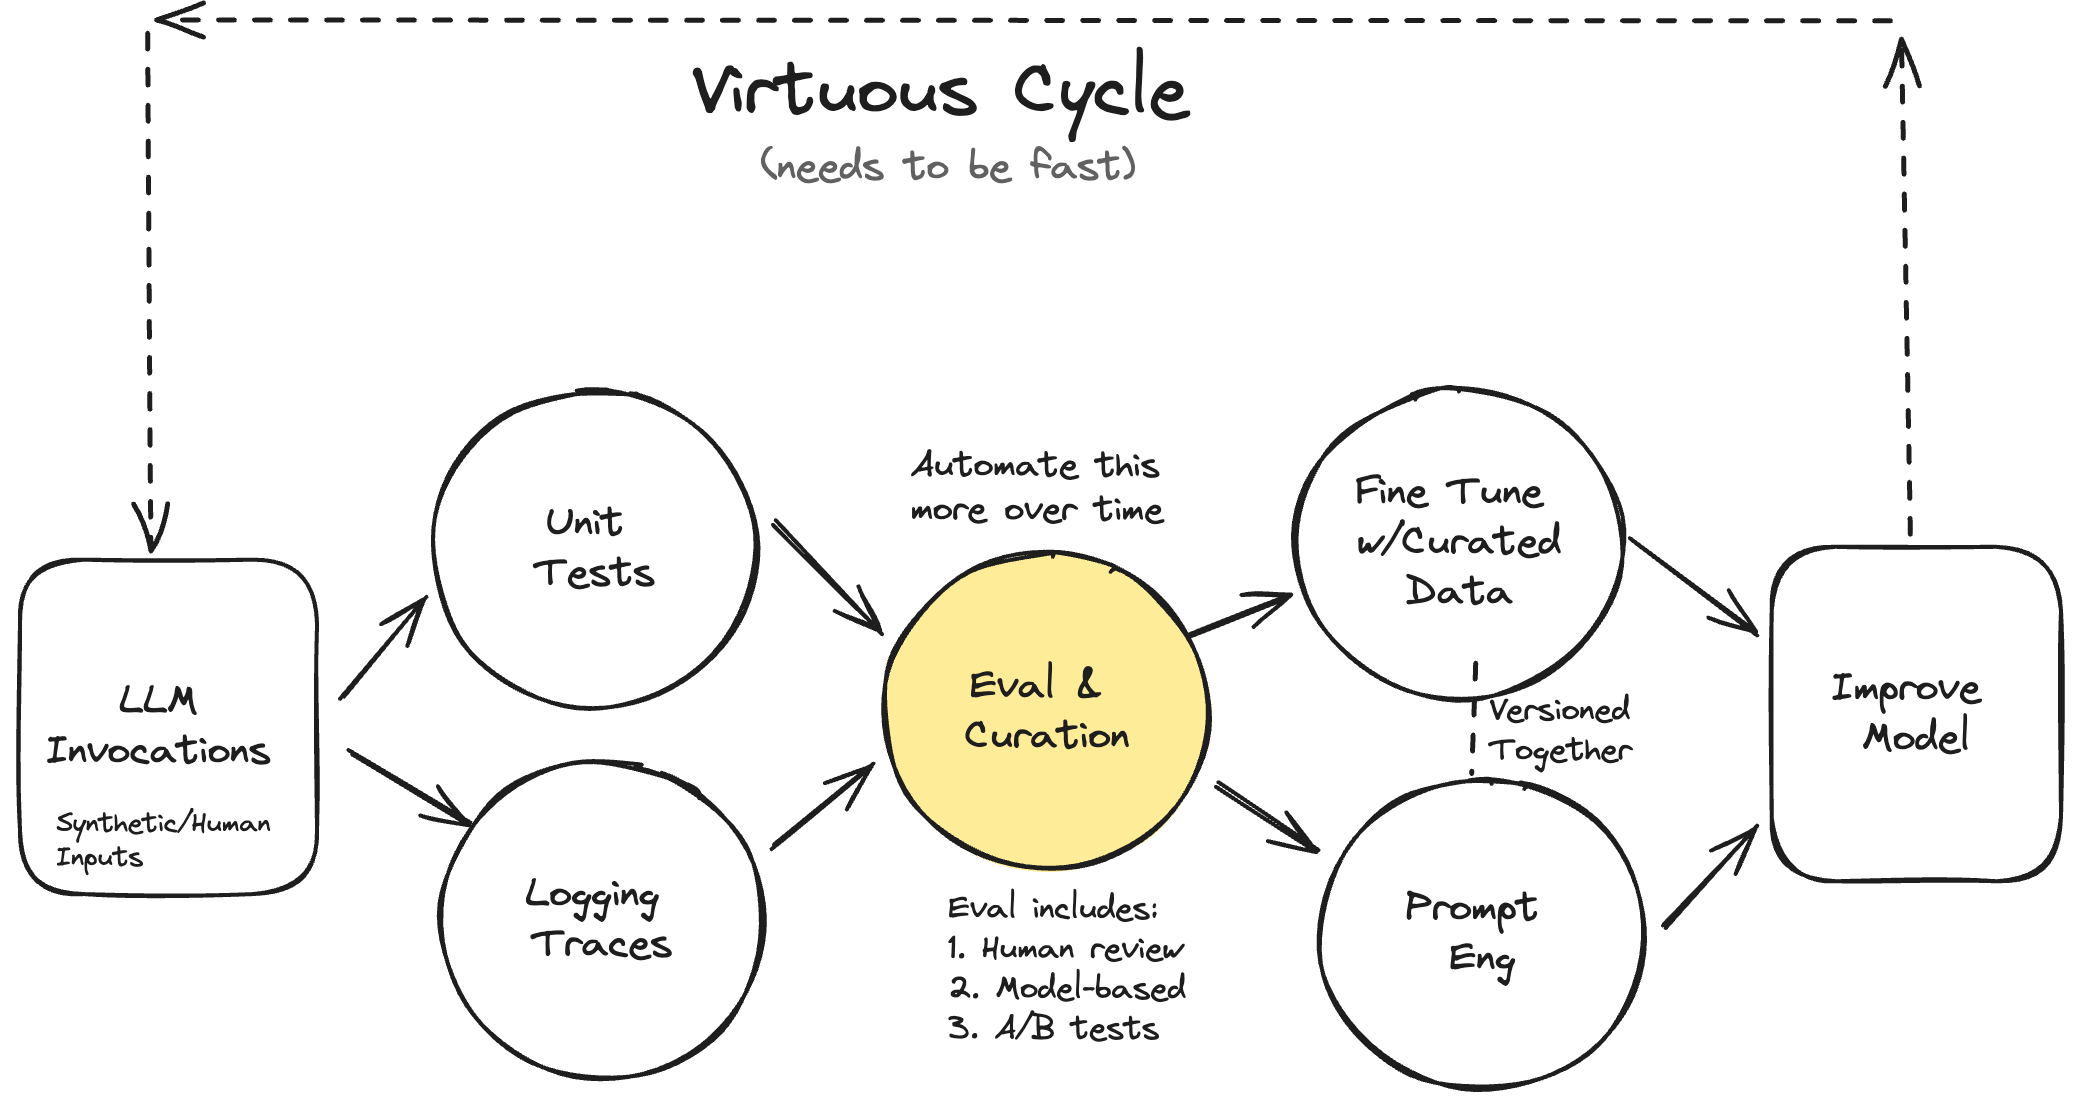
- The measure that separates eval tools is time from observing a failure to iterating on a fix. Concretely: can you go from viewing a single trace to experimenting with that same trace in a playground without leaving the tool?
- Be deeply skeptical of any feature where an AI writes the evaluation rubric and then immediately scores outputs against it. Stacking those two abstractions hides flaws behind a confident high score.
- Error analysis is the highest-ROI activity in AI engineering, so first-class manual annotation beats automation. Most tools still lack axial coding: grouping open-ended failure notes into structured, countable categories.
- Braintrust's "money table" is the output pattern to want. Once traces are annotated with failure modes, you get a view you can sort and filter to quantify which failures are actually most common.
- Proprietary query languages like Braintrust's BTQL and weak export add friction. Hamel's own setup treats these tools as a backend data store and does the real analysis in Jupyter with custom annotation interfaces.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
“The best tools don’t try to automate away the human; they empower them.”
“be wary of features where an AI agent both creates an evaluation rubric and then immediately scores the outputs. This “stacking of abstractions” often hides flaws behind a high score.”
“An eval tool should fit your stack, not force you to fit its stack.”
“As for me personally, I tend to use these tools as a backend data store and use Jupyter notebooks as well as my own custom built annotation interfaces for most of my needs.”
Checking sign-in…
Loading comments…