Is the Rush to Build New LLM Inference Engines Fragmenting the Ecosystem?
- Source
- x.com
- Date

why did everyone suddenly decide specialized inference engines are a good idea? i've seen at least 5 of these released in the last month. what's wrong with vLLM/sgLang? sure you can generate a slop inference engine quickly now but why fragment the ecosystem? it's harmful.
Context
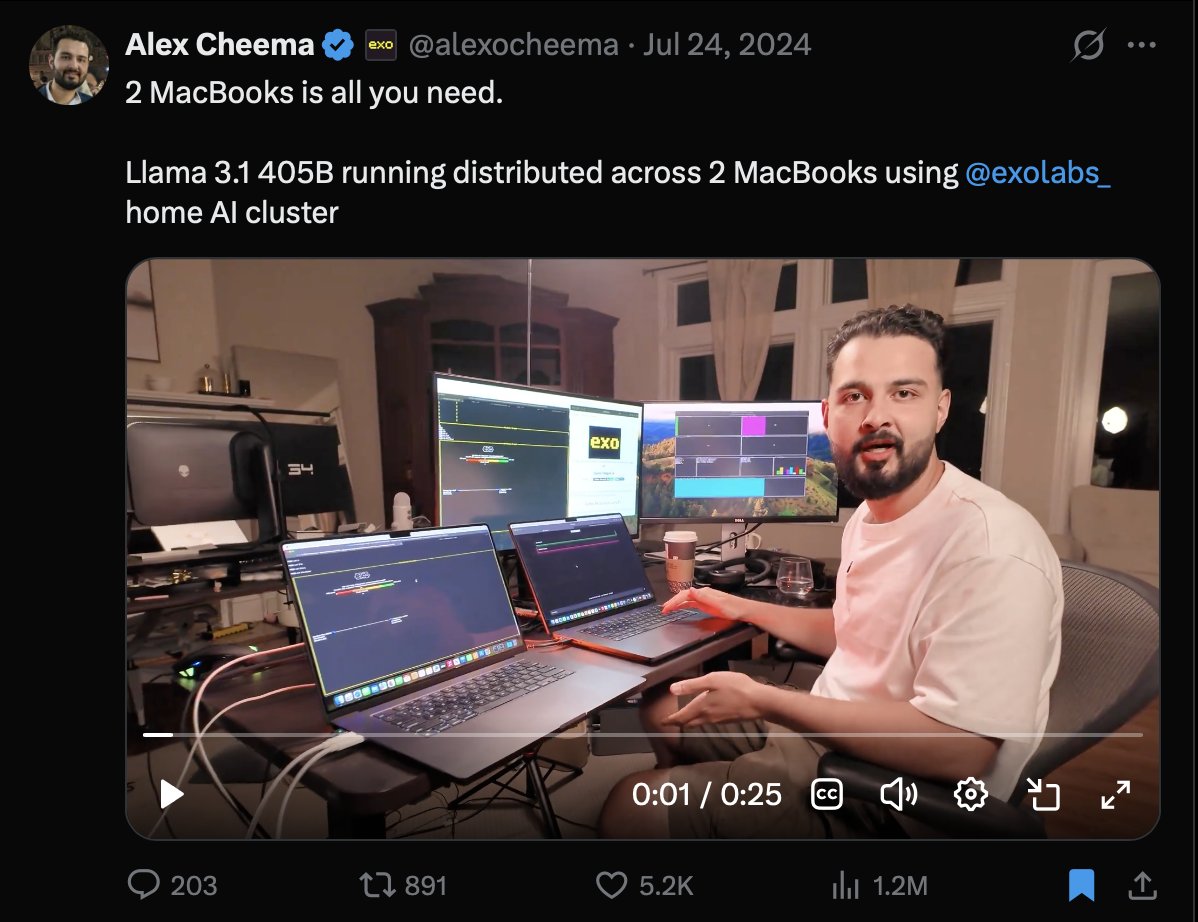
In a post questioning the trend, Alex Cheema says he has seen at least five new specialized -serving engines released in the past month, and asks why teams are building narrow engines instead of extending established, widely used ones like vLLM and sgLang.
His concern is that easier-to-generate code, he points to AI-assisted development making it faster to spin up a new inference engine, could be fragmenting effort across many narrow projects instead of concentrating it on shared infrastructure. This is his own opinion and question to his followers, not a documented count of releases or an agreed-upon industry consensus.
- postBig model. 2.4T params, 95B active. 4.89TB. Surprised they didn't release a 4-bi
 post@Jason @Lons @eisokant @ape Correction: Should actually be closer to 50 tok/sec
 postApple markets a four-Mac cluster for trillion-parameter local inference
 postLocal inference crosses over: the M5 Ultra and the 1,000x claim


Checking sign-in…
Loading comments…