Which Model Reviews Code Best?
- Source
- factory.ai
- Date
Context
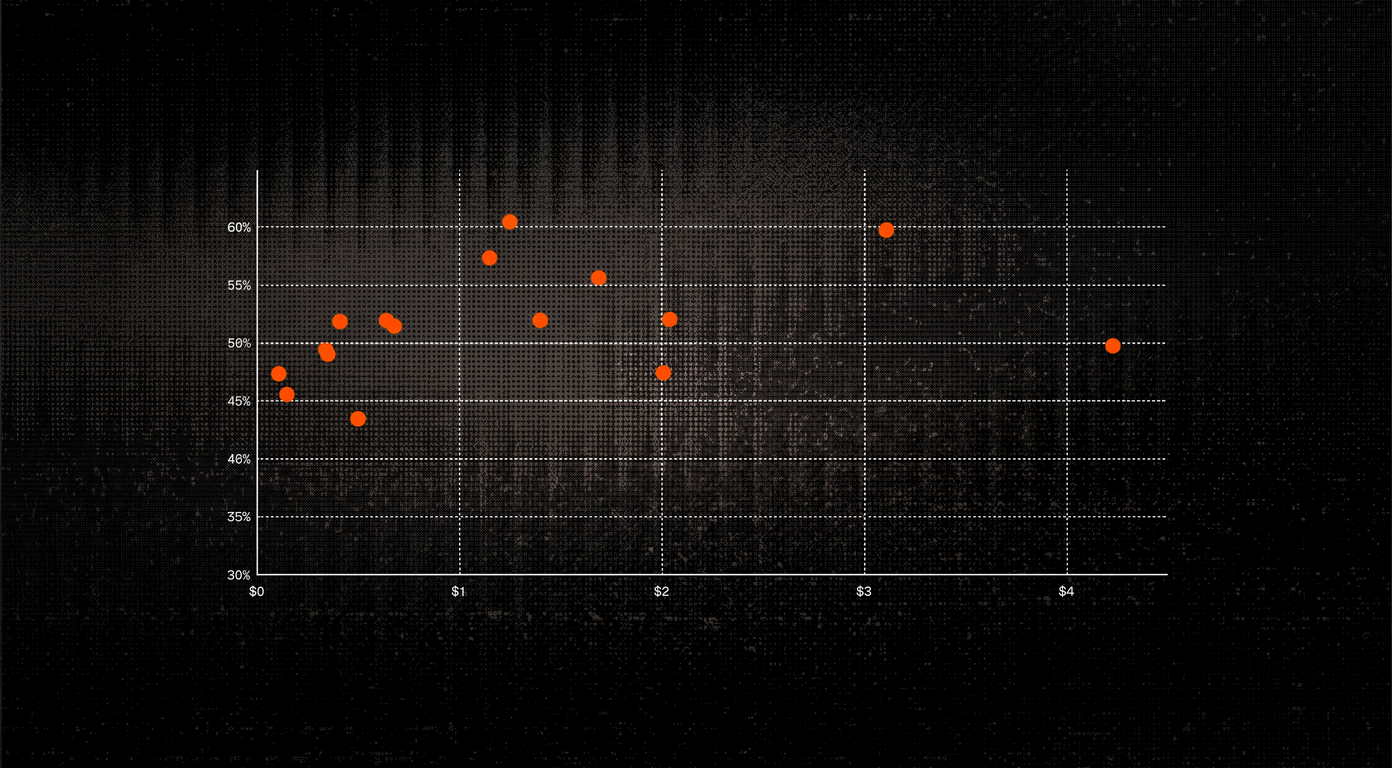
Factory benchmarked 13 models on code review, using 50 real pull requests from five open-source projects. Two results stand out: OpenAI's GPT-5.2 scored 60.5% F1 at a reported $1.25 per review, while Anthropic's Opus 4.6 scored 59.8% at $3.11. F1 balances how many reported problems are real bugs against how many known bugs the reviewer finds. The 0.7-point gap is small, and run-to-run variation in the report is larger, so the pair mainly shows that a much higher price did not buy a clearly better score here. Results.
The comparison used identical prompts, high reasoning settings and three runs per model, with an matching findings to a human-curated set of known bugs. Costs use Factory's pricing multipliers rather than list API prices, and runs where a model clearly malfunctioned were excluded. These results describe review quality under that protocol, not every kind of operational failure. Methodology and pricing.
- LLM-as-judge — Using one model to score another's output against a rubric, so quality can be measured at a scale human grading cannot reach.
Checking sign-in…
Loading comments…