Code Review Benchmark
- Source
- factory.com
- Author
- Factory News
- Date
Context
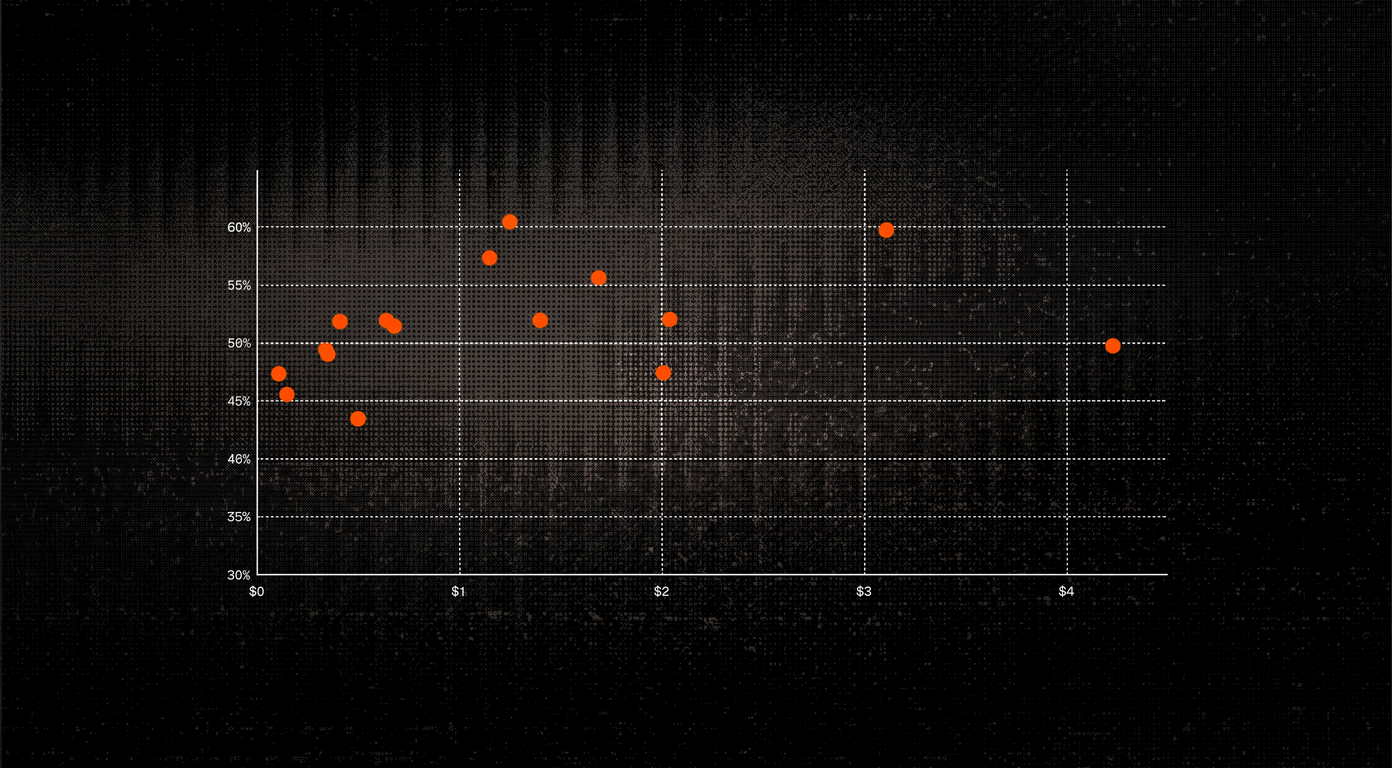
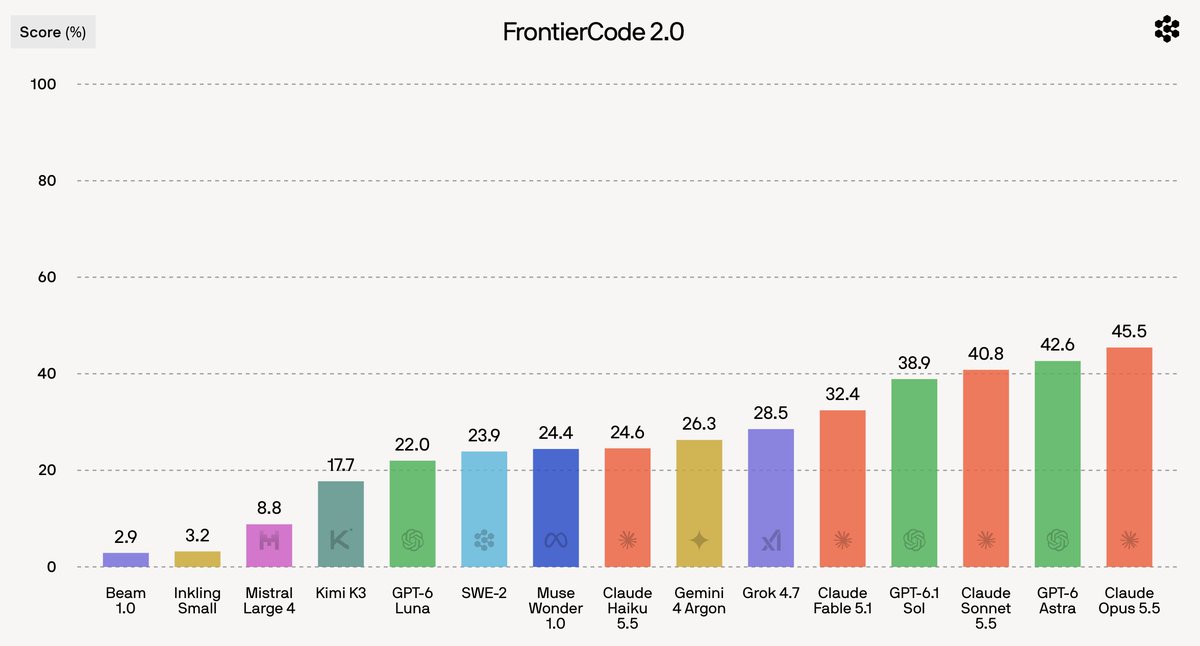
The most expensive model did not produce the best reviews in a code-review test run by Factory for its Droid coding . Across fifty pull requests (proposed code changes), OpenAI's GPT-5.2 achieved a reported 60.5% F1 score at $1.25 per review, compared with GPT-5.5's 47.9% at $5.63. F1 combines how many reported problems are real with how many known problems the reviewer finds. The benchmark therefore compares useful detection against both missed bugs and false alarms.
Thirteen models used standardized prompts and reviewed each pull request at least three times. An scored the findings against a golden set of bugs curated by humans and validated by engineers. The costs use Factory's pricing system. These results support testing models on the actual review task rather than treating higher price or a newer version as evidence of better detection.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- LLM-as-judge — Using one model to score another's output against a rubric, so quality can be measured at a scale human grading cannot reach.

Checking sign-in…
Loading comments…