A (Long) Peek into Reinforcement Learning
- Source
- lilianweng.github.io
- Author
- Lilian Weng
- Date
Context
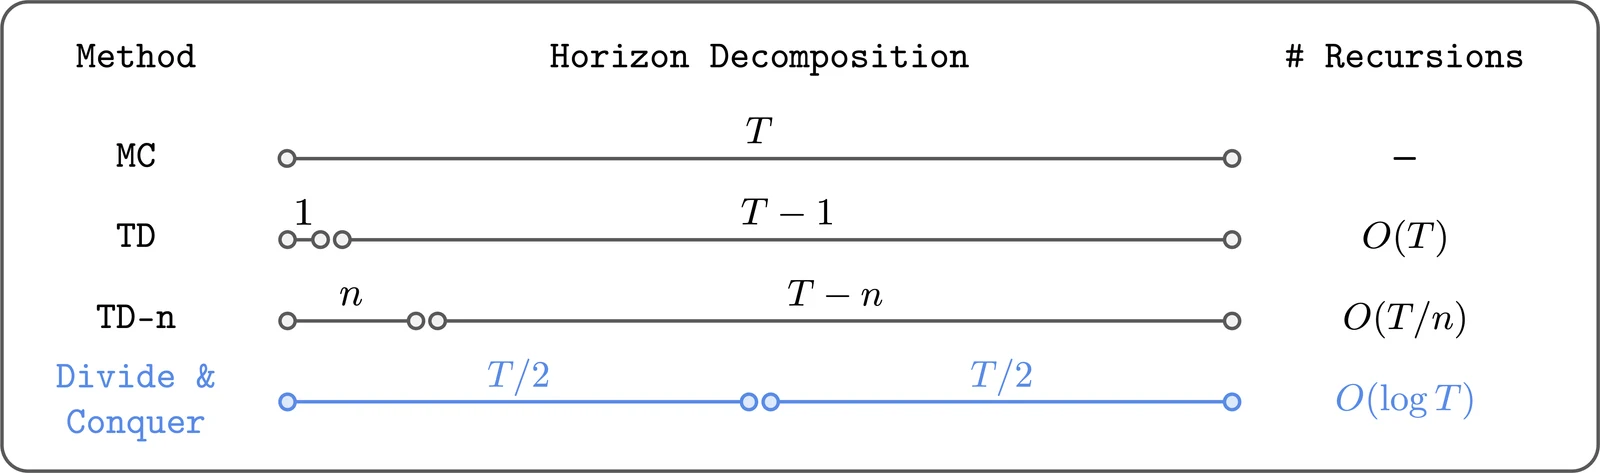
A reinforcement-learning can update its estimate of future reward before a trial has finished. Lilian Weng's 2018 overview explains this through temporal-difference learning: combine the reward just received with the estimated value of the next state, then adjust the previous state's value toward that target.
This differs from the described Monte Carlo approach, which waits for a completed trial and learns from the rewards actually accumulated. Temporal-difference learning gets an earlier update by relying partly on an existing prediction. That reliance is called bootstrapping, and explains how an agent can learn step by step without waiting to observe the entire eventual outcome.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
“Very soon the extended algorithm AlphaGo Zero beat AlphaGo by 100-0 without supervised learning on human knowledge.”
Lilian Weng
“The goal of Reinforcement Learning (RL) is to learn a good strategy for the agent from experimental trials and relative simple feedback received. With the optimal strategy, the agent is capable to actively adapt to the environment to maximize future rewards.”
Lilian Weng
“TD learning is so important that Sutton & Barto (2017) in their RL book describes it as “one idea … central and novel to reinforcement learning”.”
Lilian Weng
“The key difference from SARSA is that Q-learning does not follow the current policy to pick the second action”
Lilian Weng
“Experience replay improves data efficiency, removes correlations in the observation sequences, and smooths over changes in the data distribution.”
Lilian Weng




Checking sign-in…
Loading comments…