RL without TD learning
- Source
- bair.berkeley.edu
- Date
Context
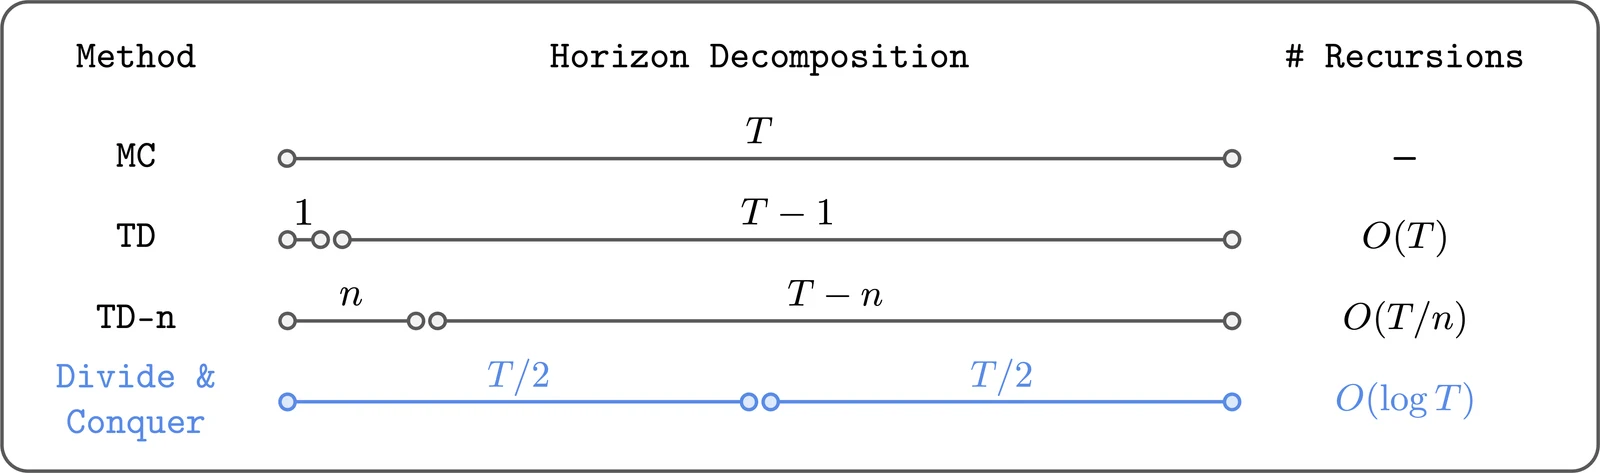
Learning to reach a distant goal can be easier if the task is repeatedly divided around intermediate goals. Transitive RL applies this idea to learning from recorded experience. Instead of estimating a long route only through one-step updates, it combines estimates for reaching a midpoint and then continuing to the destination. The research account appears on the Berkeley AI Research blog.
Searching every possible midpoint would be impractical, so the method uses intermediate states already present in recorded trajectories. The author reports strong results on long maze and puzzle tasks without choosing a fixed trajectory-chunk length for each task. The demonstrated formulation concerns goal-reaching problems with deterministic dynamics, which limits claims about broader reinforcement-learning settings.
- TD learning's error accumulates through Bellman bootstrapping over the whole horizon; n-step TD only cuts the number of recursions by a constant factor n and forces a variance tradeoff, while divide-and-conquer cuts recursions logarithmically instead of linearly.
- The divide-and-conquer update exploits the triangle inequality on shortest-path distance between states: a value can be updated from two smaller values via an optimal subgoal midpoint, rather than one-step bootstrapping.
- Since finding the true optimal subgoal is intractable in continuous spaces, the method restricts the search to states already lying between the start and goal in a sampled dataset trajectory, and replaces the max operator with expectile regression to avoid value overestimation.
- On OGBench's hardest humanoidmaze and puzzle tasks (1B-sized datasets, up to 3,000 environment steps), the method matched the best individually-tuned n-step TD baseline on every task without needing to tune n, beating TD, Monte Carlo, and quasimetric-learning baselines.
Checking sign-in…
Loading comments…