LFM2.5 Q4\_0 Checkpoints from Quantization-Aware Distillation
Source
huggingface.co
Date
Context
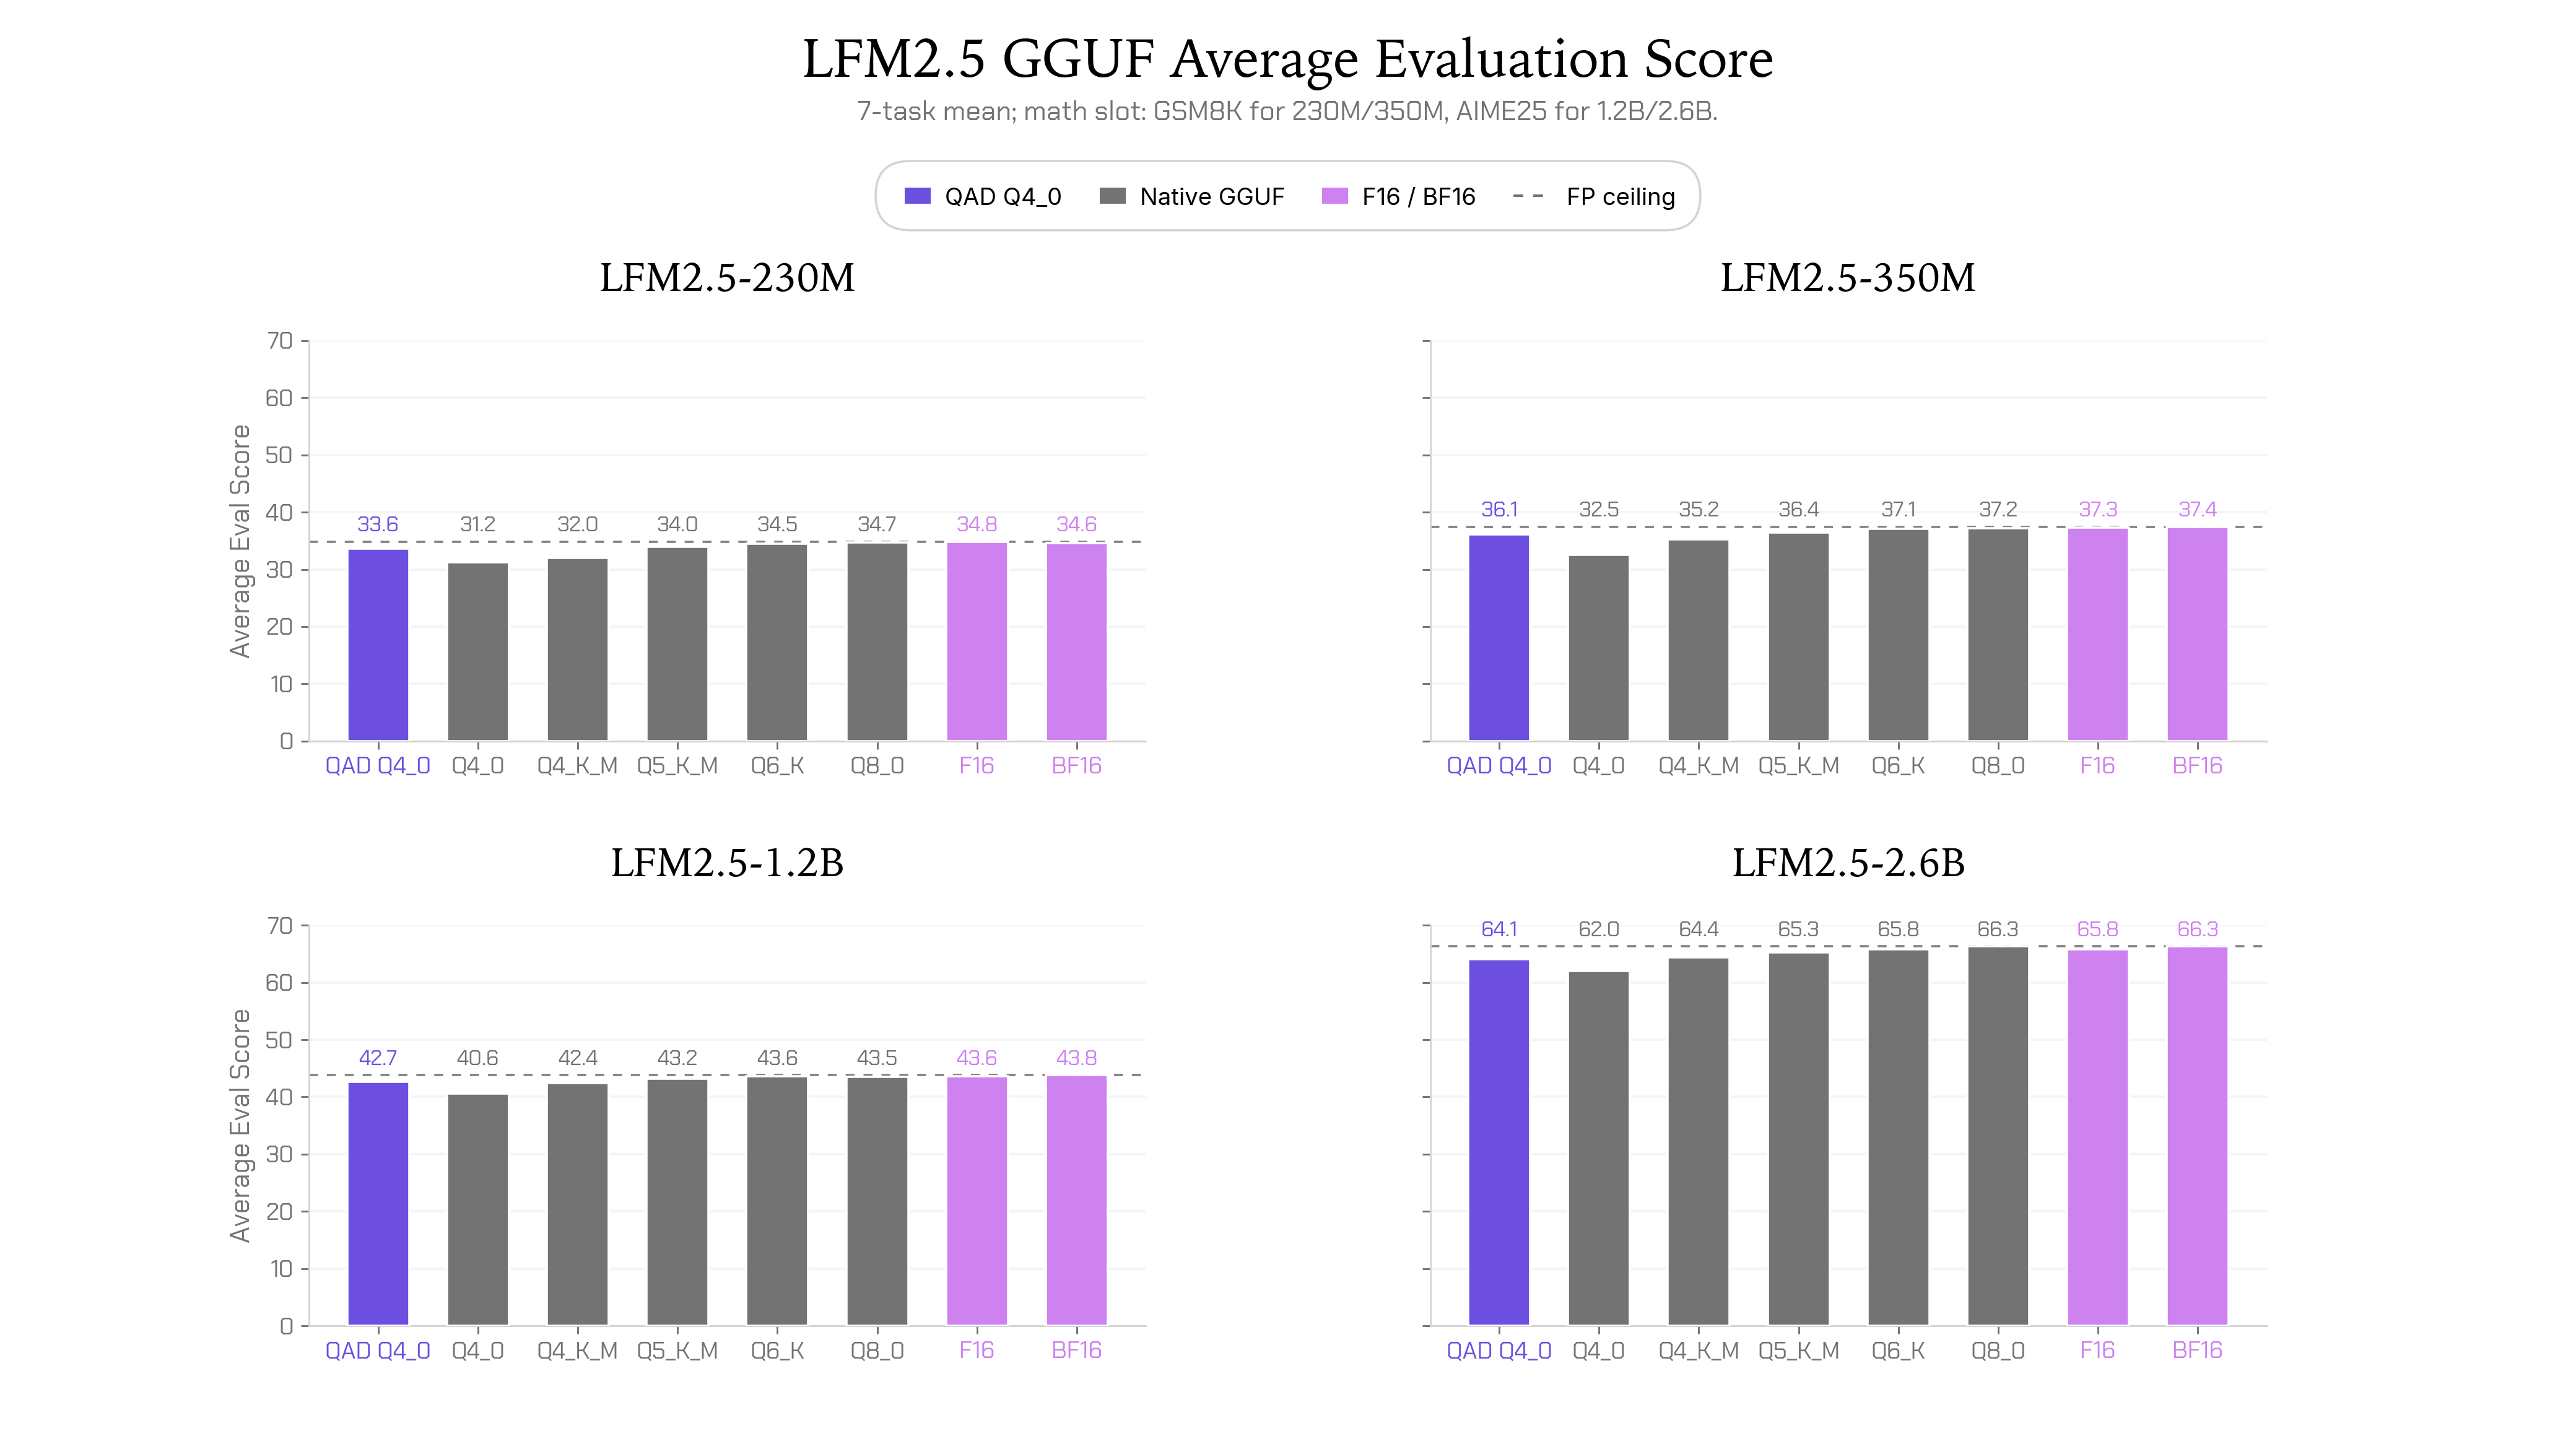
Liquid AI trained new four-bit LFM2.5 models to preserve more of their higher-precision counterparts' performance. Its quantization-aware distillation method trains a compressed student model using a higher-precision teacher, while retaining the memory footprint and runtime format of ordinary Q4_0 files.
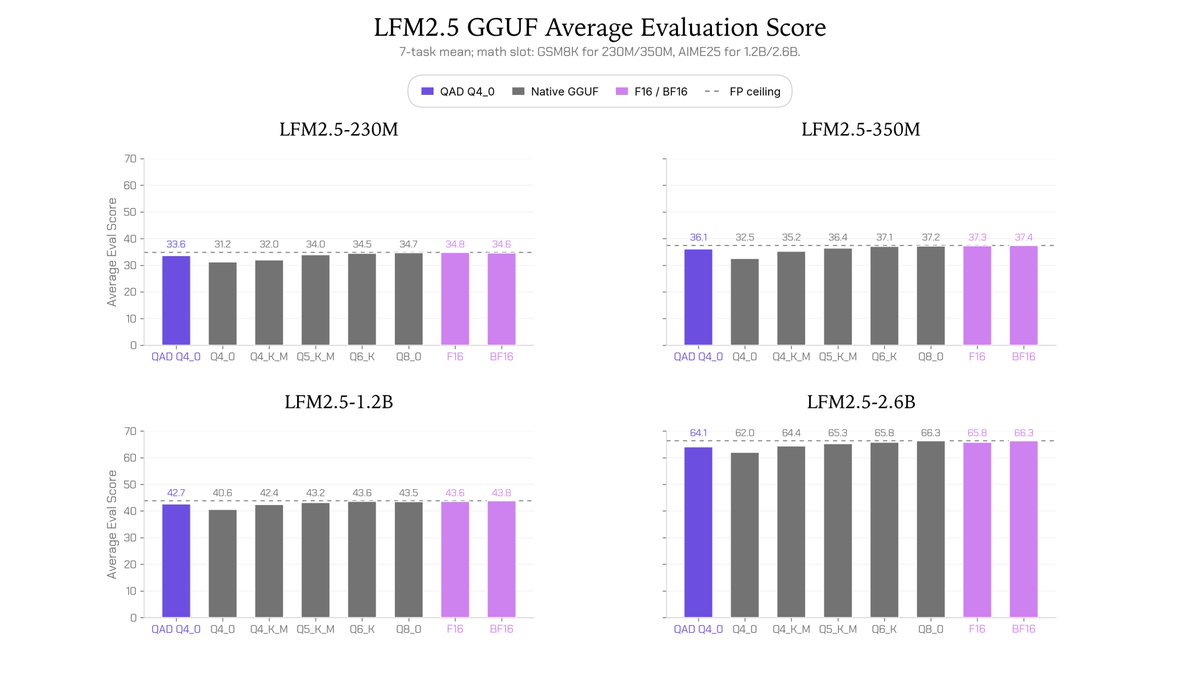
Across four model sizes, the detailed results report retaining 96.5% to 97.4% of the corresponding BF16 baseline performance on the tested benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → suite. That is a fraction of each baseline's performance, not 97% correct answers or 97% of lost accuracy recovered. The useful result is improved benchmark performance within the same four-bit deployment format.
Terms in this piece · Glossary
quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.
distillation — Training a small, cheap model to imitate a big one's outputs, keeping much of the capability at a fraction of the cost.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.