← All IntelIntel / article
LifeSciBench
- Source
- openai.com
- Date
Why it matters
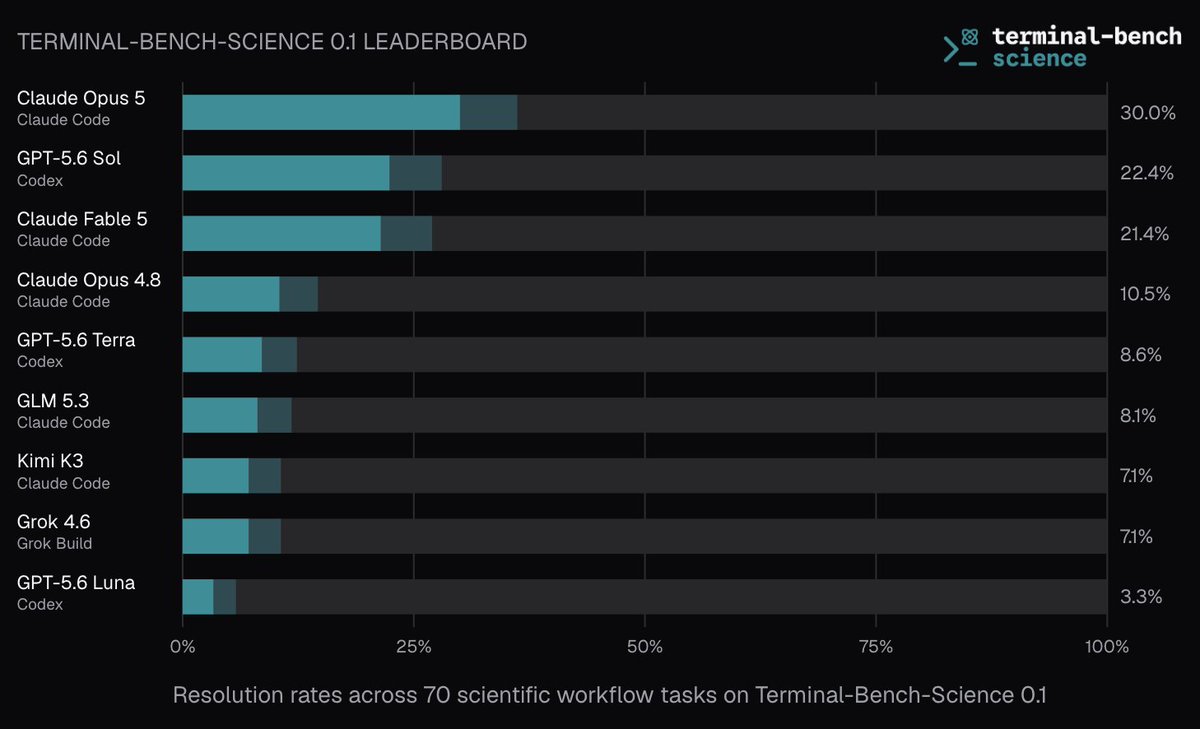
A new expert-authored for real research decisions rather than exam-style questions — a reference point for how frontier models get measured on genuine domain work.
Terms in this piece · Glossary
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
Read the source openai.com
Recommended reads
Comments
Checking sign-in…
Loading comments…