Stanford Releases Terminal-Bench-Science for AI Research Agents
- Source
- x.com
- Date

Terminal-Bench-Science is out! https://t.co/X4OYTeSmho
Context
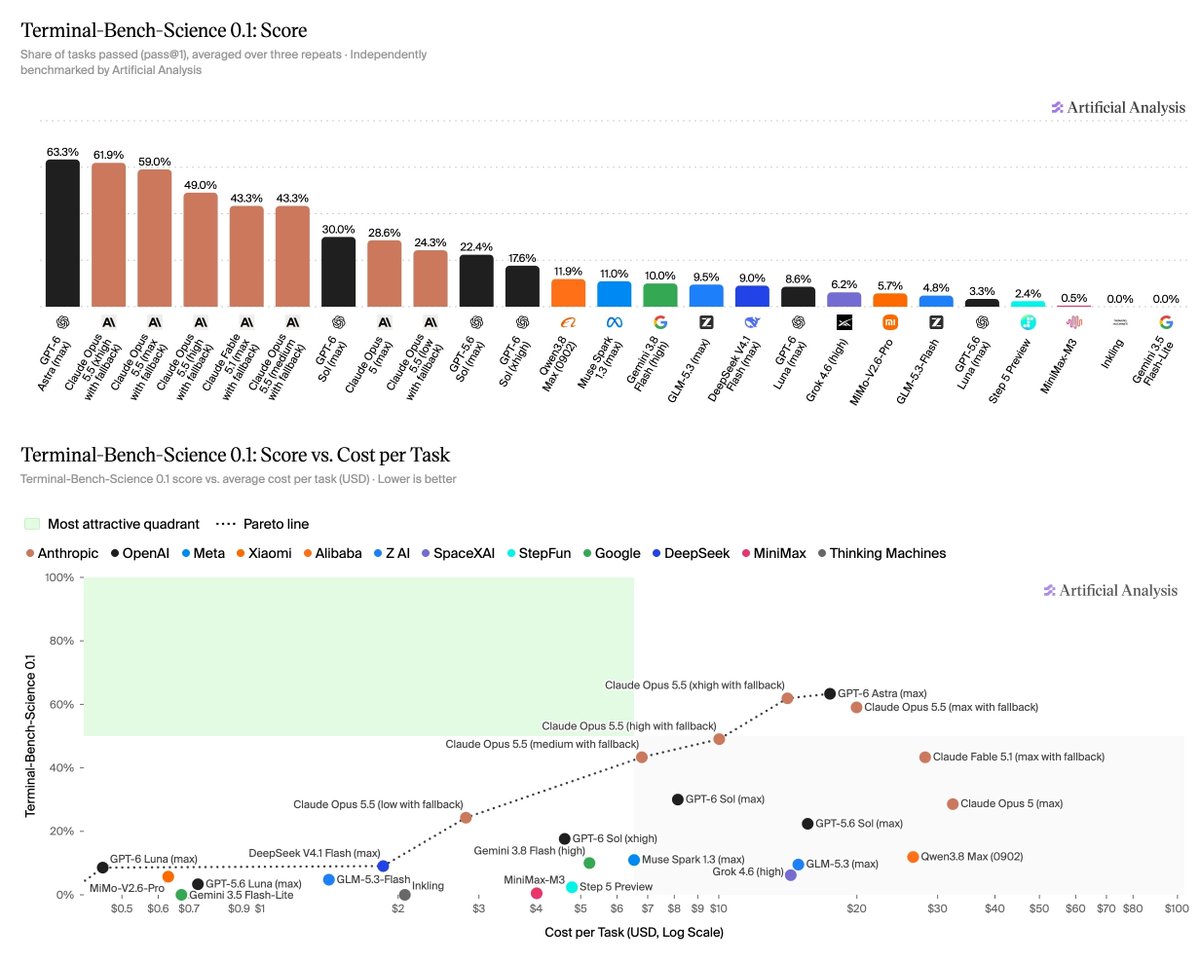
Most benchmarks test coding or general reasoning, not whether an agent can actually carry out a scientific research task, such as running a statistical analysis correctly or setting up a valid simulation. Stanford led the release of Terminal-Bench-Science 0.1 to measure exactly that, building on the existing Terminal-Bench project for evaluating agents in realistic command-line environments.
The release contains 70 tasks spanning life sciences, physical sciences, Earth sciences, mathematical sciences, and engineering, each contributed and reviewed by practicing scientists rather than by model developers. Getting to that final 70 involved filtering roughly 920 initial task proposals down through domain review for scientific validity, technical review for how the task is built and verified, and a final quality check, so the bar for inclusion was high relative to the number of submissions.
Because each task is graded by a reproducible, task-specific test rather than by human judgment, results are comparable across different AI agents and over time as new releases add tasks and retire ones that stop being challenging.





Checking sign-in…
Loading comments…