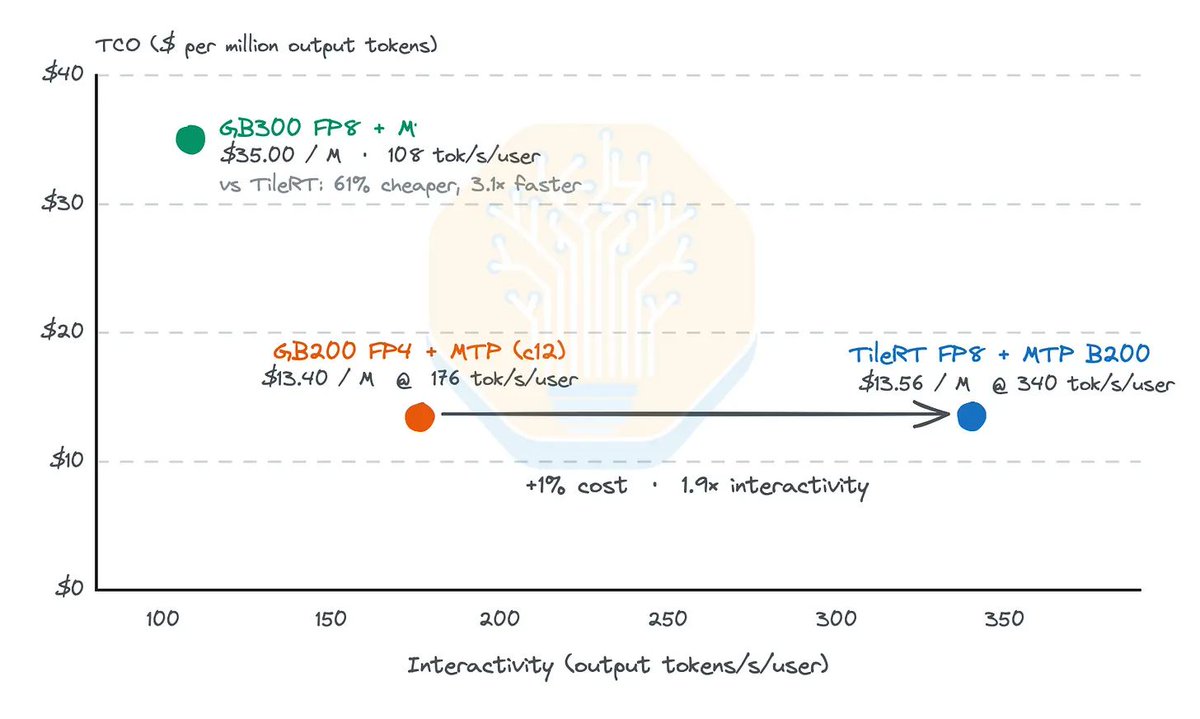
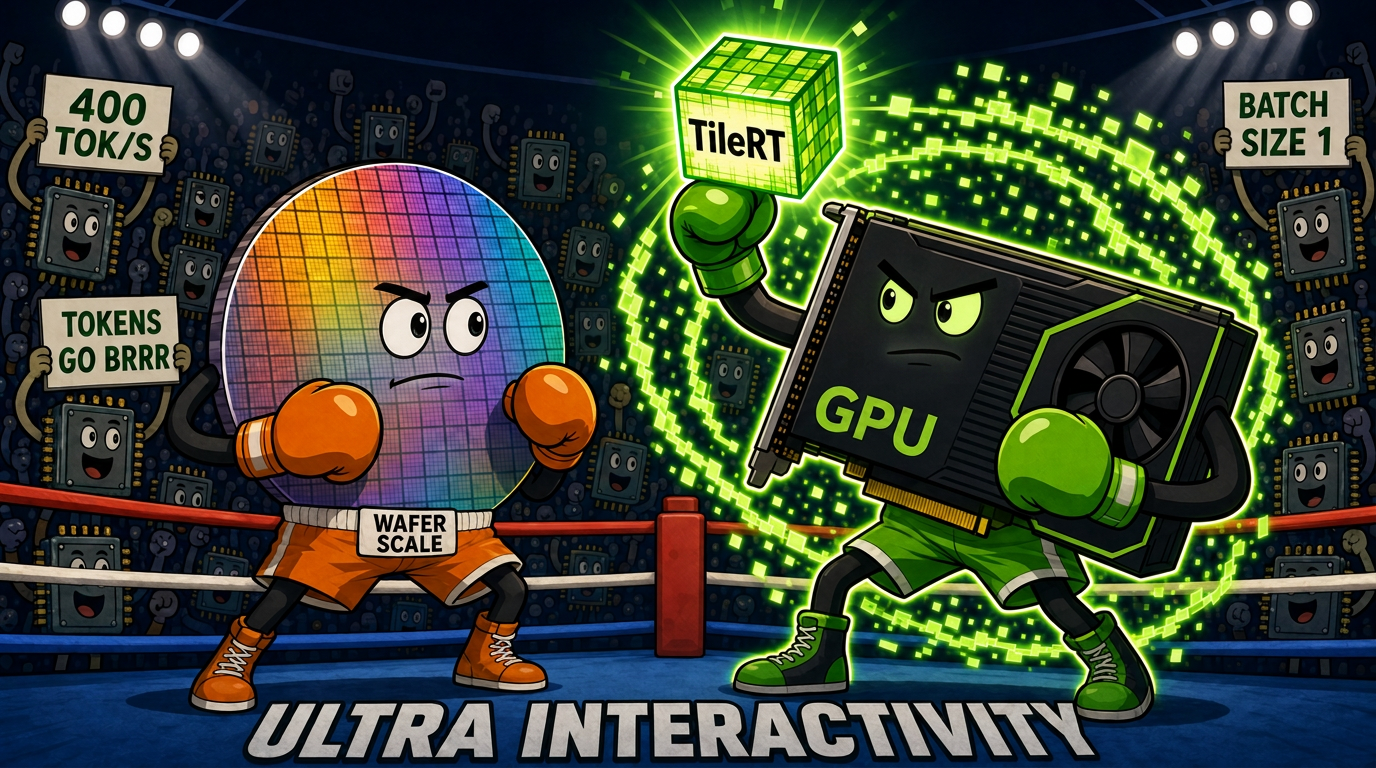
ALERT🚨 TILERT from @TileRT_AI TO BOOST DECODE INTERACTIVITY BY 1.9X AT THE SAME PER-TOKEN COST ON THE SAME NVIDIA BLACKWELL GPUs. What does this mean for Groq/Cerebras/SambaNova? 👇️ 1/5🧵
If a compiler-level change gets that much interactivity out of existing GPUs, the case for specialized inferenceRunning a trained model to get answers — the phase where AI is actually used, as opposed to trained.Full definition → hardware narrows, and serving latency budgets for AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition → loops move.
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.