Why Kimi K3's Architecture Is a Masterclass in AI Efficiency
- Source
- alphasignal.ai
- Author
- AlphaSignalAI
- Date
Context
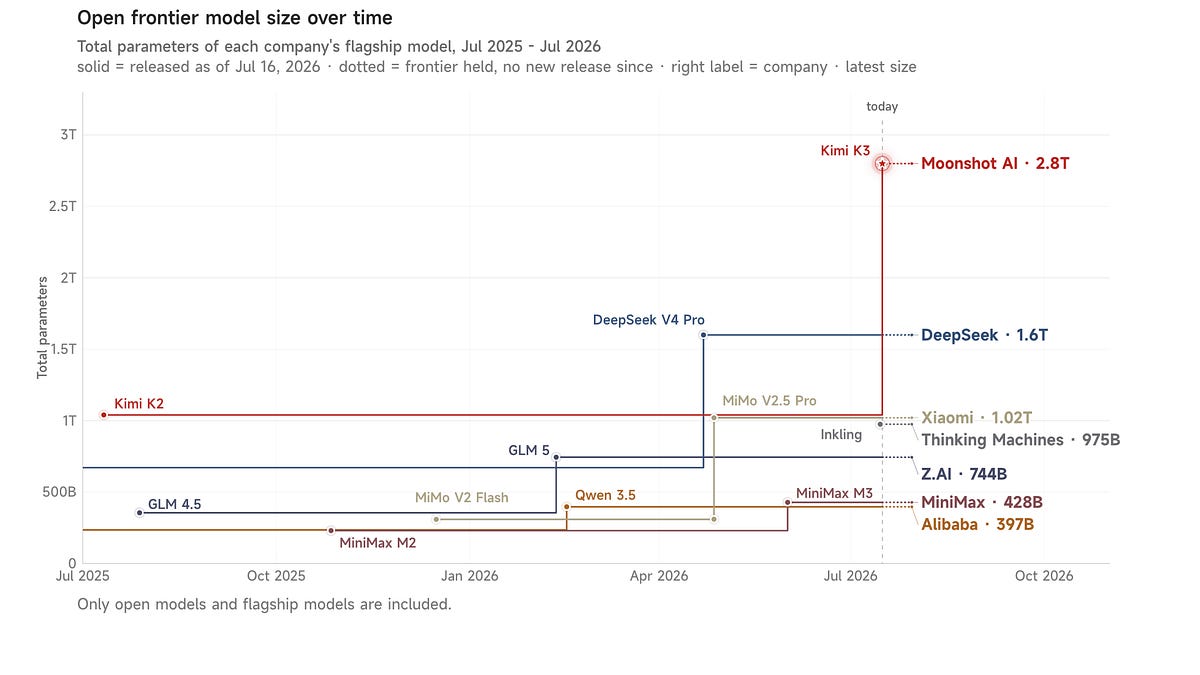
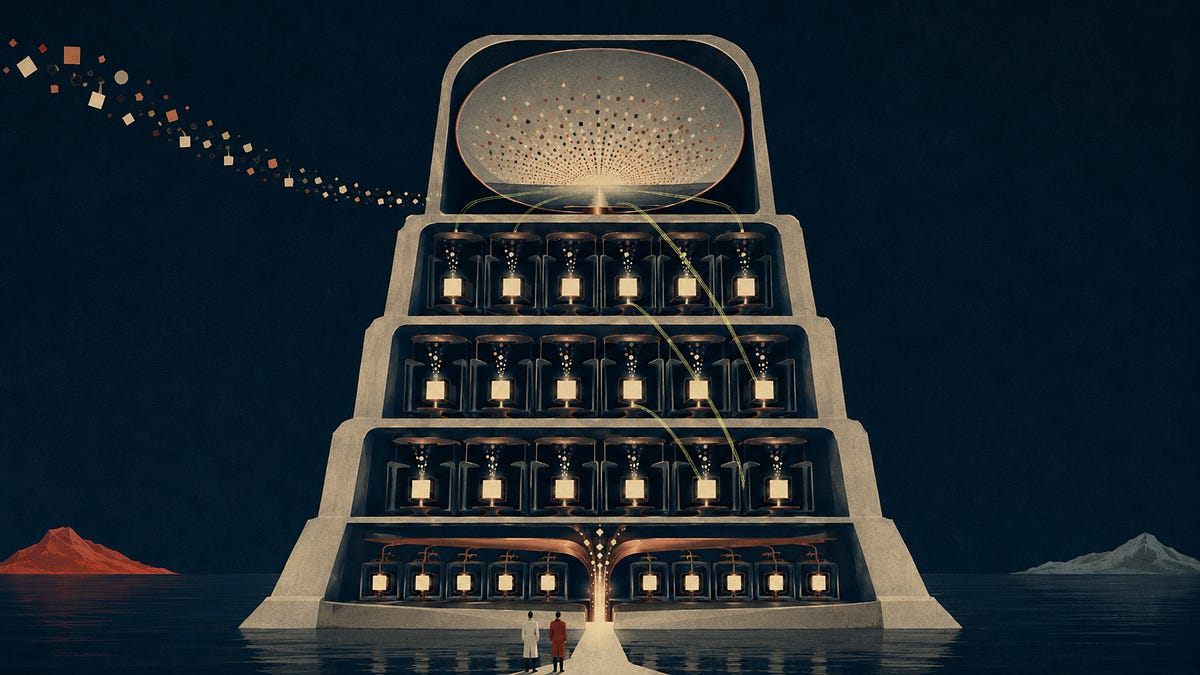
Kimi K3's total size is much larger than the portion it activates for each generated token. Moonshot AI's model card lists 2.8 trillion parameters in total and 104 billion active per token. Its design selects 16 of 896 routed experts, concentrating computation on a subset of the model for each step.
That distinction explains how an extremely large model can avoid using all its parameters on every calculation. It also separates two questions: how much learned capacity the model contains, and how much of it participates in an individual step.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
- quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.
“Kimi K3 is a multimodal Mixture-of-Experts (MoE) model with 2.8 trillion total parameters. Through extreme sparsity, only about 104 billion parameters activate per token, roughly 16 out of 896 experts. It natively supports a 1 million token context window.”
Ben Dickson
“Moonshot AI recently released the weights for its flagship Kimi K3 model, making it the largest open-weights LLM to date, rivaling Opus 4.8 and GPT-5.6.”
Ben Dickson
“on the AA-Briefcase benchmark it places second overall, trailing only Claude Fable 5, and beats both GPT-5.6 Sol and Opus 4.8 in that category”
Ben Dickson
“You cannot spin up 2.8 trillion parameters efficiently without innovations at every level of the stack.”
Ben Dickson
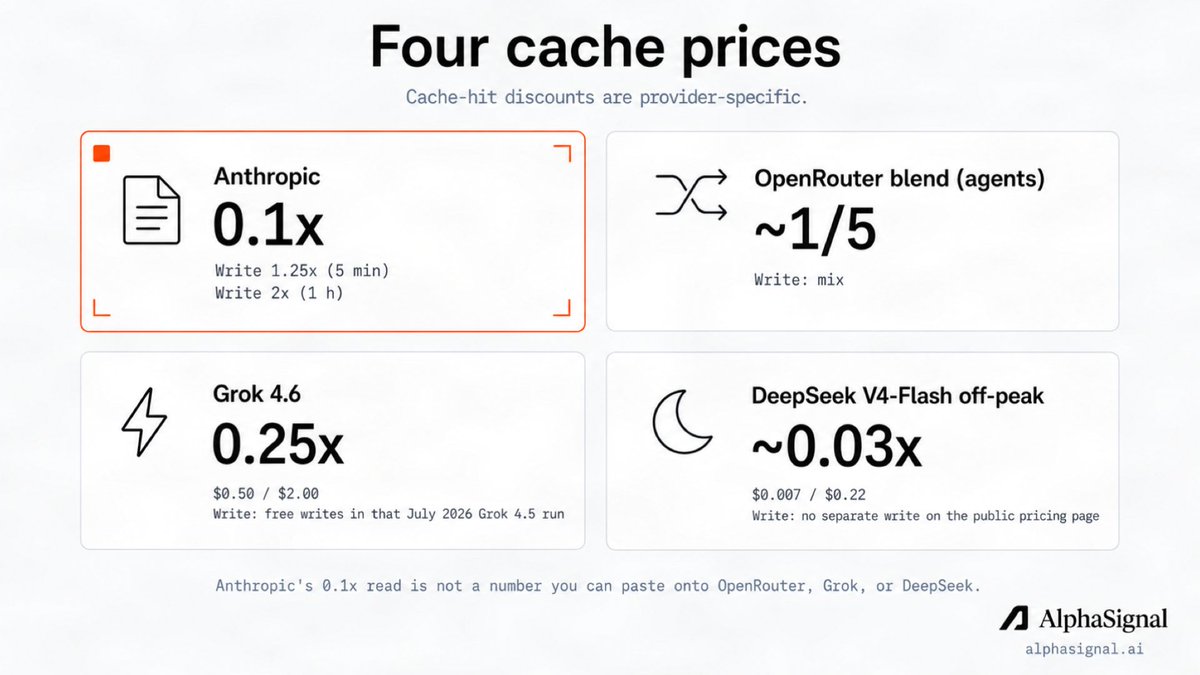 postPrompt cache TTL is the hidden line item in long coding-agent sessions
 articleFull breakdown: Claude-only apps often wait until the host speaks the new revisi
 articleDo not ask whether the agent follows the rule. Ask what stops it when it does no
 articleFull Breakdown: When can a change ship unread? When something cheap and hard to
Checking sign-in…
Loading comments…