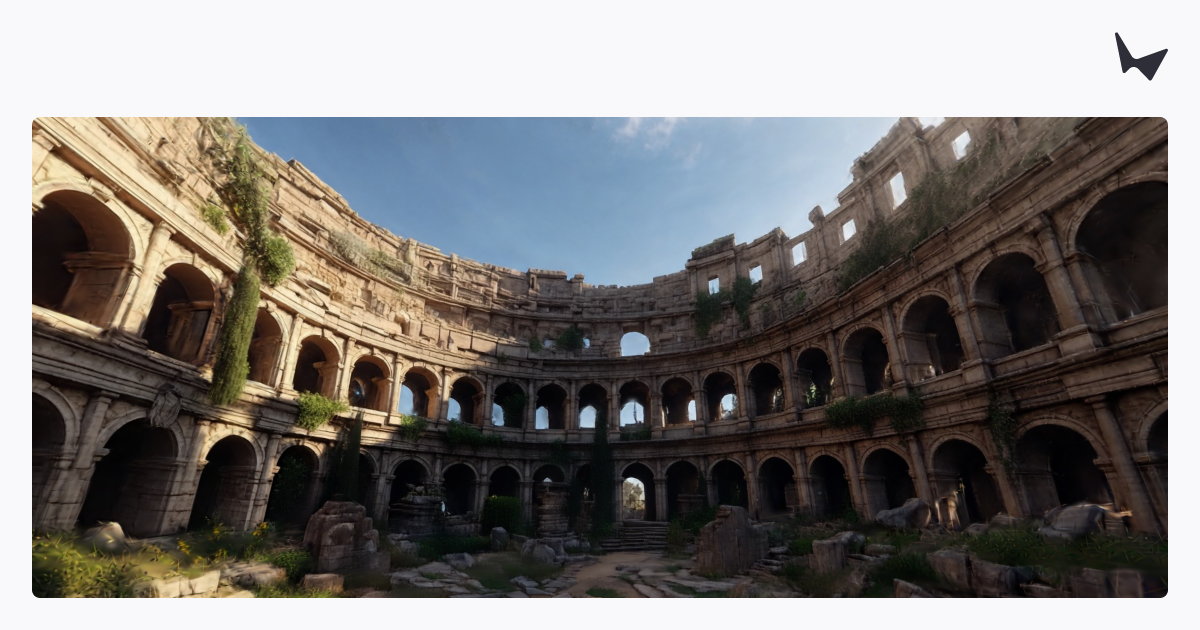
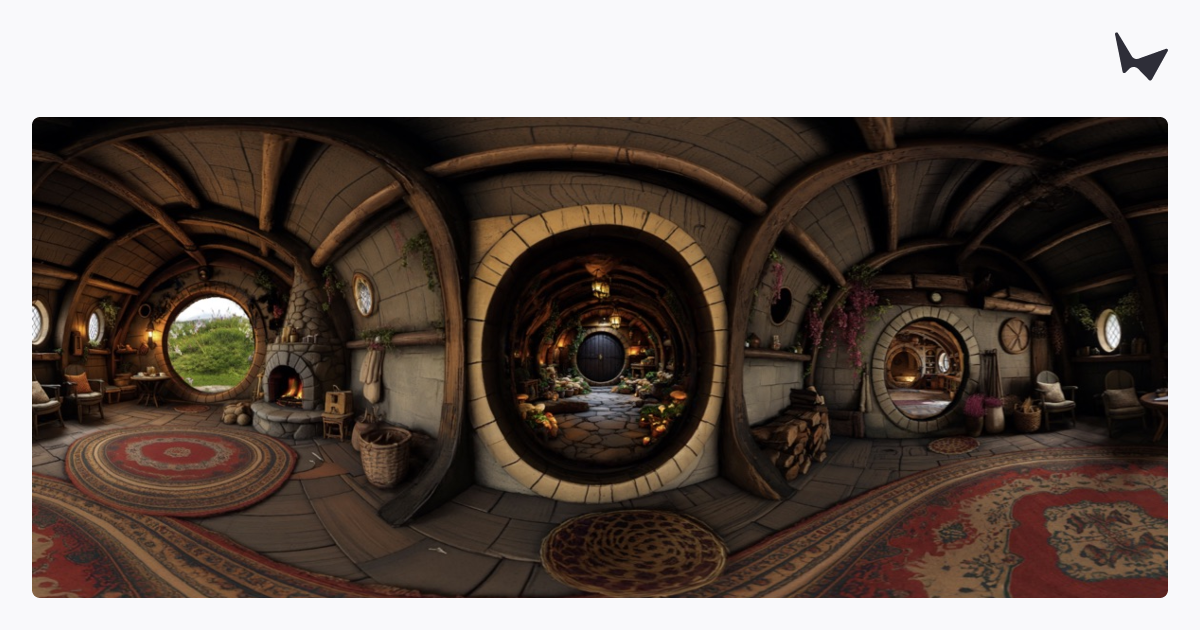
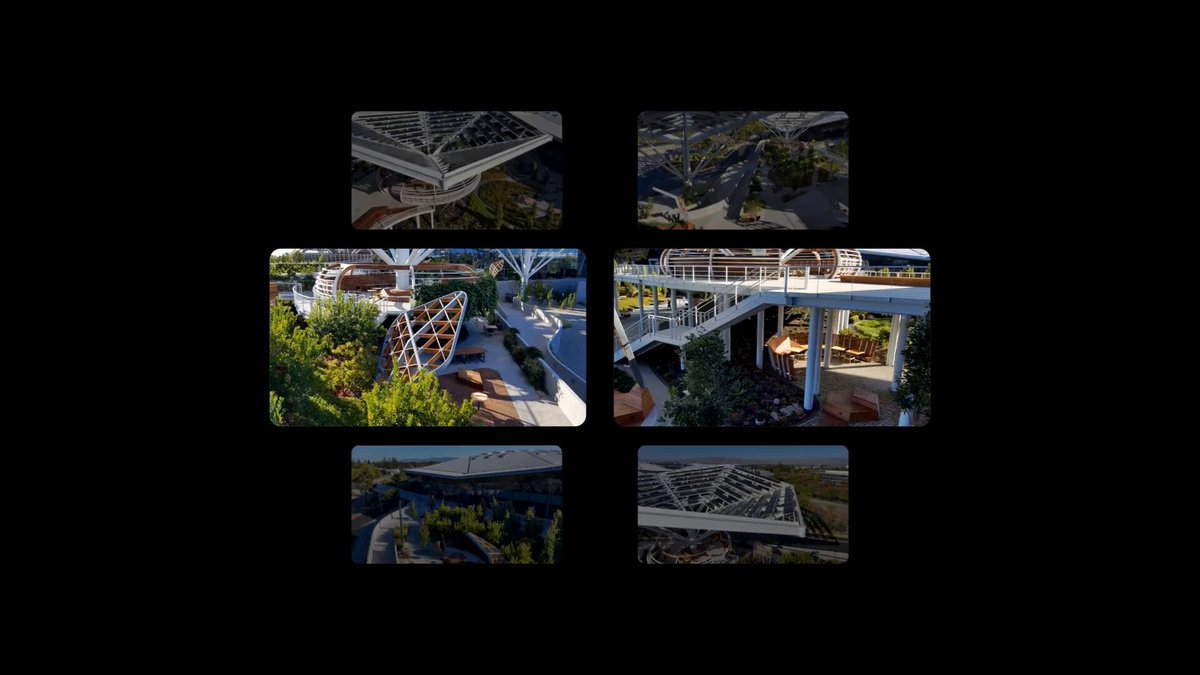
World Labs describes Atlas as a model that generates views of a scene using reference images and explicit camera positions. Each image is attached to a location in a shared spatial context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition →, letting creators specify where the camera should move. The model also invents plausible content outside the supplied views. Adding photographs gives it more observed information to work from, so the distinction between reconstruction and invention depends on how much of the scene was actually captured. The Atlas announcement explains this approach.
Terms in this piece · Glossary
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
grounding — Tying a model's answers to checkable sources — retrieved documents, live data, tool results — instead of letting it answer from memory alone.