RL Systems: Mind the Gap — Matching Trainer and Generator Throughput
- Source
- newsletter.semianalysis.com
- Author
- Kimbo Chen
- Date
Context
Reinforcement-learning systems need a steady supply of useful practice attempts, not simply large amounts of generated text. SemiAnalysis's systems study describes a generator attempting tasks, an environment scoring the results, and a trainer using those results to update the model. If accepted attempts arrive too slowly, training hardware waits.
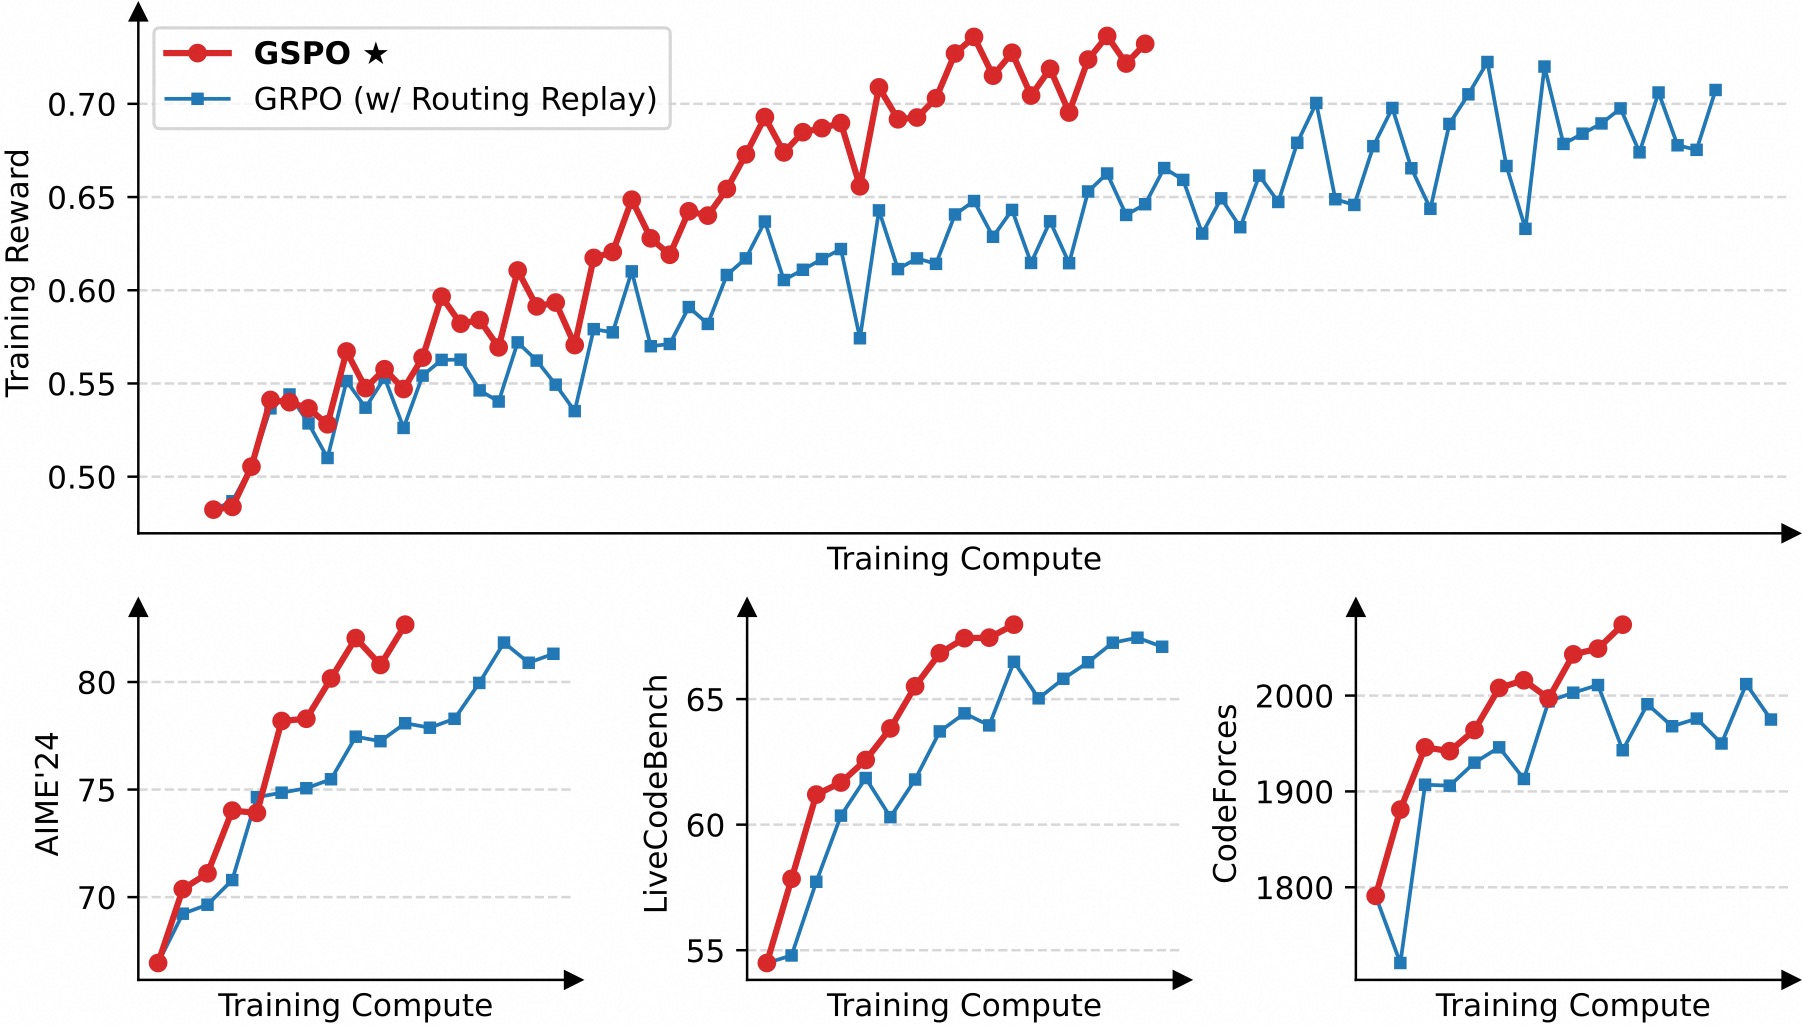
Task difficulty affects that supply. In the group-relative method discussed, attempts are rewarded according to how they compare with others answering the same problem. When every attempt receives the same score, the group provides no relative learning signal. Faster generation therefore helps only when it produces enough usable training examples.
- GRPO scores each attempt against the average of its own group, so a prompt only teaches when its attempts disagree. If every rollout passes or every one fails, the advantages are all zero and the batch produces no gradient at all.
- Picture a queue between two machines. Generator slower than trainer and the trainer idles between steps. Generator faster and rollouts pile up and age, so the trainer is learning from a policy the model has already moved past.
- Strictly on-policy RL makes the generator wait for every weight update. PipelineRL pushes new weights mid-flight, so a single sample is part old policy and part new. That accepted staleness is the price of keeping both halves of the cluster busy.
- The slowest rollout in a group sets when the group finishes, which is why cold-start time, not just generation speed, lands directly in end-to-end throughput and why sandbox vendors obsess over startup latency.
- RL environments are hostile to their own infrastructure. A model exploring freely might create a million files and exhaust the sandbox, so orchestration has to detect and recover from resource blowups rather than assume well-behaved code.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
- sandbox — An isolated environment where AI-generated code or agent actions run without being able to touch anything real.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
“RL training system efficiency is a matter of queue health.”
“RL training is as much of an infrastructure problem as an algorithm one.”
“We hope this shows that sincere collaboration and sharing, rather than hostile competitions and information hiding, propels science forward.”
“A rollout group where every rollout has the same reward produces zero advantage and contributes no training signal.”

Checking sign-in…
Loading comments…