GSPO: Towards Scalable Reinforcement Learning for Language Models
- Source
- qwenlm.github.io
- Author
- Qwen Team
- Date
Context
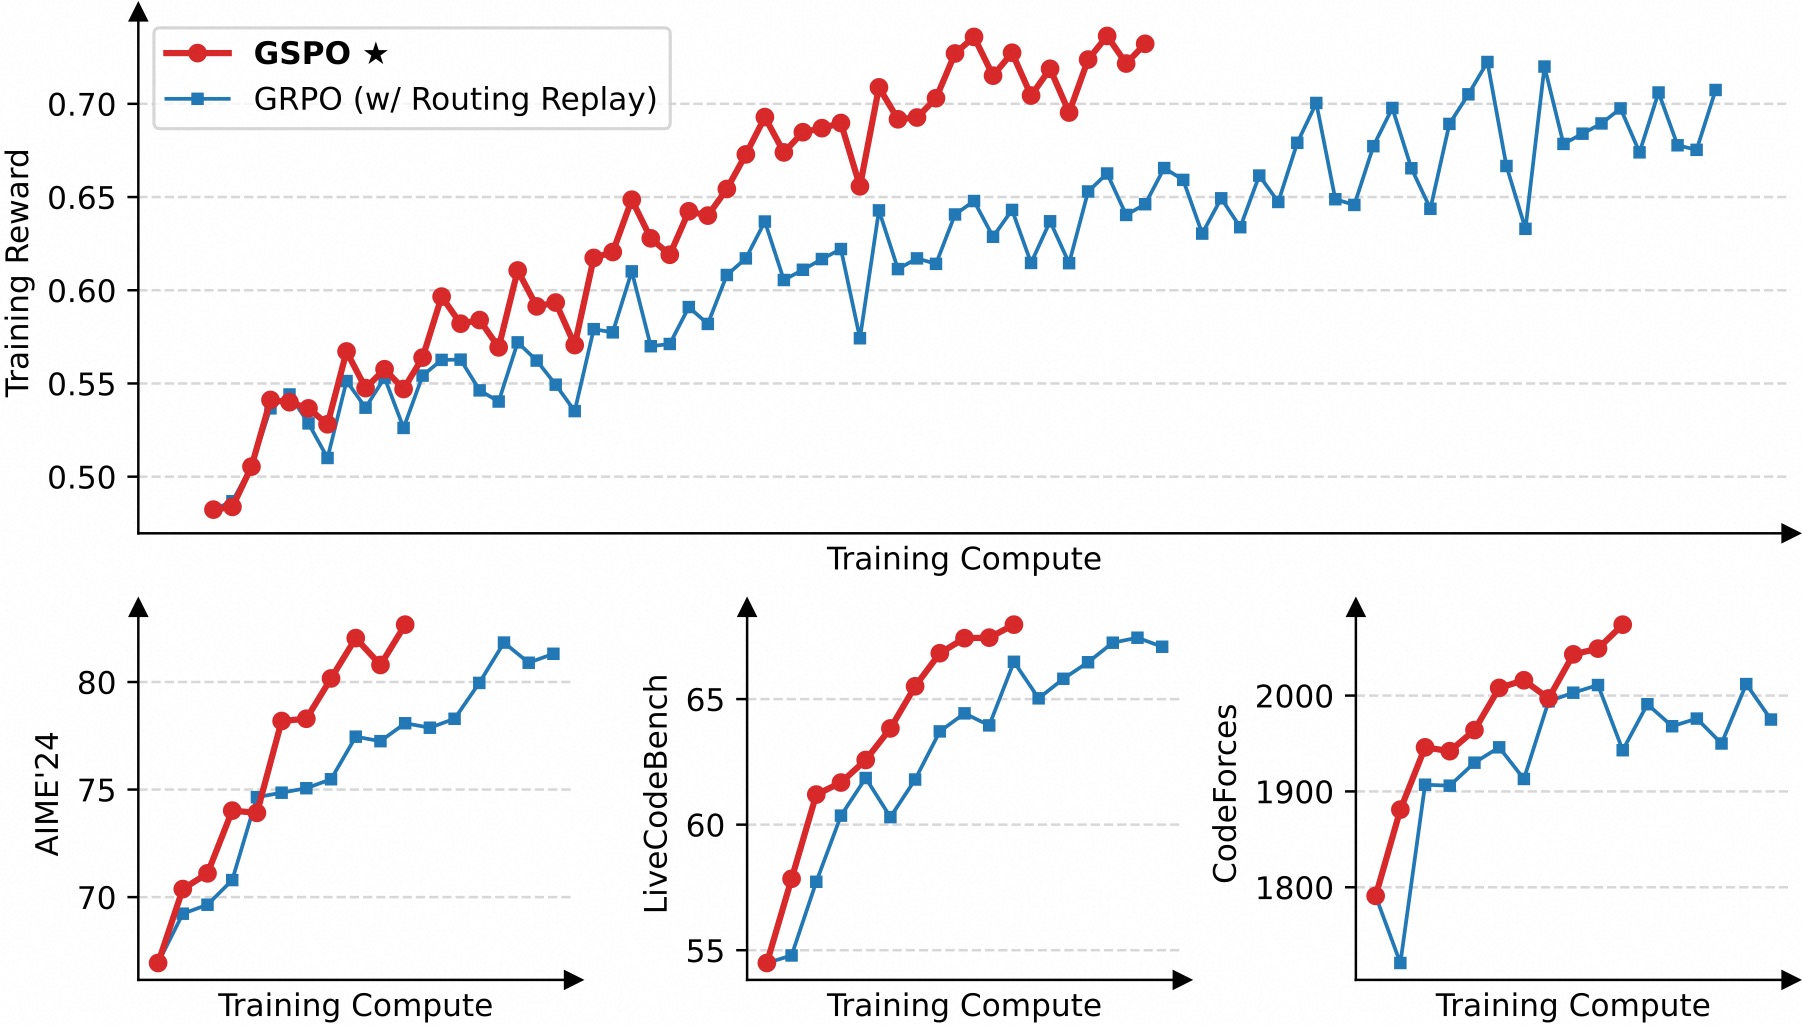
Qwen's GSPO training method changes how reward-based learning limits updates to a . It compares the probability of a complete generated answer under the old and updated models, adjusts for answer length, and clips that ratio to constrain the update. The aim is a less noisy learning signal than applying the corresponding operation separately to each generated text unit. The research account reports better training efficiency in its Qwen3-30B-A3B experiment.
The comparison also exposed an infrastructure difference. The baseline needed to record and replay which expert components had been activated to train reliably; GSPO worked without that workaround. Within the reported setup, the change simplified training while improving performance at the same training cost.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
“However, we observe that existing RL algorithms (such as GRPO) exhibit severe instability issues during long training and lead to irreversible model collapse, hindering further performance improvements with increased compute.”
- clipScaling to long-horizon synthetic environments with GRPOAI Engineer
- postSDPO Trains Models With Natural-Language Feedback Instead of Scalar RewardsStanford AI Lab
 articleGRPO Beyond English: A Large-Scale Study of GRPO in Non-English and Multilingual SettingsKonstantin Dobler, Federico Scozzafava, Jonathan Janke, Mohamed Ali, Simon Lehnerer
Checking sign-in…
Loading comments…