NVIDIA Nemotron 3.5 Super VL Powers Specialized Agents with Multimodal Reasoning
- Source
- developer.nvidia.com
- Author
- Michelle Horton
- Date
Context
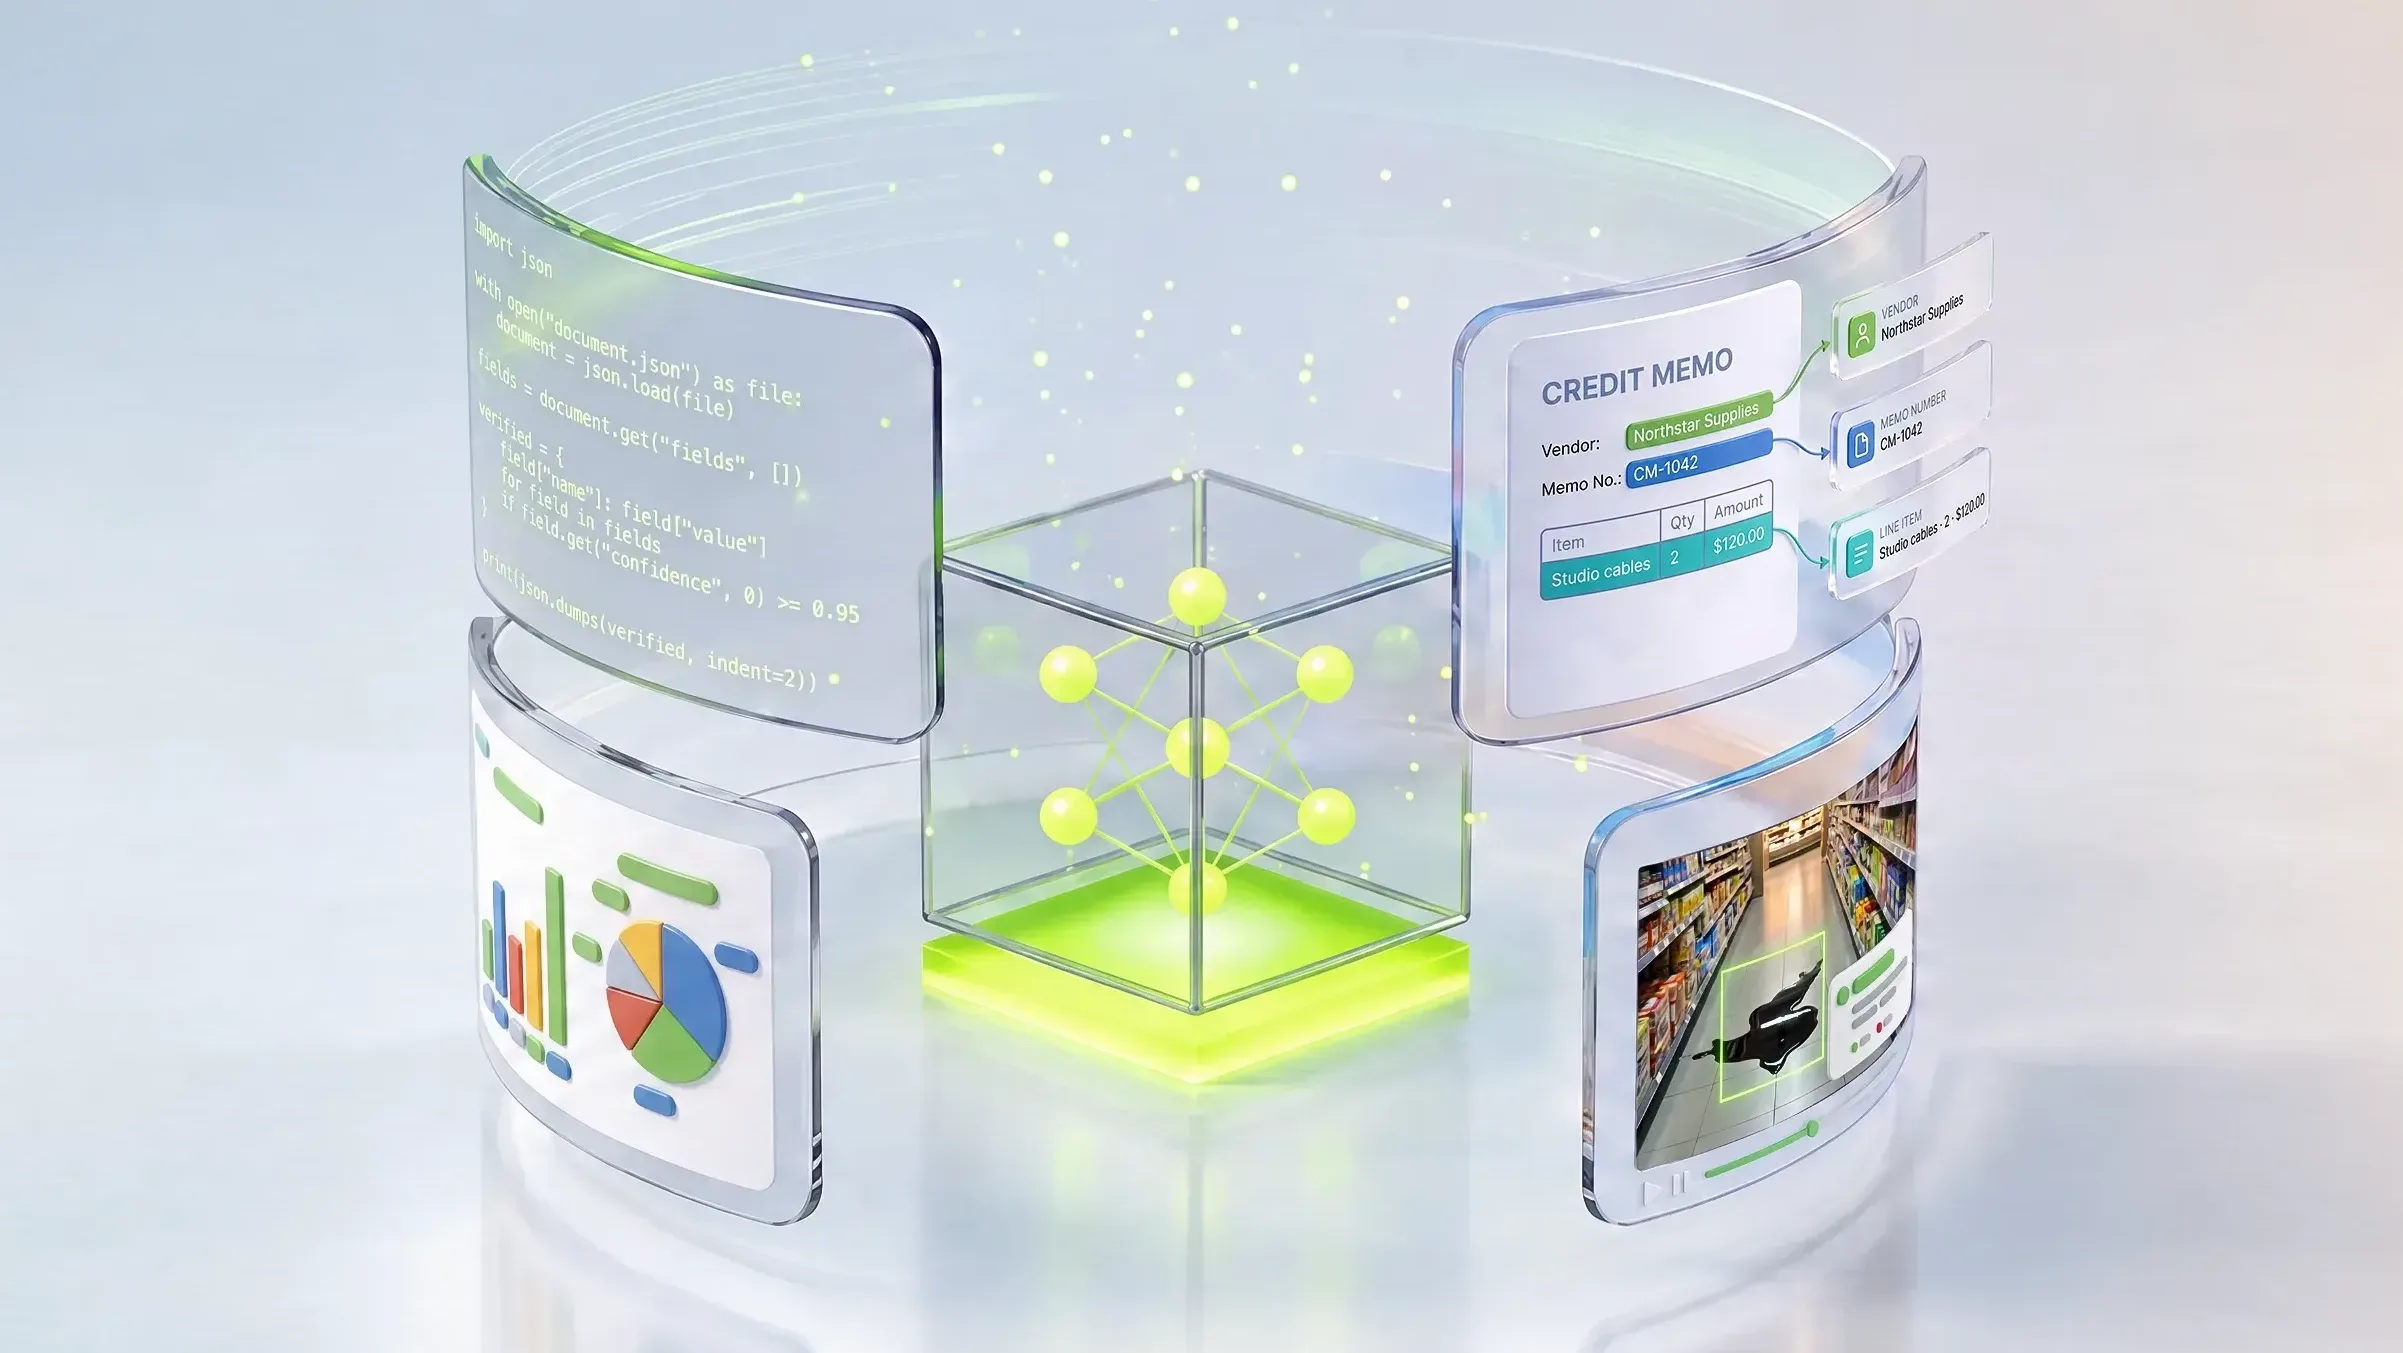
NVIDIA built Nemotron 3.5 Super VL to be the specialist in a team of models: not the smallest, fastest model for high-volume text, and not the largest model that plans and orchestrates, but the one that does multistep work needing reasoning, tool use and visual understanding together (NVIDIA Technical Blog). It is a 120B-parameter model that activates 12B parameters per token, and it reads text, images, documents and video itself, so an agent that has to interpret a chart and then act on it does not need to hand context to a separate vision model.
Much of the post is about what makes the model fit that middle role. It was distilled from the larger Nemotron 3 Ultra, and on two agent evaluations NVIDIA reports, Hermes Bench and LangChain's behavioral evals, it scores above Ultra (63.44% versus 56.33%, and 87.05% versus 84.3%). The rest of the engineering targets the fact that agents call a model again and again with largely the same inputs. A method NVIDIA calls LiLiCorr drafts several tokens and checks them together, up to 2.3x faster on a DGX Spark; a built-in drafter does similar work; weights are stored in the 4-bit NVFP4 format, with extra training so the smaller model keeps the original's accuracy; and caching reuses the work already done on repeated system instructions, tool definitions and history. In a data-center test on 16 B200 GPUs, routing requests to the GPU that already held a session's cache served up to 8x as many users and cut time to first token by 85%.
The model ships as open weights with training data and recipes, and NVIDIA's pitch is that companies will post-train it on their own documents, tools and policies. The customer results are partner results as NVIDIA reports them, and partly forward-looking: NVIDIA says inference cost for Scale AI's vendor-credit workload at Skydance will fall 40x and latency 5x, Ramp expects up to 50% higher throughput and 10x lower latency on receipt processing, and AI21 and Alice's post-training for threat-intelligence work improved accuracy by 41%.
- NVIDIA reports Super VL scores 63.44% on Hermes Bench and 87.05% on LangChain evals, ahead of Nemotron 3 Ultra (56.33% and 84.3%). On the CharXiv chart benchmark it scored 80.8%, or 84% with Python code interpretation.
- LiLiCorr speculative decoding scores token candidates jointly across a whole draft with a lightweight network. NVIDIA recommends it on DGX Spark and says it gives up to 2.3x faster generation than no speculation.
- The NVFP4 checkpoint uses 4-bit weights and activations on Blackwell, and on other GPUs runs with 4-bit weights and 16-bit activations. -aware distillation also lets the sit in NVFP4 instead of FP8.
- Super VL was distilled from Nemotron 3 Ultra, then refined with multi-teacher on-policy distillation in which specialized text and vision teachers score the model's own responses.
- Partner figures are projections or reports: Scale AI expects 40x lower inference cost and 5x lower latency for Skydance, Ramp expects up to 50% higher throughput, and AI21 and Alice report a 41% accuracy gain.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
- speculative decoding — A speed trick where a small model drafts several tokens ahead and the big model verifies them in one pass, often doubling generation speed.
- quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.
- KV cache — The memory a model keeps about text it has already read, so generating each new token doesn't require reprocessing the whole conversation.
Checking sign-in…
Loading comments…