Measuring Human Performance on ARC-AGI-3
- Source
- arcprize.org
- Author
- Greg Kamradt
- Date
Context
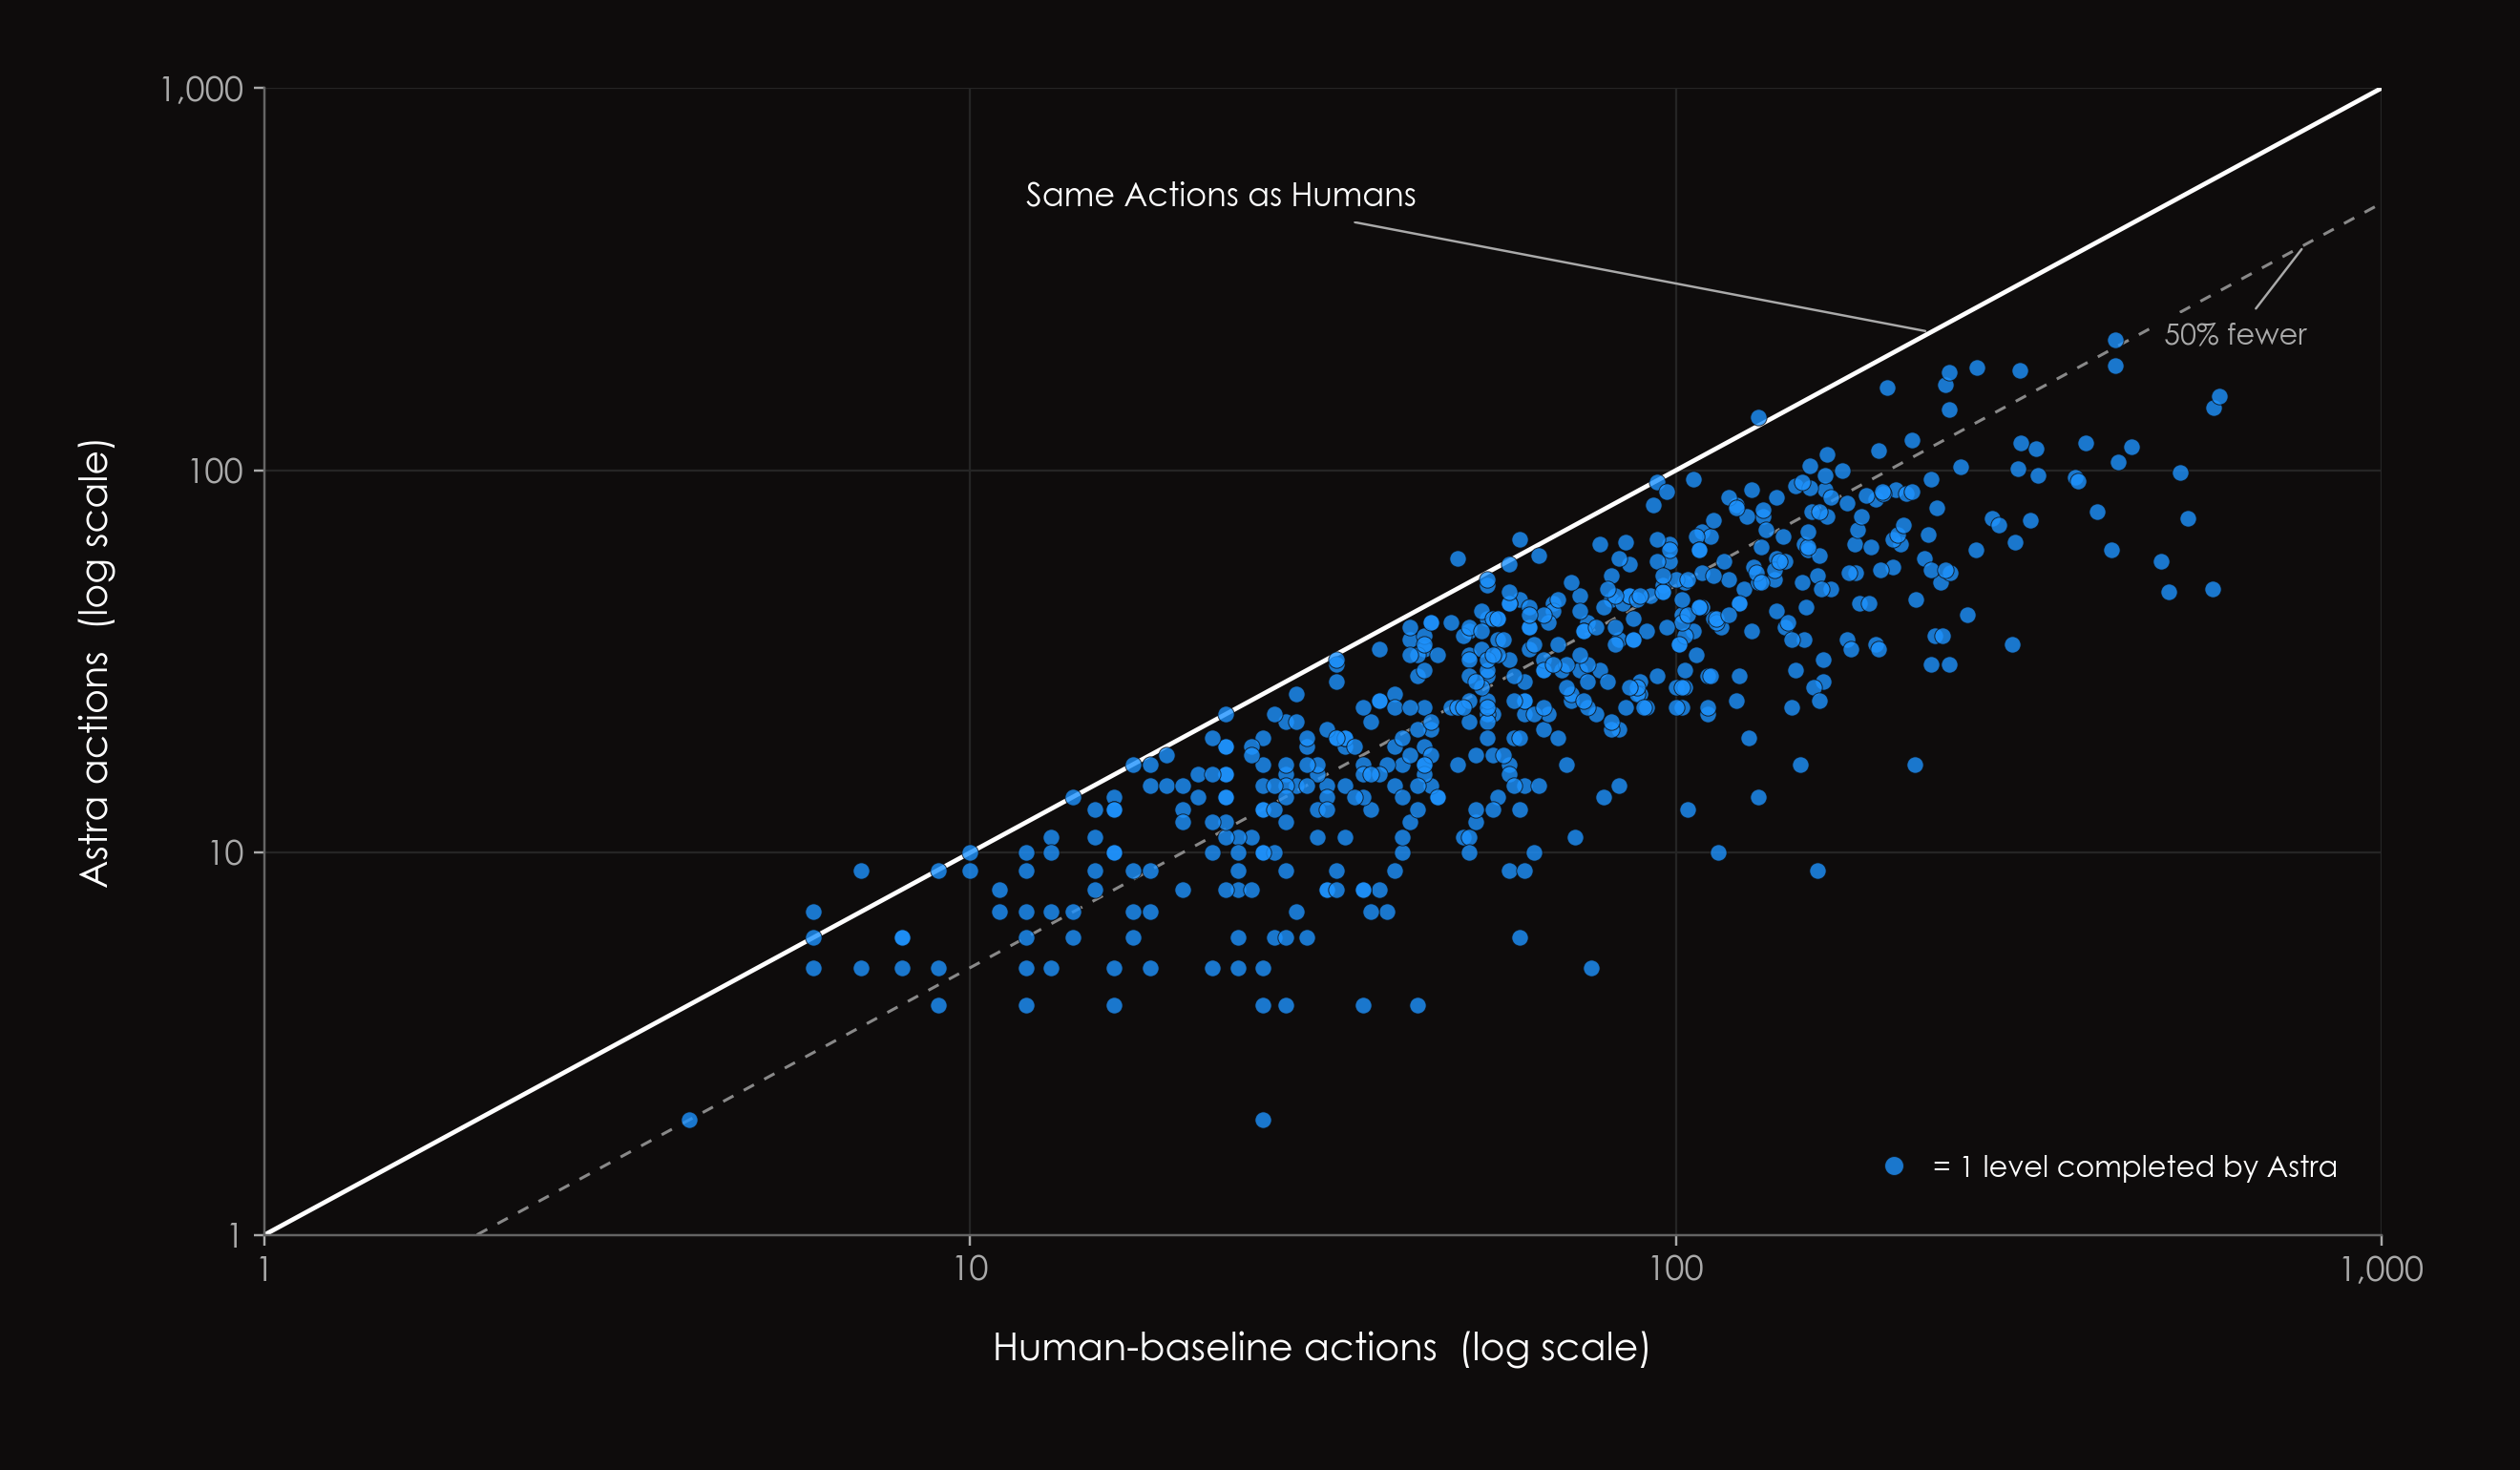
Human-solvable does not mean every human solved every task. ARC Prize's human-baseline study required each retained environment to be completed by at least two independent participants. Individual completion rates varied considerably, so the claim describes coverage of the task set rather than a perfect score for the typical participant.
The post also announced scoring changes based on submitted scorecard data. Moving the baseline from the second-best human attempt to the median reduces the influence of an unusually efficient run, while a higher per-level cap gives strong performance elsewhere some room to offset a weaker level. A model's score therefore reflects both its actions and the 's choices about what counts as representative human performance.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Checking sign-in…
Loading comments…