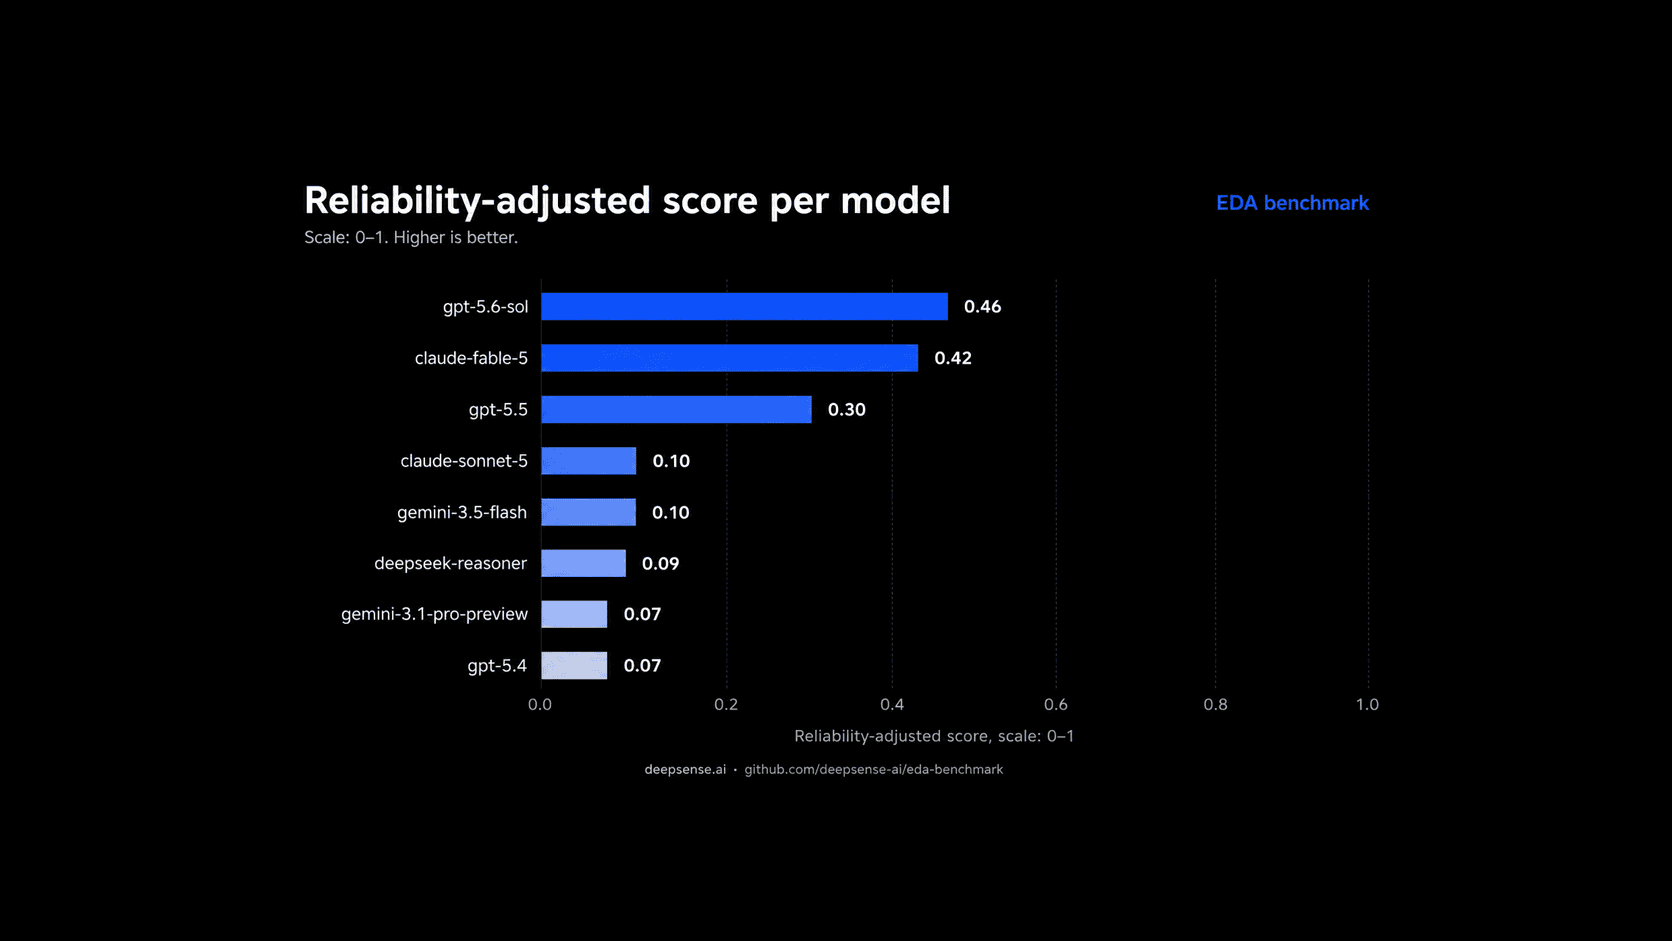
Repeating the same analysis task can change which model looks strongest. In deepsense.ai's July benchmark update, models attempt ten synthetic data-analysis tasks five times each. Anthropic's Claude Fable 5 has the highest average score, 0.50, ahead of OpenAI's gpt-5.6-sol at 0.48. After the benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → penalizes variation between runs, the order reverses: gpt-5.6-sol scores 0.46 and Fable 5 scores 0.42. The adjusted ranking expresses a preference for repeatability. It helps distinguish strong average performance from consistent execution within this particular task set.
Terms in this piece · Glossary
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.