Intelligence Index v5 goes majority-private and adds agentic coding and science
- Source
- x.com
- Date

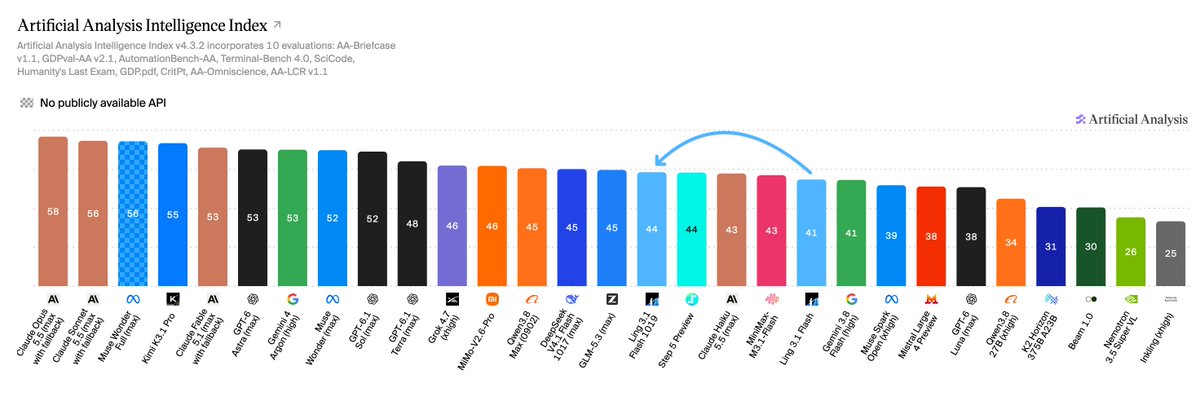
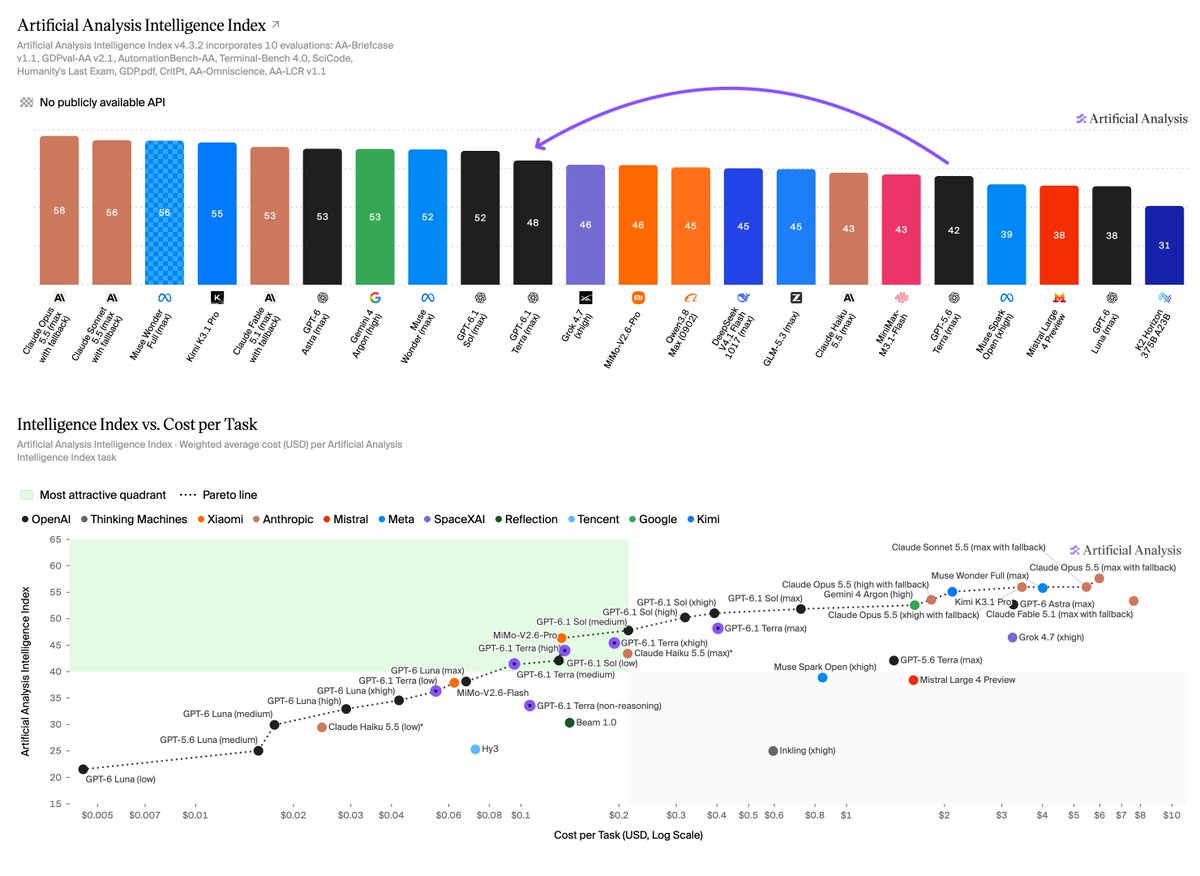
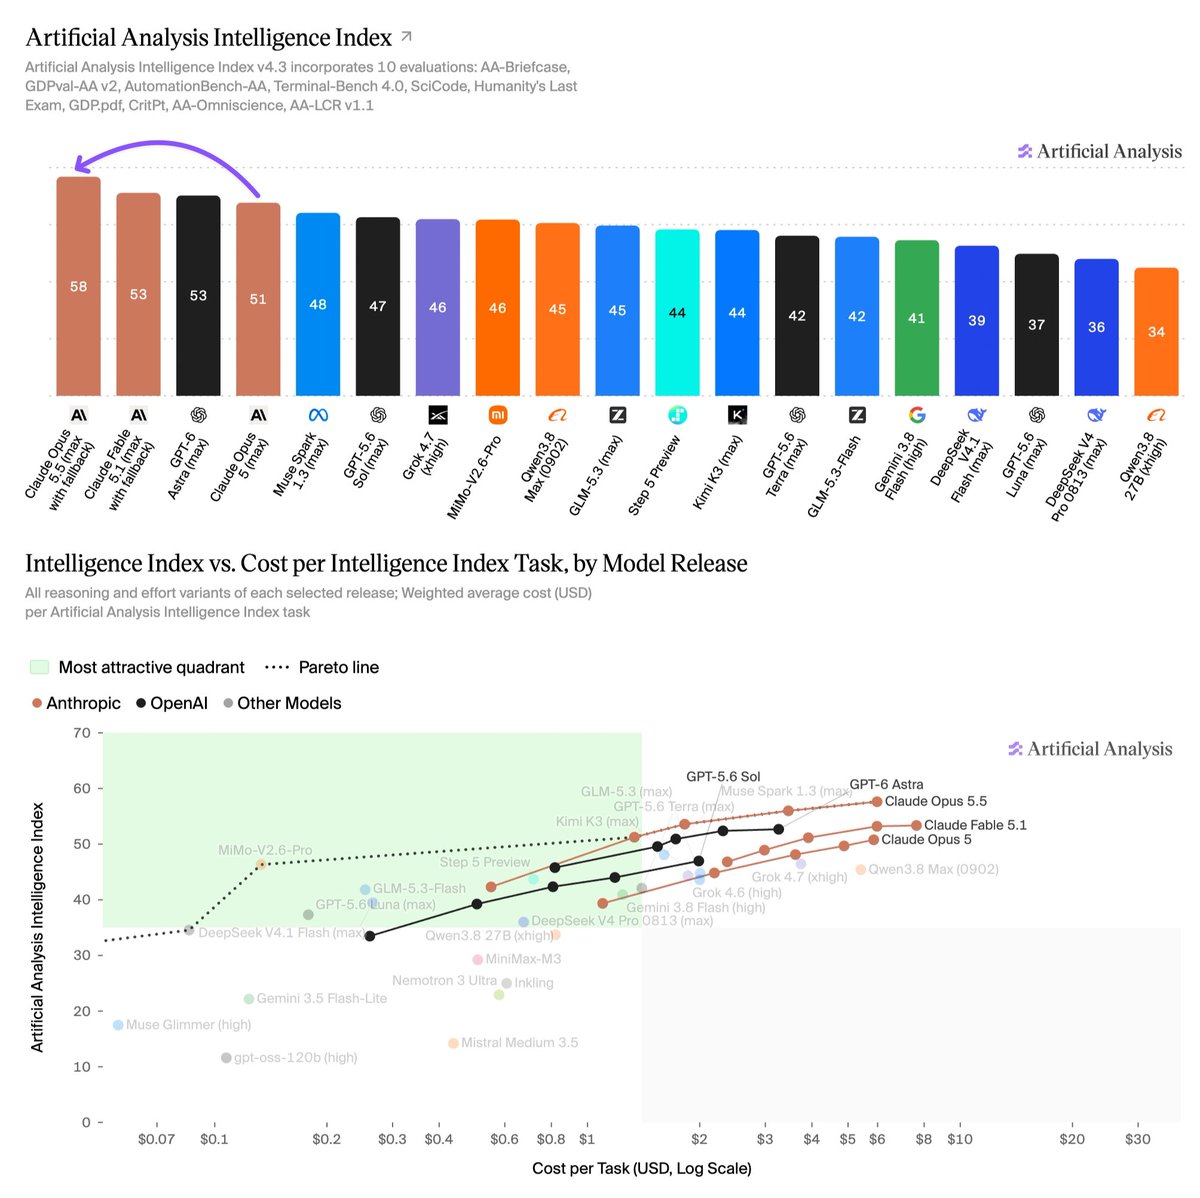
Announcing Artificial Analysis Intelligence Index v5, featuring 2 new benchmarks and 3 upgrades. For the first time, the majority of the Index is built on private datasets The Artificial Analysis Intelligence Index is our composite measure of model capabilities across tasks reflecting real-world usage today. v5 is our biggest upgrade since v4 launched in January. With v5, 60% of the Index is now based on evaluations with private test sets or held-out answers. Alongside Intelligence Index v5, we’re launching the Artificial Analysis Progress Index v1, which tracks model capability over time on one continuous scale. New to the Intelligence Index: ➤ FrontierCode 2.0: Cognition's newly-launched private benchmark of real-world coding tasks, graded on whether a repository maintainer would merge the agent's change ➤ Terminal-Bench-Science: 70 agentic scientific research tasks, run in a terminal environment Upgraded: ➤ HLE-Diamond (replacing Humanity's Last Exam): a refined 1,000-question version of Humanity's Last Exam, split evenly between reasoning and knowledge questions ➤ AA-Omniscience v1.1: An updated dataset with saturated and public set questions removed, new questions…
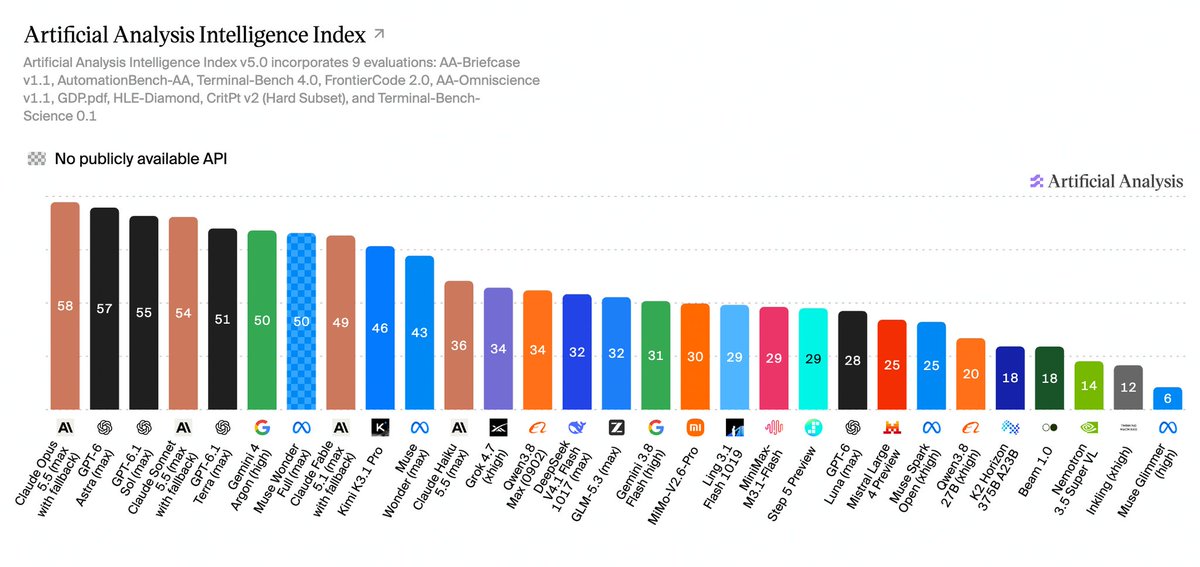
The index now relies mostly on private test sets and adds maintainer-merge coding and terminal science tasks, so rankings are harder to game. The open-weights gap widened to 12 points and cost per task spans over 13x.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
Checking sign-in…
Loading comments…