Vals AI's New Benchmark Shows No Model Clears 30% on Iterative Coding
- Source
- x.com
- Date

Existing coding benchmarks stop at the first working version. We are releasing Vibe Code Bench 1-100 today, to measure what comes next. This benchmark asks if models can handle a large number of modifications to a product, without breaking what already works.

Context
Vals AI released Vibe Code Bench 1-100, a follow-on to its earlier coding that stops grading once an application first works. The new version starts from a complete, passing application and feeds a model up to ten sequential product-manager-style change requests, the kind of ongoing feature work a real engineer receives, then checks both whether the new request works and whether roughly a third of the test suite covering earlier features still passes. Vals AI's benchmark page reports that at launch, the top-scoring model, Claude Opus 5.5, reached only 30.36% overall, and close to 39% of graded failures involved breaking something that previously worked rather than only failing to finish the new request. That points to non-regressive iteration, not first-pass code generation, as the harder unsolved part of agentic coding.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
 articleBehind the Scenes of Vibe Code Benchwww.vals.ai
 articleVibe Coding: Practice, Performance, Productivity, and Risk -A State-of-the-Art ReviewDominik L. Michels, Mutaz Abu Ghazaleh, Francois Lazzari, Nabil Kassem, Jonathan Klein
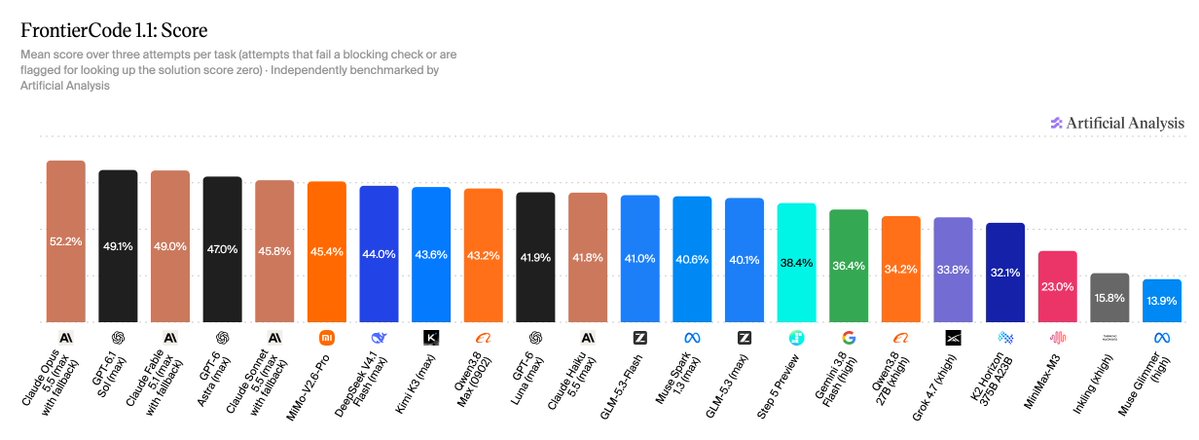 postFrontierCode 1.1 leaderboard grades coding models on merge-readinessArtificialAnlys
Checking sign-in…
Loading comments…