Making Knowledge Distillation Cheap Enough to Run at Scale
Source
huggingface.co
Date
Context
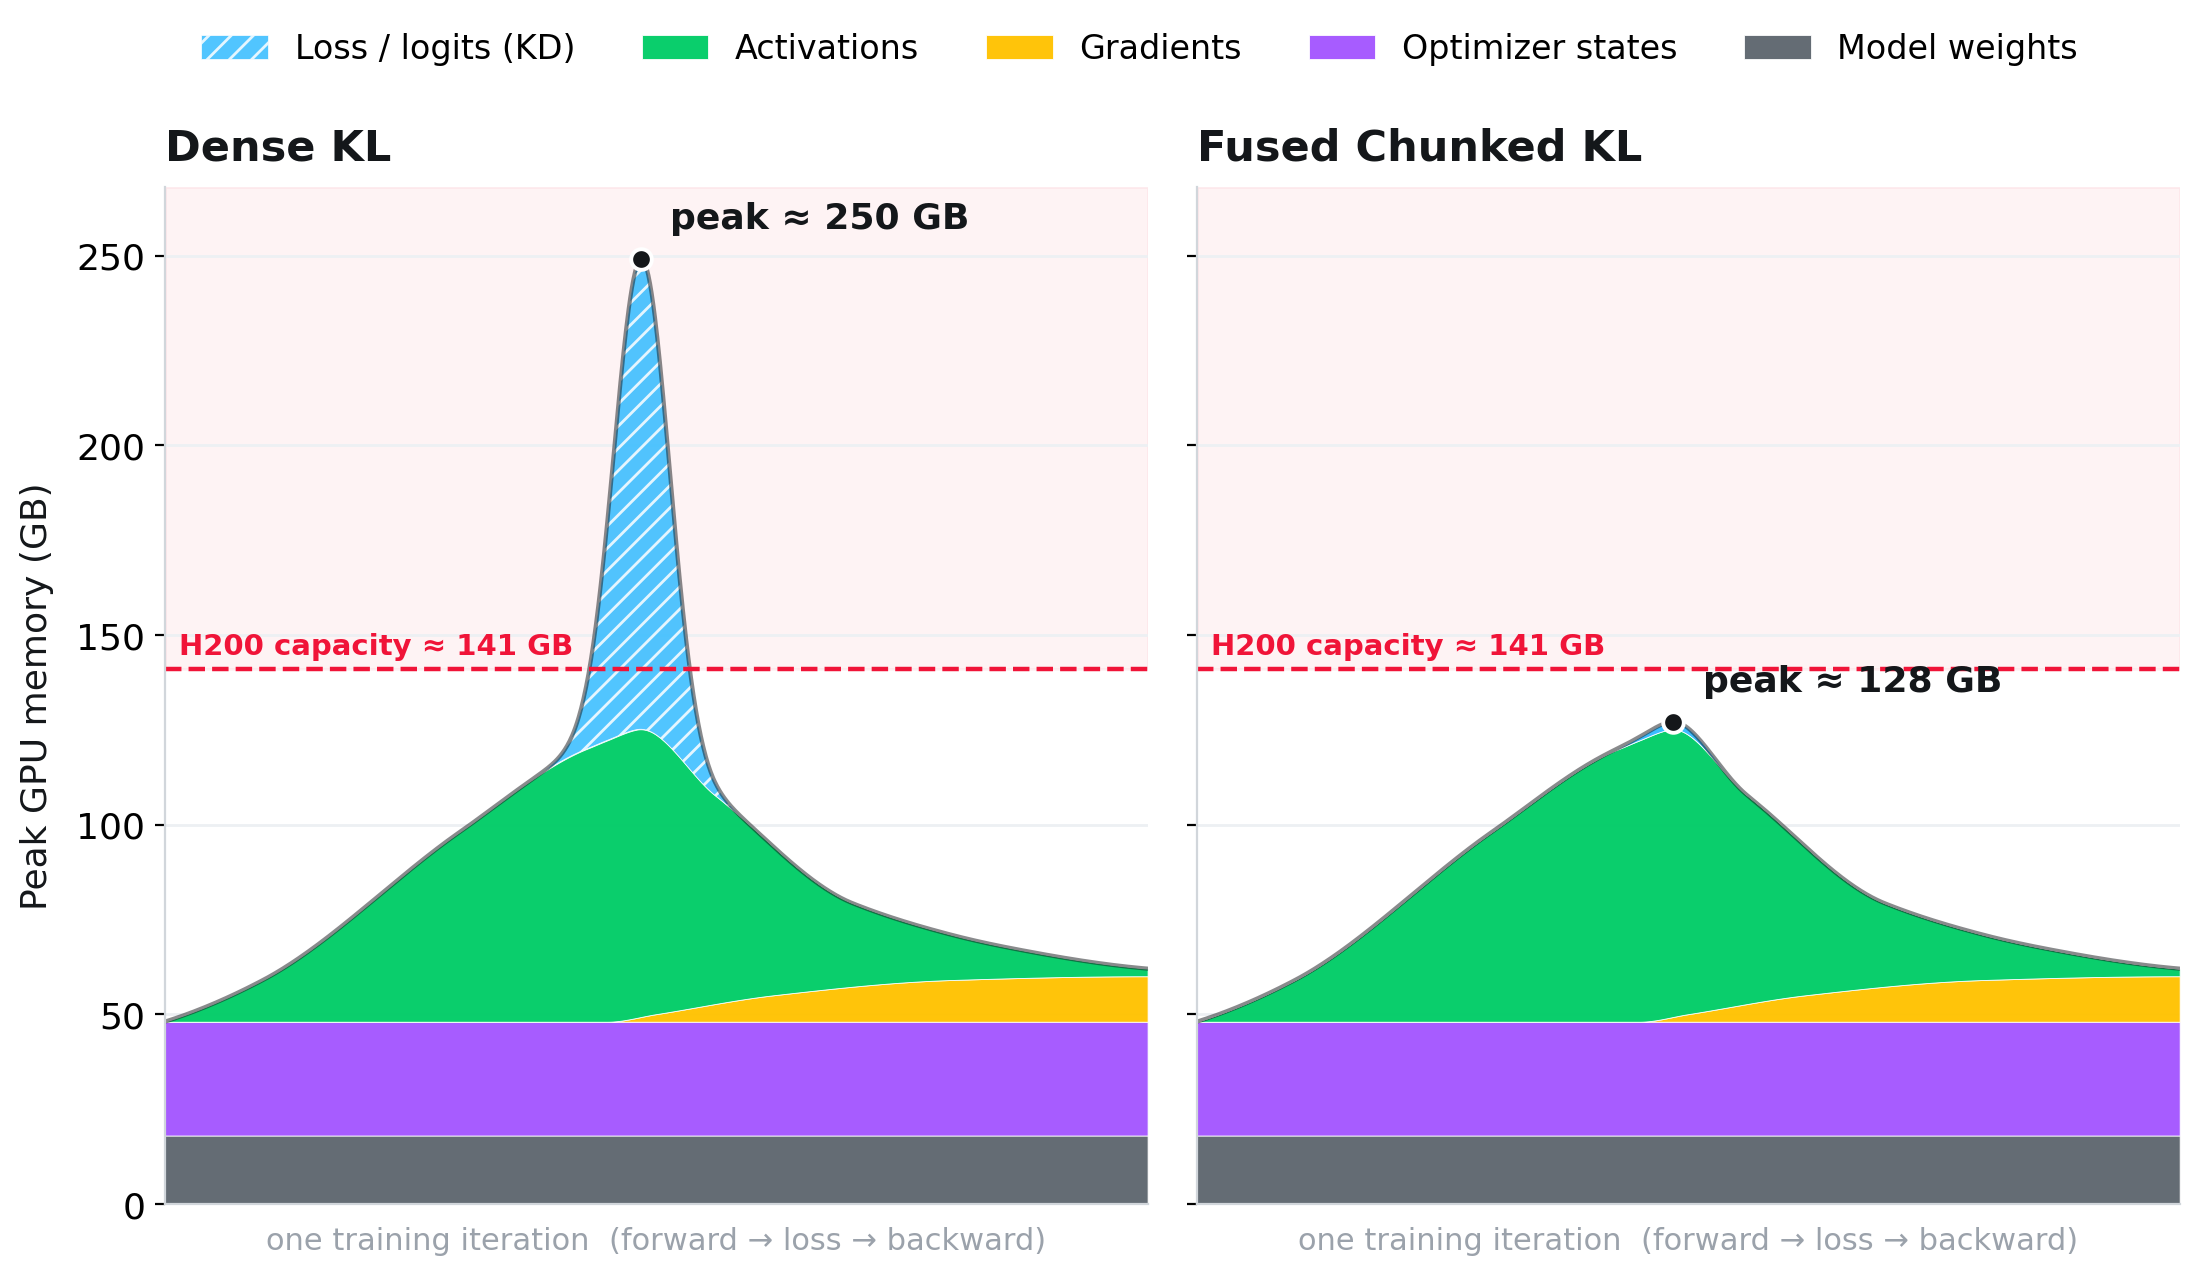
Training a smaller model to imitate a larger one need not keep both models in GPU memory throughout training. Multiverse Computing's method first saves the teacher's 100 highest-scoring next-tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → predictions at each position. The student then learns from that cache. A second change computes the comparison in small chunks, recomputing intermediate values during the backward pass instead of retaining a full prediction matrix. In the reported single-H200, 8K-context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition → experiment, peak memory fell from 102.8 GB for online distillationTraining a small, cheap model to imitate a big one's outputs, keeping much of the capability at a fraction of the cost.Full definition → to 58.3 GB for the fused offline version. The tradeoff is extra recomputation to reduce memory demand.
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
distillation — Training a small, cheap model to imitate a big one's outputs, keeping much of the capability at a fraction of the cost.