[AINews] Claude Opus 5.5, the new default model for AINews — and everybody cuts prices 40-50%
Source
latent.space
Date
Context
AINews, the newsletter section of Latent Space, says it is switching its own writing workflow to Anthropic's Claude Opus 5.5. In its launch-day issue, the editors ran the same section with Opus 5.5 and GPT-6 Sol and report that the difference was night and day. They single out Anthropic's launch claim that the model puts the most important information up front and follows writing rules it is given, and say they can confirm it. That is a more direct reason for the switch than the benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → rankings in the same issue: the editors preferred the result on the job they needed done. It is a reported editorial preference, not a controlled evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition → showing the model writes better for every audience or task.
Terms in this piece · Glossary
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
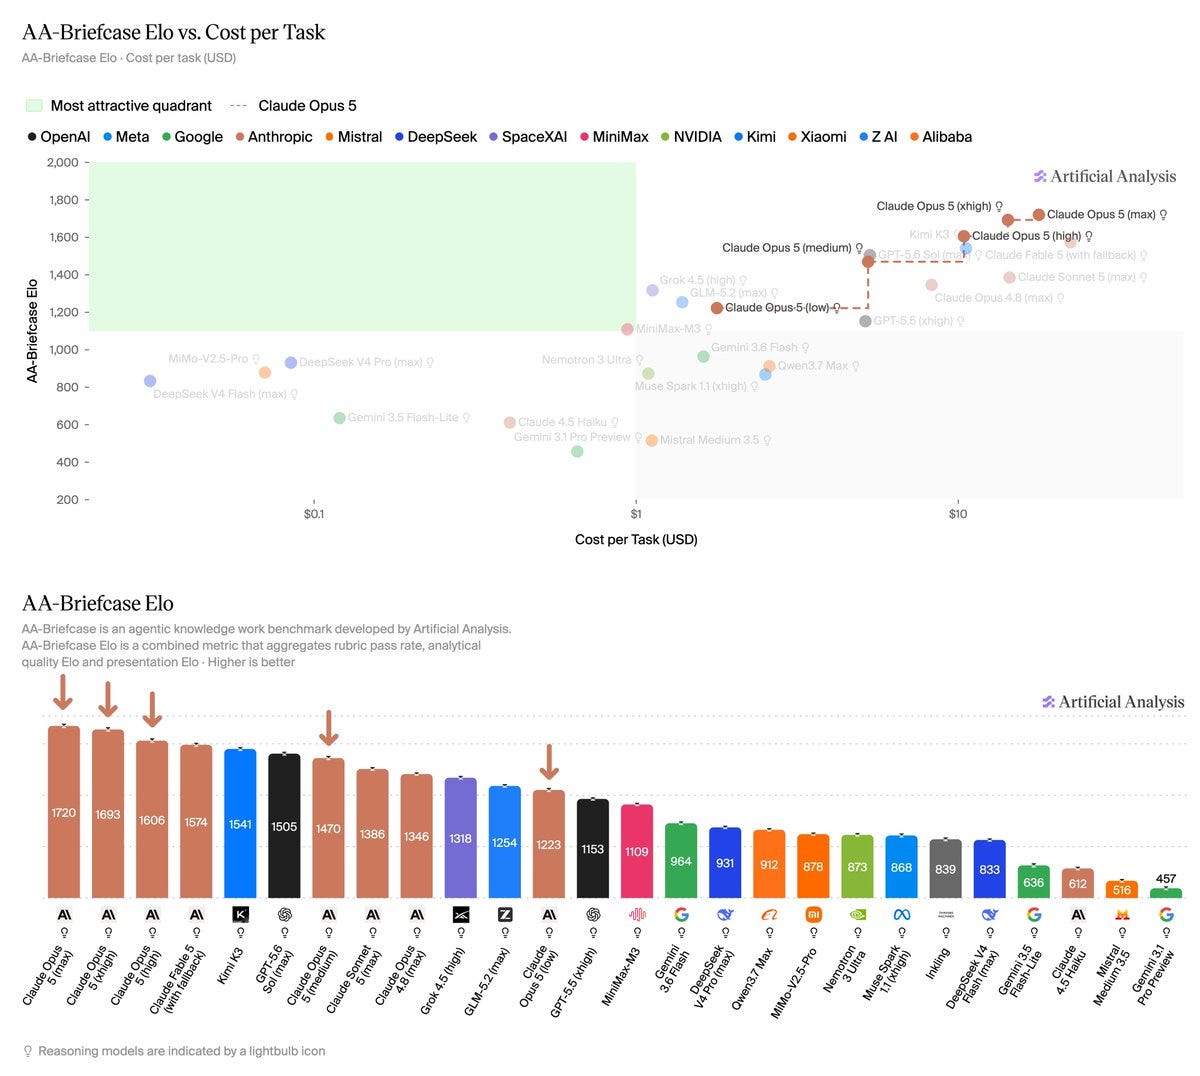 article[AINews] Claude Opus 5: Fable-level performance at Opus price (half Fable)Latent Space
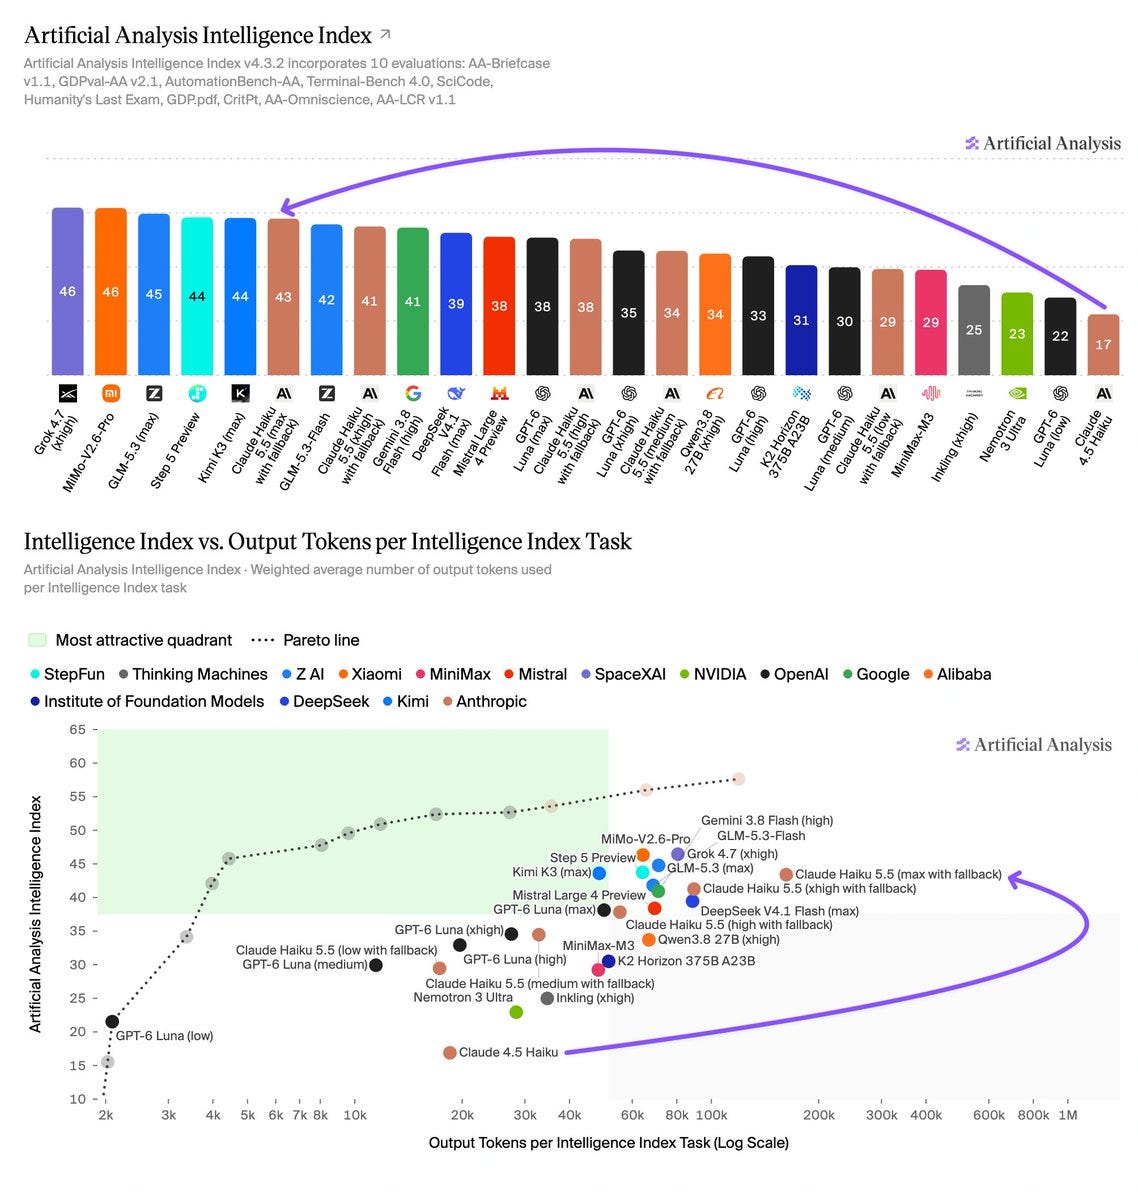 article[AINews] Claude Haiku 5.5 — better than GPT-6 Luna at the same pricingwww.latent.space
 article[AINews] Claude Fable/Mythos 5.1: new SOTA model, 75% cache price cut but 70% more output tokenswww.latent.space