[AINews] Claude Fable/Mythos 5.1: new SOTA model, 75% cache price cut but 70% more output tokens
- Source
- latent.space
- Date
Context
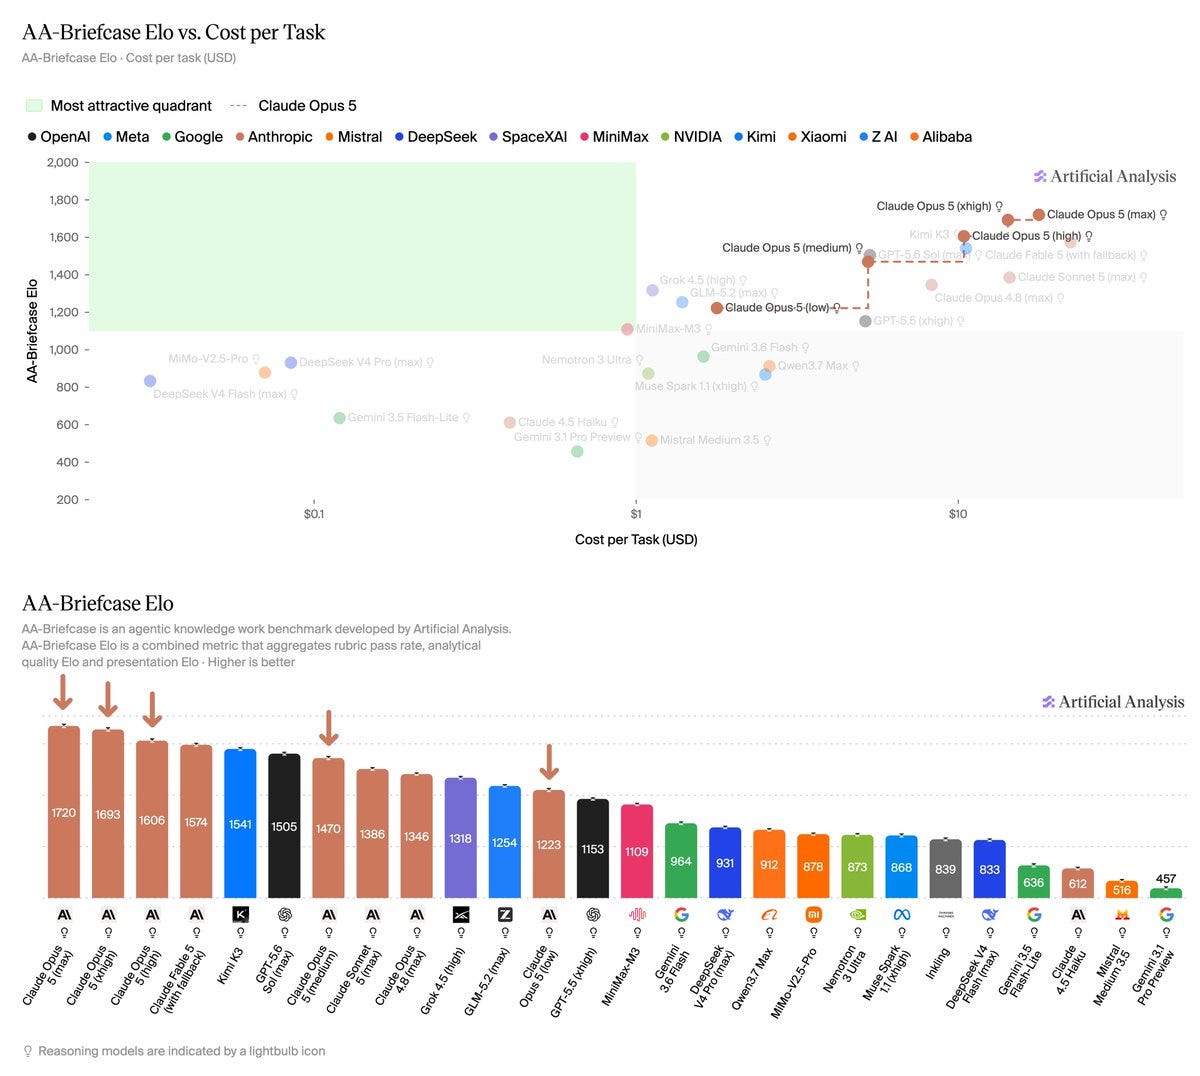
Cheaper cached input did not make Anthropic's Fable 5.1 cheaper on every workload. In its September 1 , Artificial Analysis reported $3.76 per Intelligence Index task at maximum reasoning effort, versus $3.14 for Fable 5. It attributed the increase to roughly 1.7 times as much generated output, outweighing the cache savings. Original evaluation.
The result explains why a unit-price discount and a higher task bill can coexist: the bill depends on both price and usage. These figures describe the evaluator's launch-time task set and effort setting, including the default safety fallback to other models. They are a workload-specific cost comparison, useful when interpreting the release's pricing claims. Evaluation conditions.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Checking sign-in…
Loading comments…