Turning Opportunistic AI Inference Capacity Into Better Ads Recommendations
Source
engineering.fb.com
Date
Context
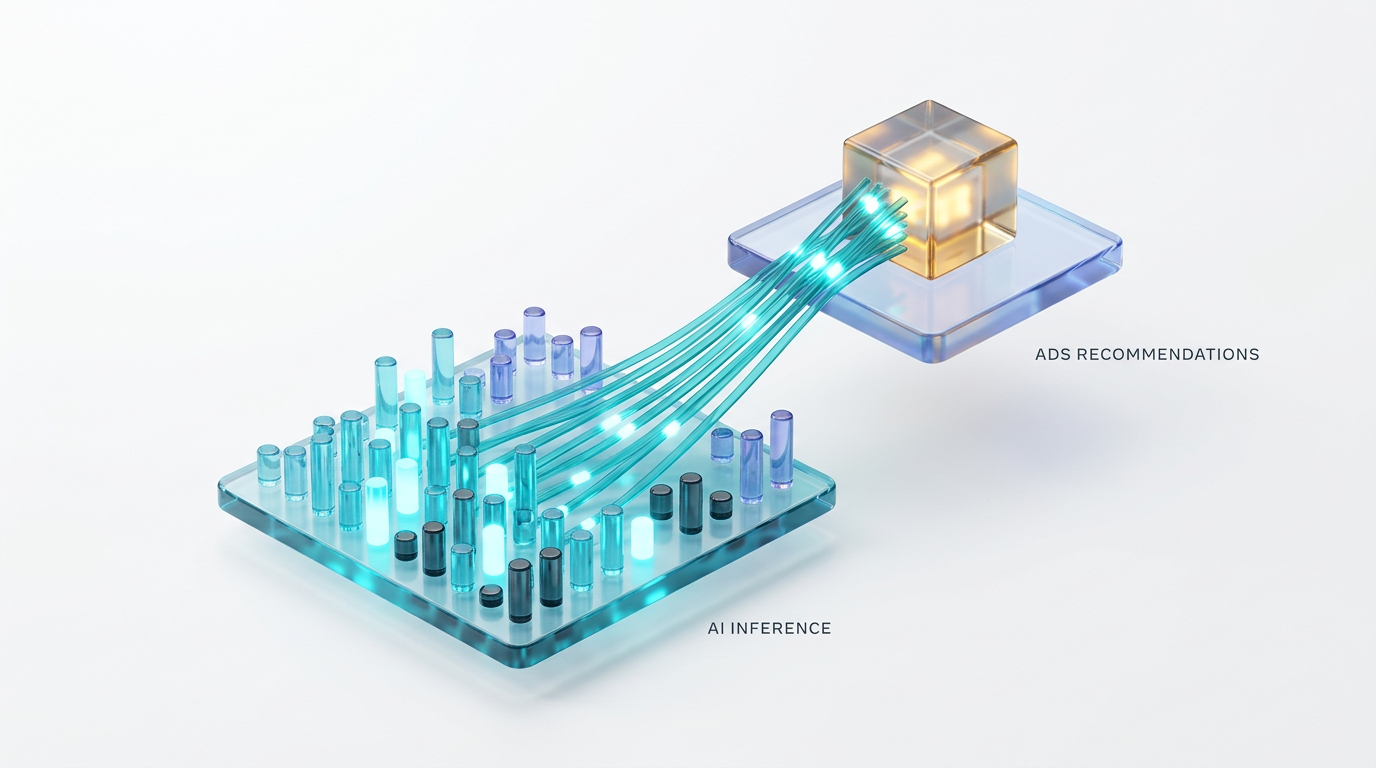
Meta uses temporarily idle computing capacity to do extra work on ad recommendations. Its engineering account describes two ways to spend that surplus: evaluate more candidate ads, or send more requests to a stronger prediction model. The first needs spare CPU and accelerator capacity; the second can use accelerator surplus without substantially increasing upstream CPU work.
The extra work must be removable because other workloads can reclaim the capacity. Separate capacity controls protect baseline serving, while fast local mechanisms discard lower-value optional work before slower central controllers catch up. The design makes recommendation effort adjustable to the resources actually available.
Key takeaways · AI-distilled
Meta lists four causes of locally idle capacity in a constrained fleet: peak provisioning versus demand swings, capacity arriving before models are ready, regional CPU-to-accelerator ratio gaps, and non-portable accelerator types.
The two levers consume different resources: ranking more candidates needs both CPU and accelerator surplus because extra ads pass through retrieval and feature processing, while routing to stronger models uses accelerator-only surplus.
Candidate volume is governed by a central PID controller that reads tail latency, raising the number of ads ranked when latency is under target and cutting it when latency rises.
model routingSending each request to a model chosen by the difficulty of the task, rather than using one model for everything.Full definition → uses an explore-and-exploit process across engagement segments, because, Meta says, the gain from the stronger model does not always track a request's absolute value; exploratory traffic is kept to avoid stale routing.
Since the central controllers react on the order of minutes, servers and clients also shed lower-value opportunistic work on their own within a few milliseconds when capacity is suddenly preempted.
Terms in this piece · Glossary
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
model routing — Sending each request to a model chosen by the difficulty of the task, rather than using one model for everything.