Muse Spark 1.2 adds visual coding, tool-use reasoning and robot orchestration
- Source
- x.com
- Date

Muse Spark 1.2 supports a broad range of multimodal tasks, from turning visuals into working code to translating perception into physical action. It also brings robust audio-visual understanding to enable video-heavy workflows common in real-world enterprise use. Today, we’re sharing new evals and demos that illustrate the breadth of the model’s visual understanding and reasoning capabilities. Let’s start with a demo that shows how Muse Spark parses multimodal observations and calls tools to guide a robot to navigate in an unstructured environment to find a rubber duck. 🧵👇

Context
In the rubber duck demo, Meta's Muse Spark 1.2 acts as the robot's orchestrator rather than its motor control. Meta's technical post describes the model taking the user's instruction, reading what the robot observes, issuing tool calls, checking the results and repeating until the task is finished. Meta does not name the specific tools the robot demos use or say whether the duck scene was a real robot or a simulation.
For tasks that involve handling objects, Meta describes a two-level arrangement. A high-level planner interprets the scene, tells similar objects apart and breaks one abstract goal into subtasks, and a lower-level vision-language-action policy, a model that turns what it sees and an instruction into movements, carries out each subtask. In two of these demos that lower-level policy came from an experimental smaller model in the Muse family, and another demo ran in simulation with simplified grasps.
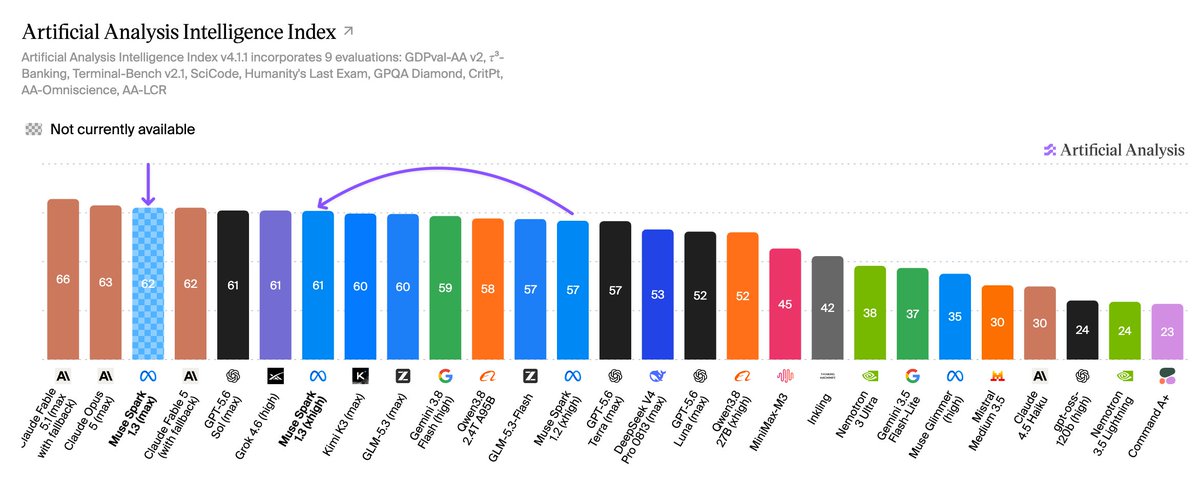
The same post publishes vision evaluations that put Muse Spark 1.2 close to, not clearly ahead of, the comparison models. On ZeroBench it scored 54.0% against 54.6% for GPT-5.6 Sol, and on CharXiv Reasoning it scored 87.6%, slightly below Muse Spark 1.1. These are Meta's own reported numbers, and the robot clips are demos Meta chose, so they show the planning-plus-tools pattern working in selected cases rather than general reliability.
- multimodal — A model that works with more than text — reading images, audio, or video, and sometimes generating them too.

Checking sign-in…
Loading comments…