Learning Word Embedding
- Source
- lilianweng.github.io
- Author
- Lilian Weng
- Date

Context
Word give words learned numeric representations that reflect patterns in their surrounding text. Lilian Weng's 2017 tutorial explains skip-gram: choose a word, use nearby words as prediction targets, and adjust the model's vectors to improve those predictions.
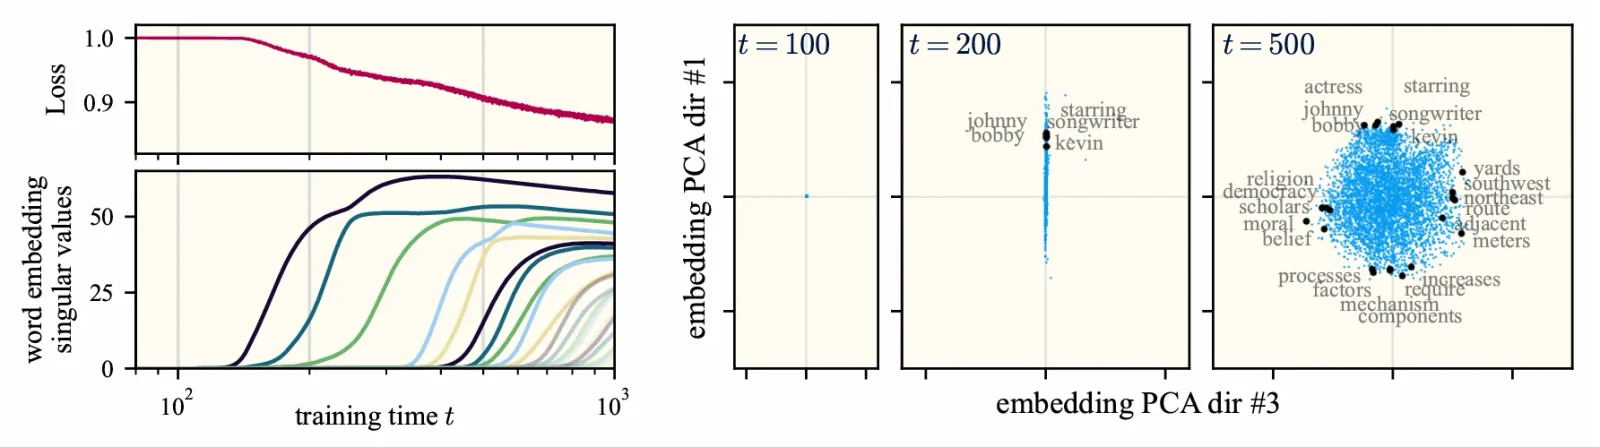
The training examples come from the text's word positions, so people need not label each pair's semantic relationship. Words used in similar contexts can acquire similar representations, making relationships available to a model through compact vectors. These similarities reflect usage in the training corpus. They are a learned representation of those patterns, rather than a direct test that the model understands every meaning of a word.
- embedding — A list of numbers representing a piece of text's meaning, so that similar meanings end up numerically close and can be searched.
“One of the simplest transformation approaches is to do a one-hot encoding in which each distinct word stands for one dimension of the resulting vector and a binary value indicates whether the word presents (1) or not (0).”



Checking sign-in…
Loading comments…