Model Routing Layers and the Prompt Cache Tax
- Source
- alphasignal.ai
- Author
- AlphaSignalAI
- Date
Context
Switching to a cheaper model can introduce a new cost when a long conversation must be processed without an existing prompt cache. In a reported coding-session experiment, the first turn after switching a 60,000- session to Claude Sonnet 5 cost $0.223; the next turn on that model cost $0.020.
Anthropic's caching documentation explains the underlying benefit: unchanged prompt content can be reused at a discounted input rate, with exact matching required. The experiment illustrates why routing costs should include processing carried conversation history. Its particular bills do not establish a universal switching penalty or an optimal routing policy.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
“Claude Sonnet 5 took over a 60,000-token coding session for me mid-way through, and that one turn billed $0.223. The next turn ran on the same model, in the same conversation, and it cost $0.020.”
Adham Khaled
“A cache belongs to one model, so the moment you switch, the model you switched to has to read the whole conversation again, and you pay full price for every token of it.”
Adham Khaled
“A switch costs about five times a warm turn when you're carrying 10,000 tokens, and nearly eight times when you're carrying 60,000.”
Adham Khaled
“Cursor says roughly 60% of its developers pick a single daily-driver model, which prices routine work at frontier rates.”
Adham Khaled
“a router is a bet on a portfolio that moves faster than the bet can be retrained.”
Adham Khaled
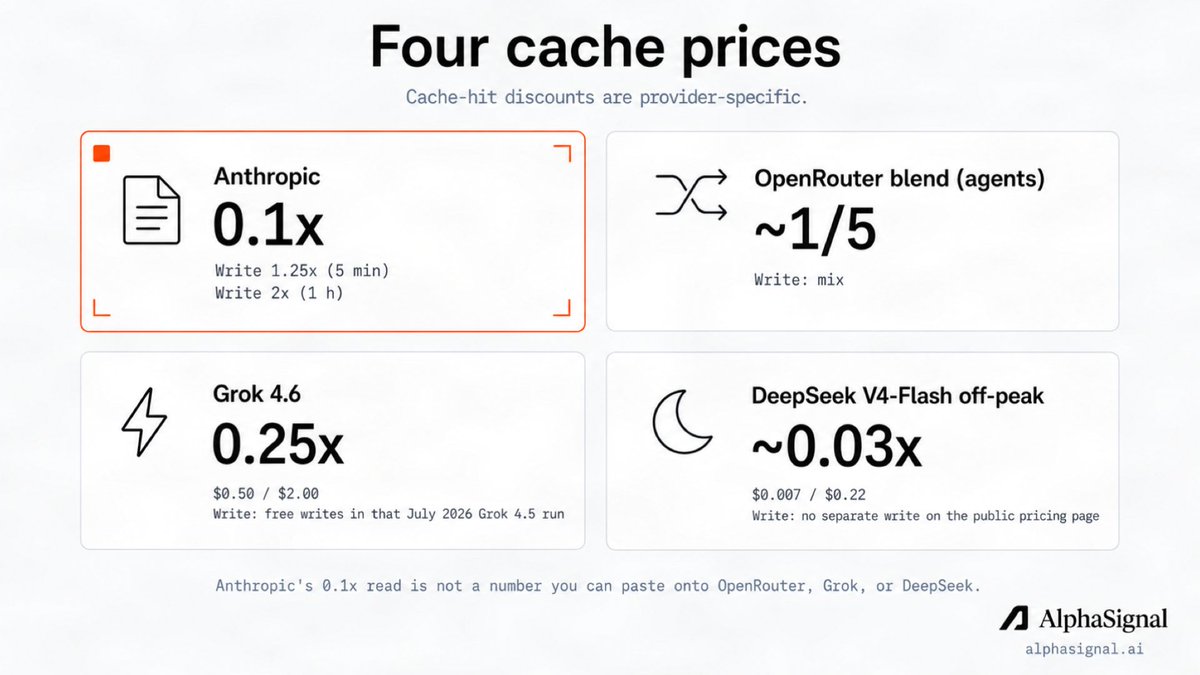 postPrompt cache TTL is the hidden line item in long coding-agent sessions
 articleFull breakdown: Claude-only apps often wait until the host speaks the new revisi
 articleDo not ask whether the agent follows the rule. Ask what stops it when it does no
 articleFull Breakdown: When can a change ship unread? When something cheap and hard to
Checking sign-in…
Loading comments…