A practical AI Evaluation pattern
- Source
- deepsense.ai
- Author
- nvmdbljstm
- Date
Context
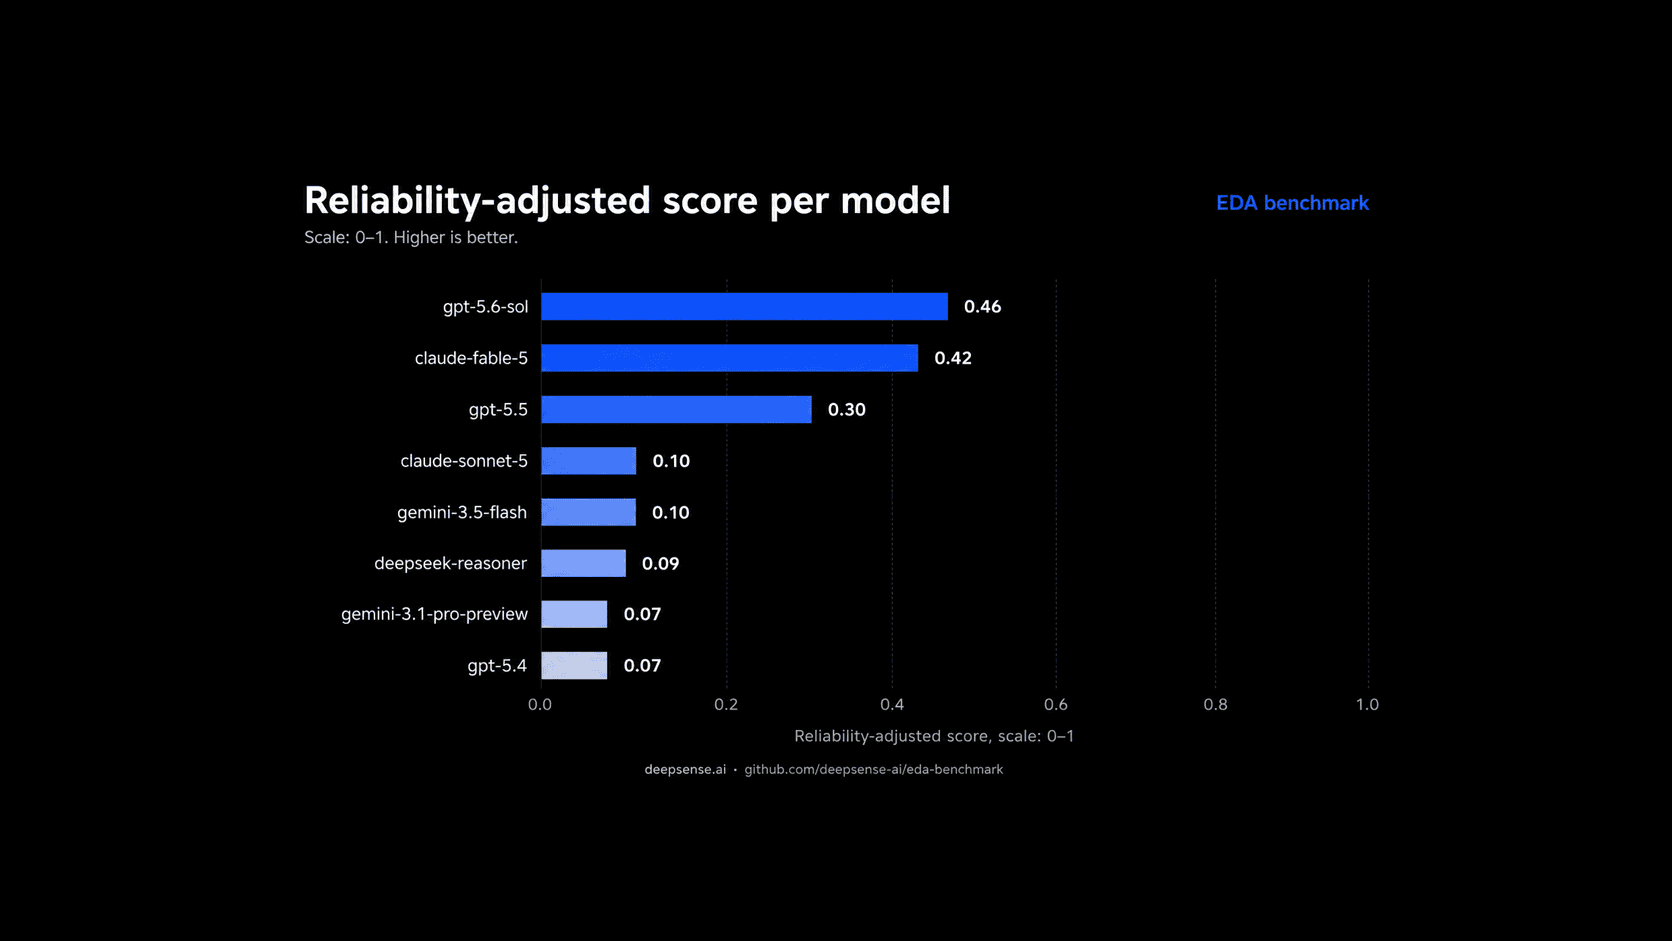
Choosing an AI system by its best run can hide how often it fails on repeat attempts. In its evaluation guide, deepsense.ai describes testing ten analytical tasks five times per model. Adjusting its scores for variation between runs reversed the ordering of the two leading models.
The adjustment was the company's own scoring formula, and the two models' average scores were close (0.50 and 0.48), so the reversal is an illustration from one rather than a general ranking. It makes the issue concrete: average quality and repeatability can favor different systems. For work that must succeed repeatedly, evaluating the same tasks several times reveals a property that a single successful demonstration cannot establish.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.

Checking sign-in…
Loading comments…