benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Why it matters
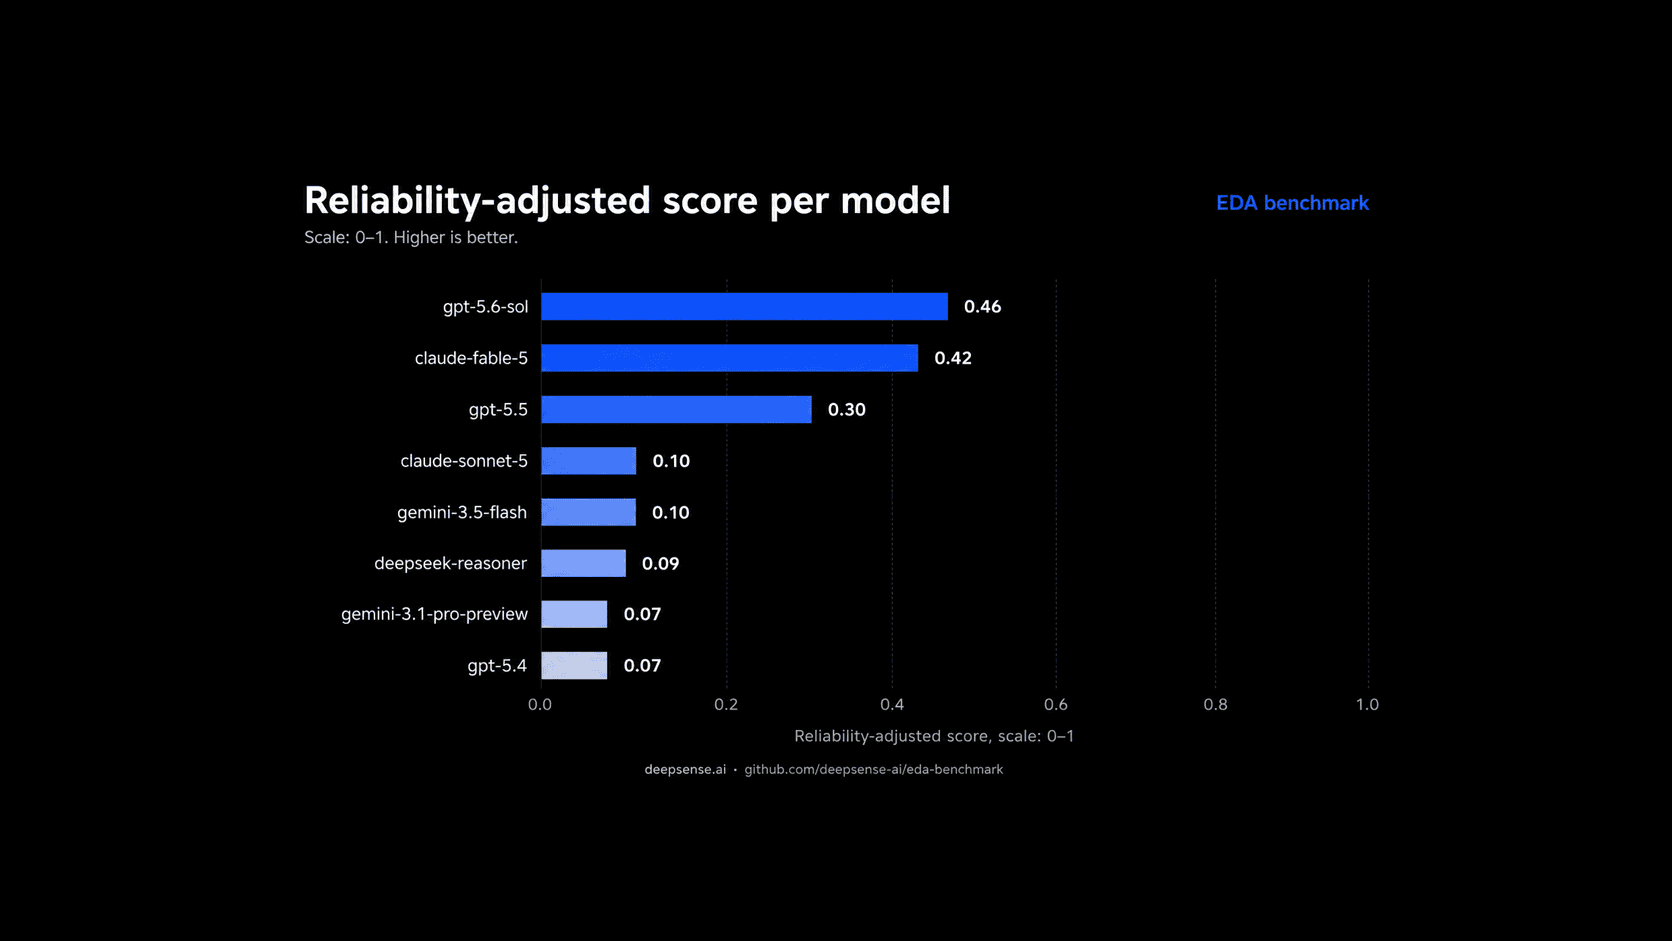
deepsense.ai's benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → shows Claude Fable 5 leads on raw mean score for exploratory data analysis while GPT-5.6-sol tops the reliability-adjusted ranking, showing that consistency across repeated runs matters as much as peak accuracy for production use.