← All IntelIntel / article
Eleven V4 Turbo In Elevenagents
- Source
- elevenlabs.io
- Author
- ElevenLabs editorial sitemap
- Date
Context
ElevenLabs has integrated Eleven v4 Turbo, the low-latency member of its v4 speech family, into ElevenAgents. Its announcement describes speech delivery that adjusts during a call, such as a more reassuring tone when a caller is frustrated. The model works alongside the platform's transcription and turn-taking models, combining speech generation with the systems that listen and manage conversational timing.
The company reports roughly 100 milliseconds of median model latency. That figure concerns inference, not the complete time a caller waits for a reply. The supported change is an integrated expressive speech option for live agents; improved customer outcomes remain the company's intended benefit.
Key takeaways · AI-distilled
- ElevenLabs says Eleven v4 was preferred by about 75% of listeners in blind head-to-head tests against Cartesia Sonic 3.6, Inworld TTS-2 and two Gemini 3.8 TTS models, with ties counted as half.
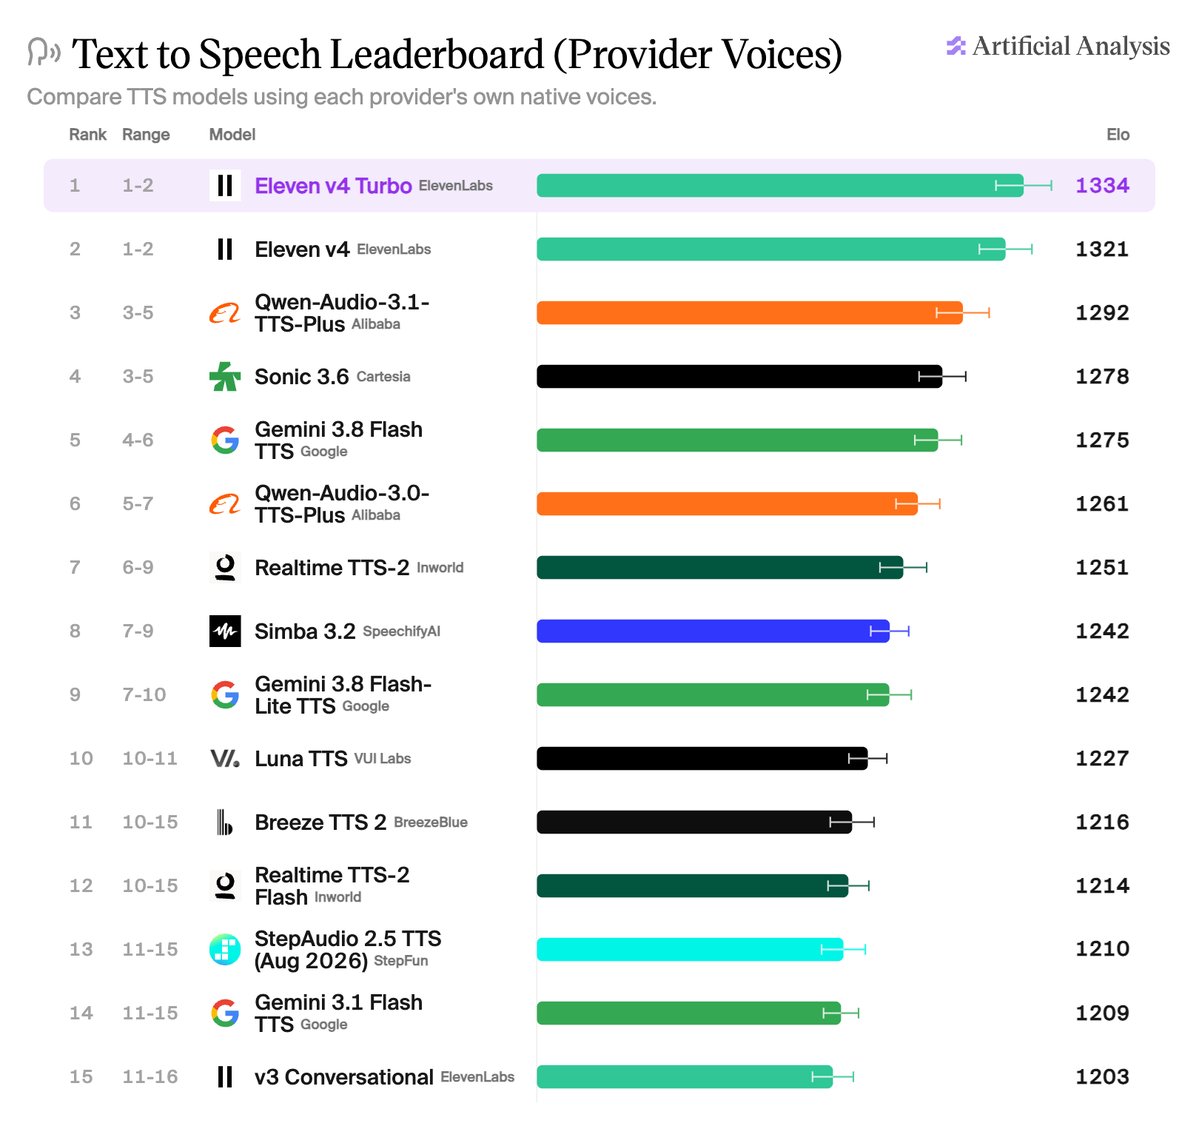
- The company reports Eleven v4 ranked first on Artificial Analysis's Provider Voice Arena leaderboard as of September 2026.
- Among the 90+ supported languages, ElevenLabs says the largest improvements are in Japanese, Brazilian Portuguese, Mandarin and Cantonese.
- When a caller switches languages, the can either keep recognizably the same voice or switch to a different voice for native-level accuracy, according to ElevenLabs.
Terms in this piece · Glossary
Read the source elevenlabs.io
More from ElevenLabs editorial sitemap
Recommended reads
Comments
Checking sign-in…
Loading comments…