E-Commerce Bench tests agents on a full simulated year of store operations
- Source
- arxiv.org
- Author
- Alibaba_Qwen
- Date
Context
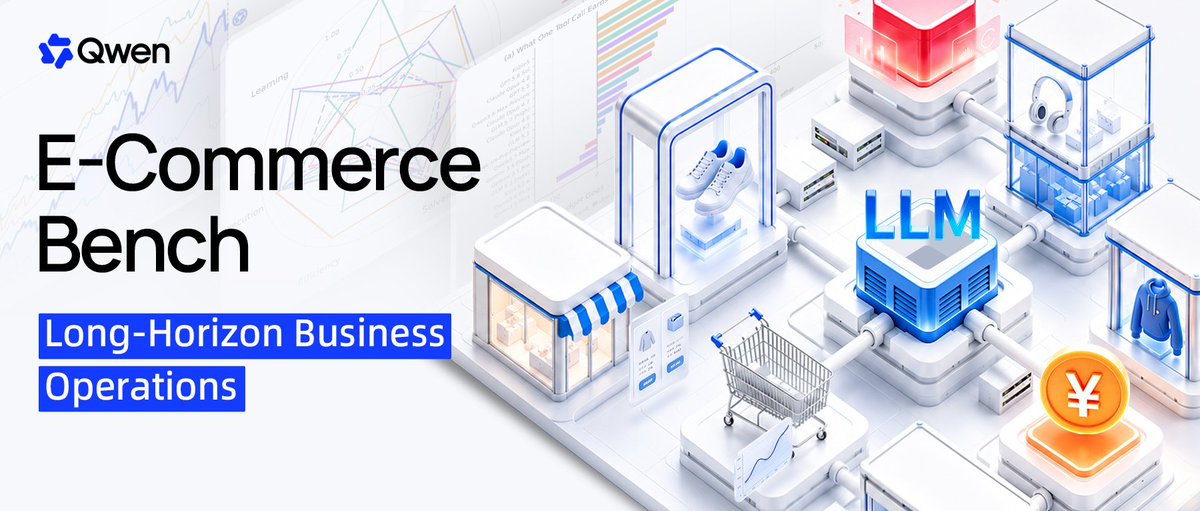
E-Commerce Bench, from Qwen researchers, gives an ¥100,000 and a simulated 365-day year to run up to four online stores, sourcing goods by negotiating with 576 suppliers, 152 of them fraudulent across five kinds of scam, then pricing, shipping, handling returns and managing cash, according to the paper. Products and suppliers come from a real e-commerce platform, but both sides of the market are deterministic: customers follow a fixed demand model, and a rule-based negotiation engine sets every supplier price and decision while a only turns those decisions into dialogue, so a difference in outcome comes from the agent rather than from a randomly sampled reply. Each of 18 models ran the year five times, and runs are scored on year-end assets plus six other dimensions.
Those dimensions do not line up. OpenAI's GPT-5.6 Sol earned the most, growing the stake to ¥1,431,425, roughly 14 times over, yet ranked 16th of 18 on fraud avoidance, measured as the share of order spending that went to fraudulent suppliers. Anthropic's Claude Opus 4.7 led both bargaining and fraud avoidance while finishing mid-pack on profit. The paper explains why scams did not cost the leader its year: a scam before the deal inflates a price that still sits inside the honest range, and a scam after the deal still delivers most of the goods. Models contacted fraudulent suppliers at about their share of the list; what differed was how often an approach became an order, from 4.0% for Opus 4.7 to 31.7% for GPT-5.6 Sol. The authors caution that the fraud readings rest on a handful of orders, with run-to-run variation larger than the average for 15 of the 18 models.
Learning over the year was the weakest result. Across 8,647 repeat purchases of the same item from the same honest supplier, 16 of the 18 models showed no clear sign of pushing the price down as the year went on. Only two, Qwen3.8-Max-Preview, the authors' own model, and Google's Gemini 3.5 Flash, paid less on repeat orders than a random reshuffling of the prices they had already won would have cost, and 16 of 18 captured less of the bargaining range in the second half of a run than in the first. The paper names possible causes, including earlier prices dropping out of the model's , and says the does not separate them.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.

Checking sign-in…
Loading comments…