Qwen-Image-2.1-Turbo ships open weights with 8-step generation
- Source
- x.com
- Date
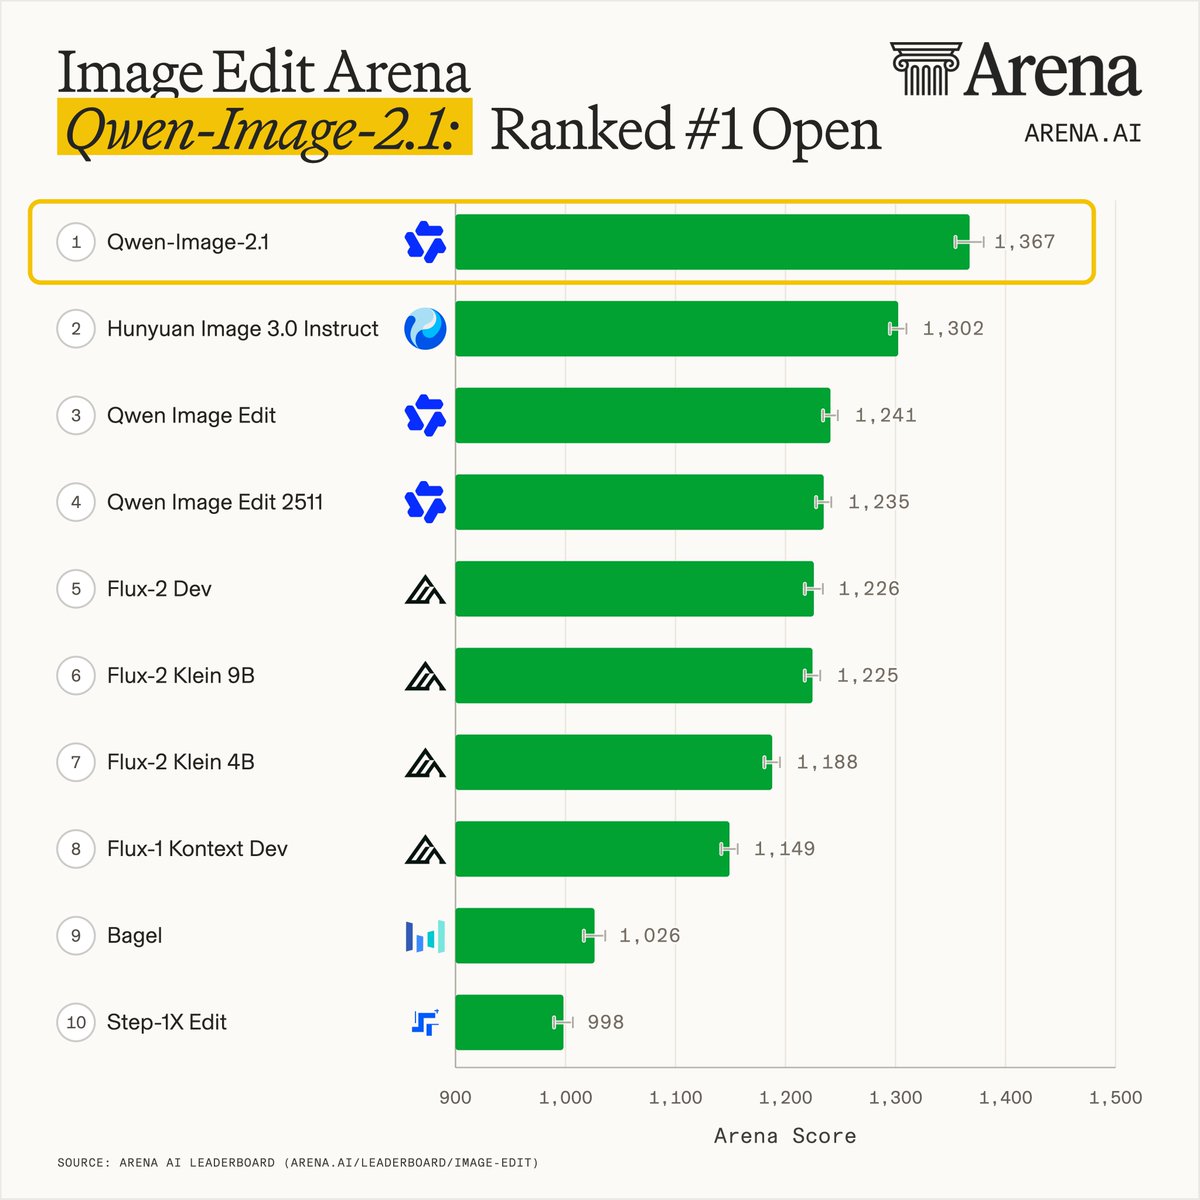
🚀 Meet Qwen-Image-2.1-Turbo — create and edit images in just 8 denoising steps! Open weights now available! Built on Qwen-Image-2.1, Turbo is an accelerated checkpoint on the same 7B visual generation architecture. Fewer steps does not mean lower quality: it still generates strong 2K images from text, and supports continued creation through natural-language edits, from adding accessories to changing a scene. Start directly with Diffusers: load QwenImage21Pipeline and the checkpoint’s recommended 8-step sampling schedule is ready to go. 🌐 Prefer an API? Qwen-Image-2.1 Pro and Turbo APIs are now officially live. Choose a hosted API for your application, or use the Turbo weights in your own workflow. 🤖 ModelScope: https://t.co/Cixiro51v8 🤗 Hugging Face: https://t.co/4GqXcYeAmB 🔗 Pro API: https://t.co/fw2am7VCP7 🔗 Turbo API: https://t.co/qmDvTqiVZK What will you create with 8 steps? Share your results with us!
A 7B image model that generates and edits 2K images in 8 denoising steps cuts cost and latency. You can run it via Diffusers or use the hosted API.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
- distillation — Training a small, cheap model to imitate a big one's outputs, keeping much of the capability at a fraction of the cost.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
Checking sign-in…
Loading comments…