Vals AI Launches an Index for Measuring Recursive Self-Improvement
- Source
- x.com
- Date

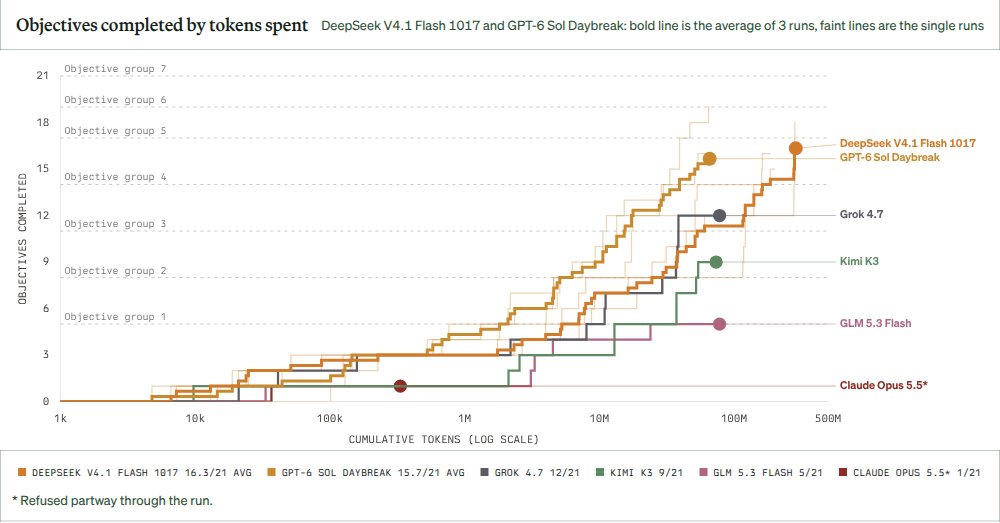
AI safety is back in the spotlight, driven by concerns about recursive self improvement. We built the first third party benchmark to measure just how close AI is building its own successor. In collaboration with @marimo_io and @CoreWeave we built the The RSI Index, which runs every frontier model through the same AI research tasks and scores each one against the strongest published results. So far, the models can do the work, but is far from the human frontier.

Context
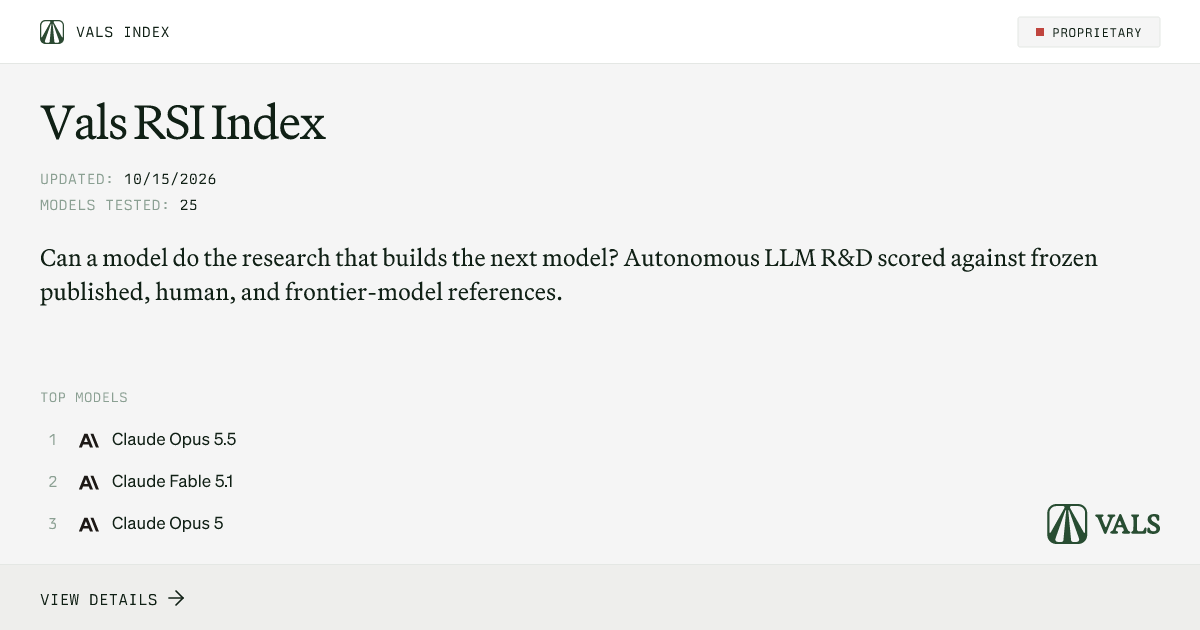
Vals AI has launched the RSI Index, a built with CoreWeave and marimo to measure how close AI models are to doing the research and development work needed to build their own successors. Each task gives a model a fixed compute and time budget to work on an open-ended AI R&D problem, such as efficiently training a model or engineering an evaluator, and grades the result against the best result a human team has achieved on the same task, according to the index page.
As of this launch, Claude Opus 5.5 leads the index at 37.31%, followed by Claude Fable 5.1 at 36.09%, scores well short of the human-expert baseline the index anchors to. Vals AI frames this as evidence that models can already do meaningful pieces of AI research work, even though none come close to the strongest published human results on the same tasks, a distinction that matters for anyone trying to gauge how near models are to accelerating their own development rather than just performing well on existing benchmarks.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Checking sign-in…
Loading comments…