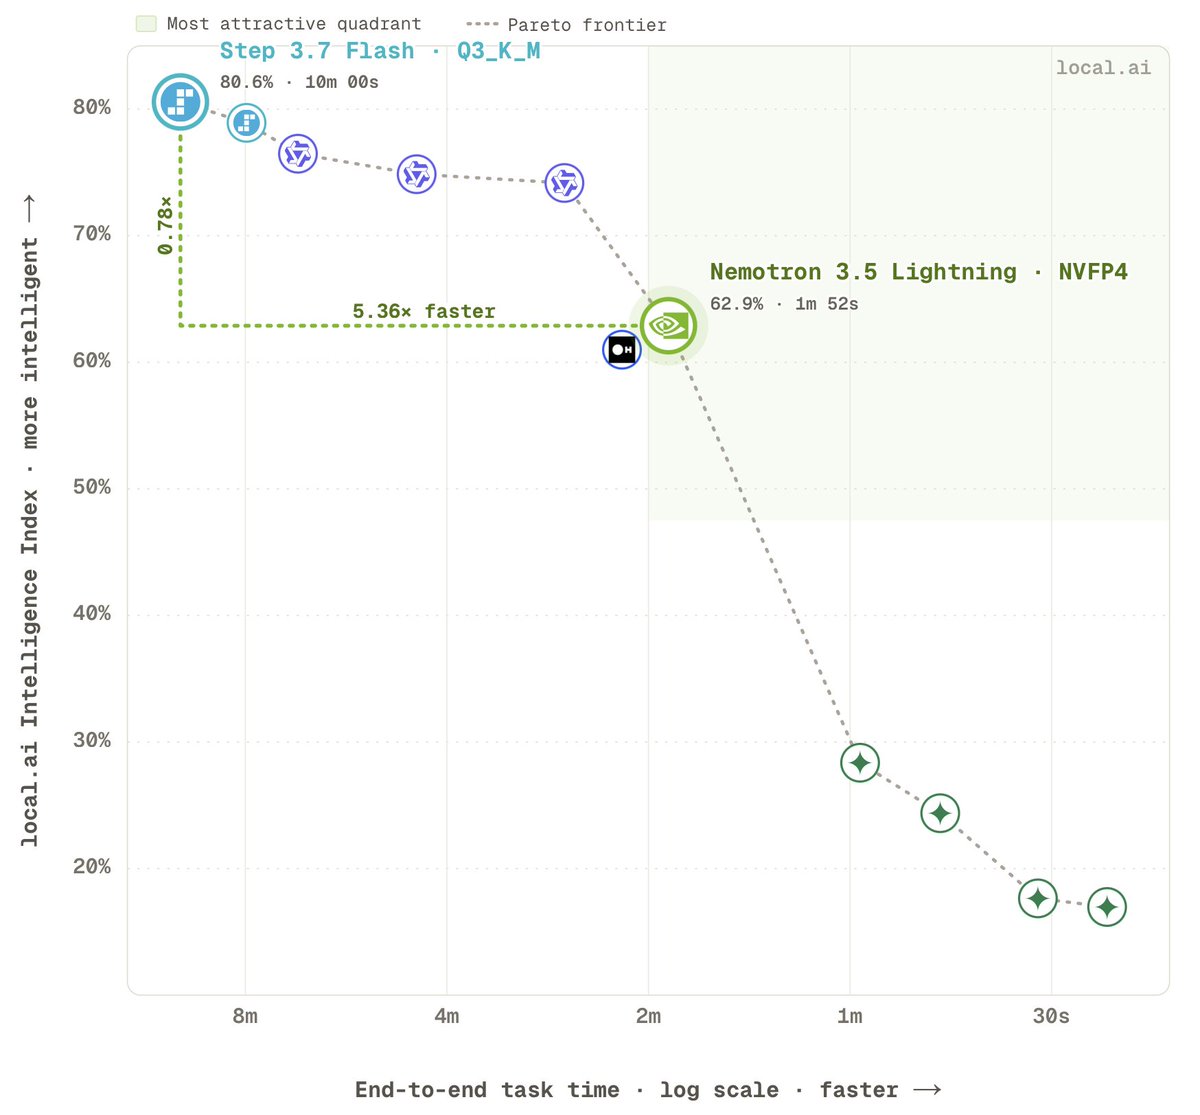
Nemotron 3.5 Lightning was released with native support for MTP, DFlash and…
- Source
- x.com
- Date

Nemotron 3.5 Lightning was released with native support for MTP, DFlash and DSpark. We recommend DSpark on DGX Spark. Here is the full vLLM configuration for DGX Spark with DSpark so you can run it yourself: vllm serve \ nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-NVFP4 \ --served-model-name nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-NVFP4 \ --trust-remote-code \ --moe-backend marlin \ --kv-cache-dtype fp8 \ --max-model-len 262144 \ --max-num-batched-tokens 16384 \ --quantization modelopt_fp4 \ --mamba-backend flashinfer \ --mamba-ssm-cache-dtype float16 \ --enable-mamba-cache-stochastic-rounding \ --mamba-cache-philox-rounds 5 \ --enable-prefix-caching \ --mamba-cache-mode align \ --speculative-config '{ "model": "nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-NVFP4-DSpark", "method": "dspark", "num_speculative_tokens": 7 }' vllm image: vllm/vllm-openai:nightly-7794b1e08bf505ff28664515ffaaeeec955ab796
Context
Alex Cheema's DGX Spark recipe pairs Nemotron 3.5 Lightning with a separate DSpark draft model and pins a specific nightly build of the vLLM serving software. The configuration requests seven speculative at a time. Published configuration.
The draft model proposes text that the main model verifies, aiming to accelerate generation, as the DSpark paper abstract describes. The model card from NVIDIA identifies this checkpoint as a companion to Lightning, tuned for DGX Spark and low-concurrency deployments. That makes the recipe a concrete deployment configuration for that pairing.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
- KV cache — The memory a model keeps about text it has already read, so generating each new token doesn't require reprocessing the whole conversation.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- postIs the Rush to Build New LLM Inference Engines Fragmenting the Ecosystem?
- postBig model. 2.4T params, 95B active. 4.89TB. Surprised they didn't release a 4-bi
 post@Jason @Lons @eisokant @ape Correction: Should actually be closer to 50 tok/sec
 postApple markets a four-Mac cluster for trillion-parameter local inference
Checking sign-in…
Loading comments…