Nemotron 3.5 Lightning completes tasks 5.36x faster than the most intelligent mo
- Source
- x.com
- Date

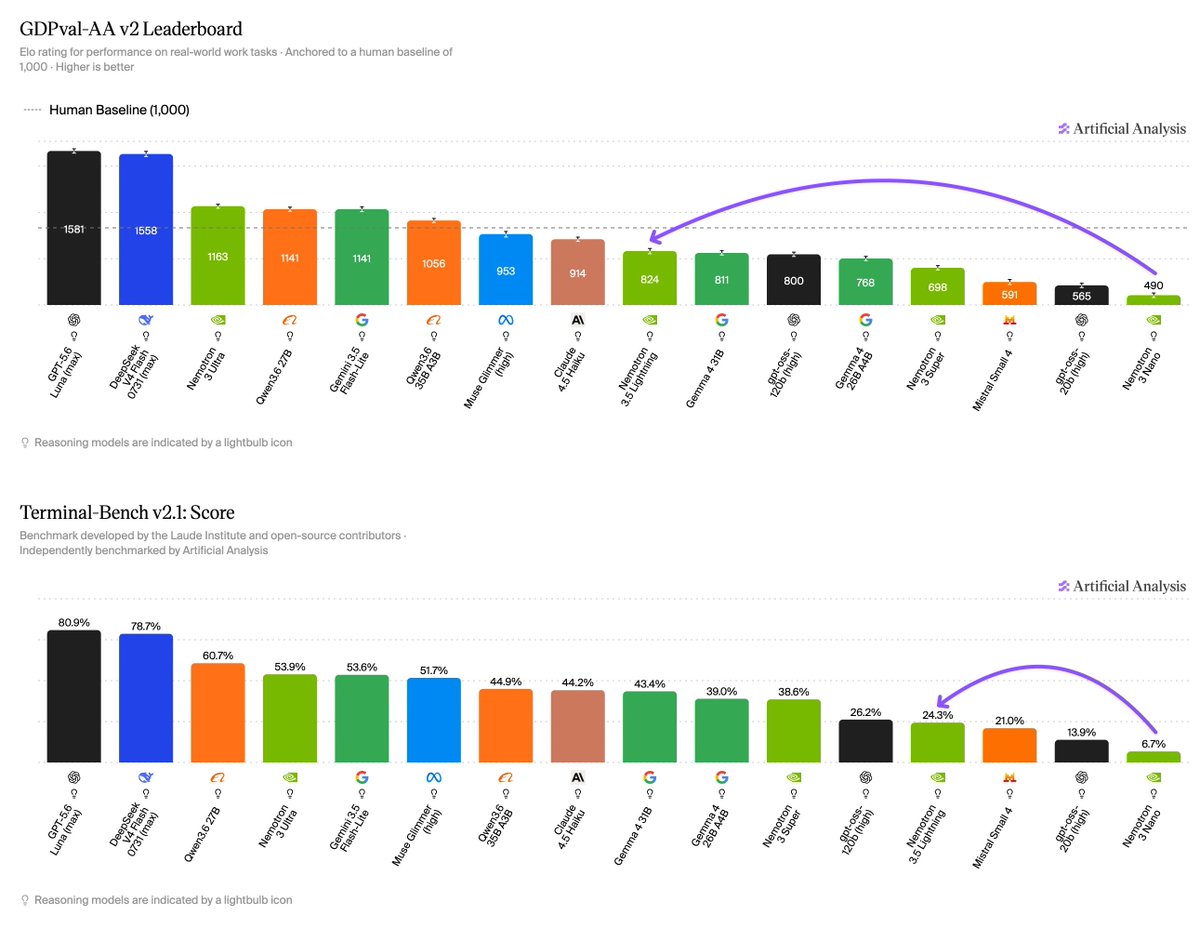
We worked with @nvidia to understand how Nemotron 3.5 Lightning performs locally on the DGX Spark. We ran the same set of 884 agent tasks on 100 unique models and compared them on Intelligence and Speed. Here's what we found 👇 (Full results on https://t.co/b6s9nCUDko) https://t.co/RD0jmQJR8C

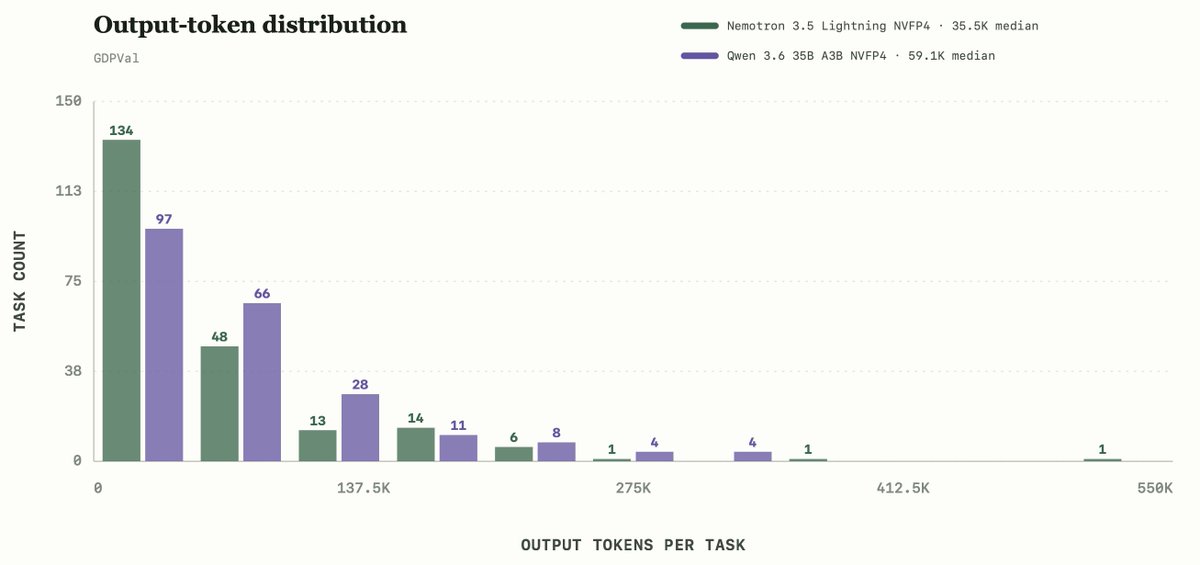
Nemotron 3.5 Lightning completes tasks 5.36x faster than the most intelligent model that runs on the DGX Spark (Step 3.7 Flash) while retaining 78% Intelligence. Why is it 5.36x faster? Despite being a much smaller model, Lightning uses about the same number of output tokens per task as Flash (on average ~2% more). However, it runs much faster per token on decode on DGX Spark, accounting for the 5.36x overall speedup.

Context
In Alex Cheema's tests on NVIDIA's DGX Spark, the company's Nemotron 3.5 Lightning finishes tasks sooner than Step 3.7 Flash because it generates each faster; it writes about as much. Cheema says his team worked with NVIDIA to see how Lightning performs locally on the Spark, ran the same 884 agent tasks on 100 models, and compared them on intelligence and speed (thread). Lightning completed tasks 5.36 times as fast as Step 3.7 Flash, which Cheema calls the most intelligent model that runs on the DGX Spark, while retaining 78% of its intelligence (post).
The token counts explain the speedup. How long a task takes depends on how much text the model writes and how fast it writes it. Lightning is much the smaller model but used about the same number of output tokens per task as Step 3.7 Flash, around 2% more on average, so Cheema attributes the 5.36-times speedup to Lightning's much faster per-token decoding on the Spark.
The 78% compares Lightning with Step 3.7 Flash on the team's intelligence measure; it is not presented as a share of tasks solved. The thread does not define that measure or explain how either figure was computed beyond the token comparison. Another post in the same thread shows the opposite case: against Qwen 3.6 35B A3B, Lightning finishes sooner even though Qwen decodes faster, because Qwen writes much more.
- postIs the Rush to Build New LLM Inference Engines Fragmenting the Ecosystem?
- postBig model. 2.4T params, 95B active. 4.89TB. Surprised they didn't release a 4-bi
 post@Jason @Lons @eisokant @ape Correction: Should actually be closer to 50 tok/sec
 postApple markets a four-Mac cluster for trillion-parameter local inference
Checking sign-in…
Loading comments…