Time Horizon 1.1
- Source
- metr.org
- Date
Context
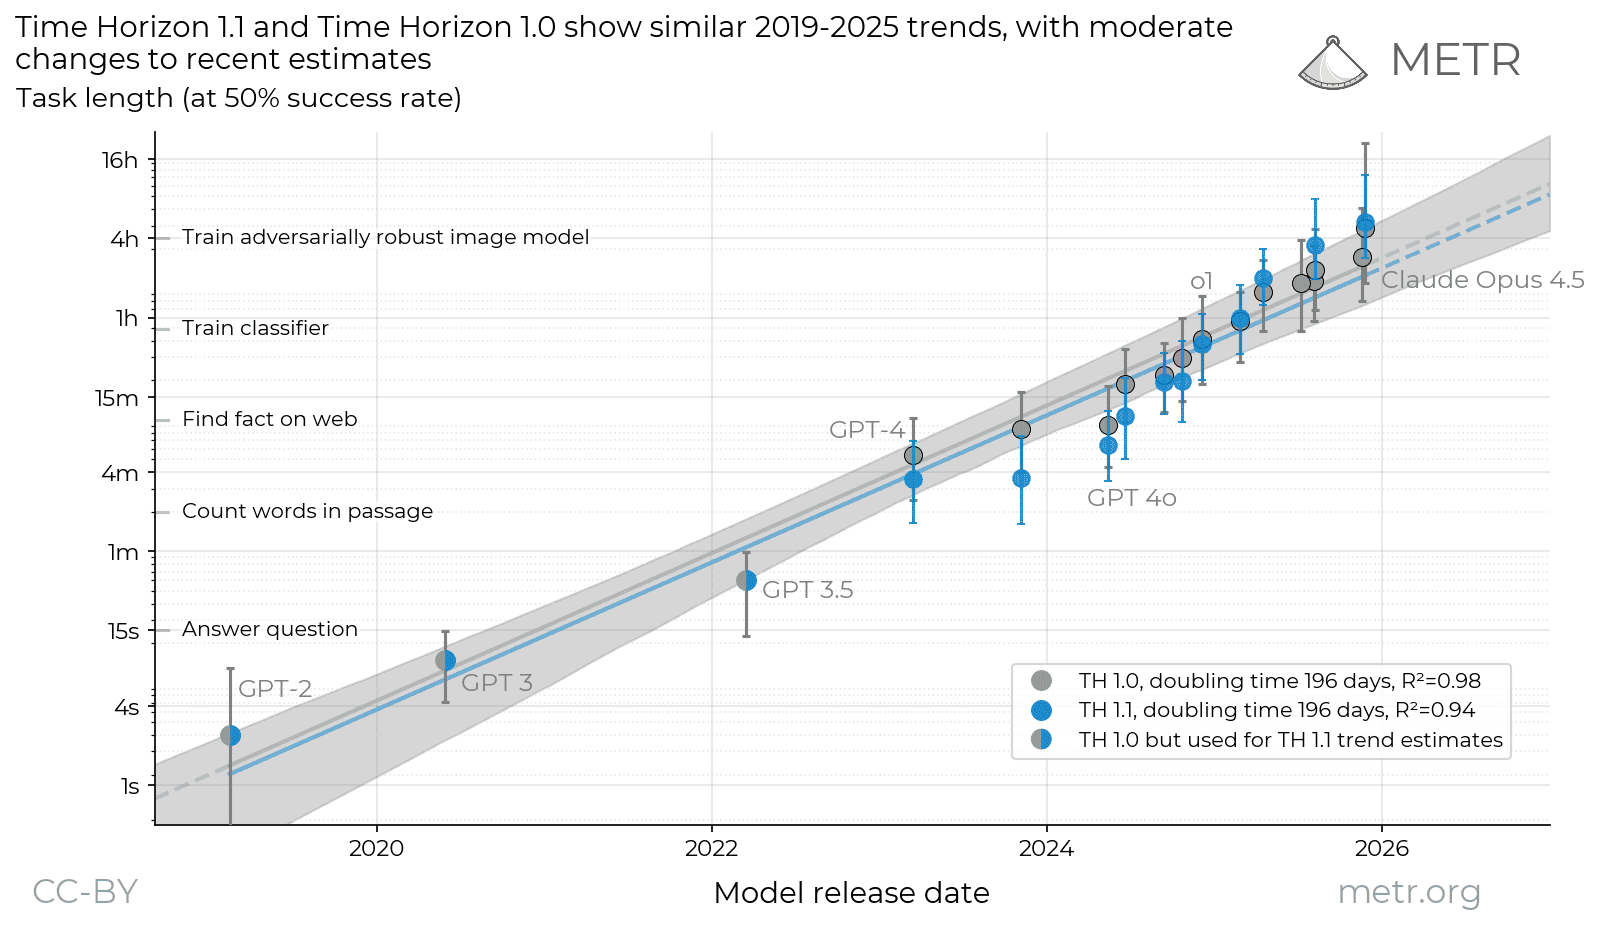
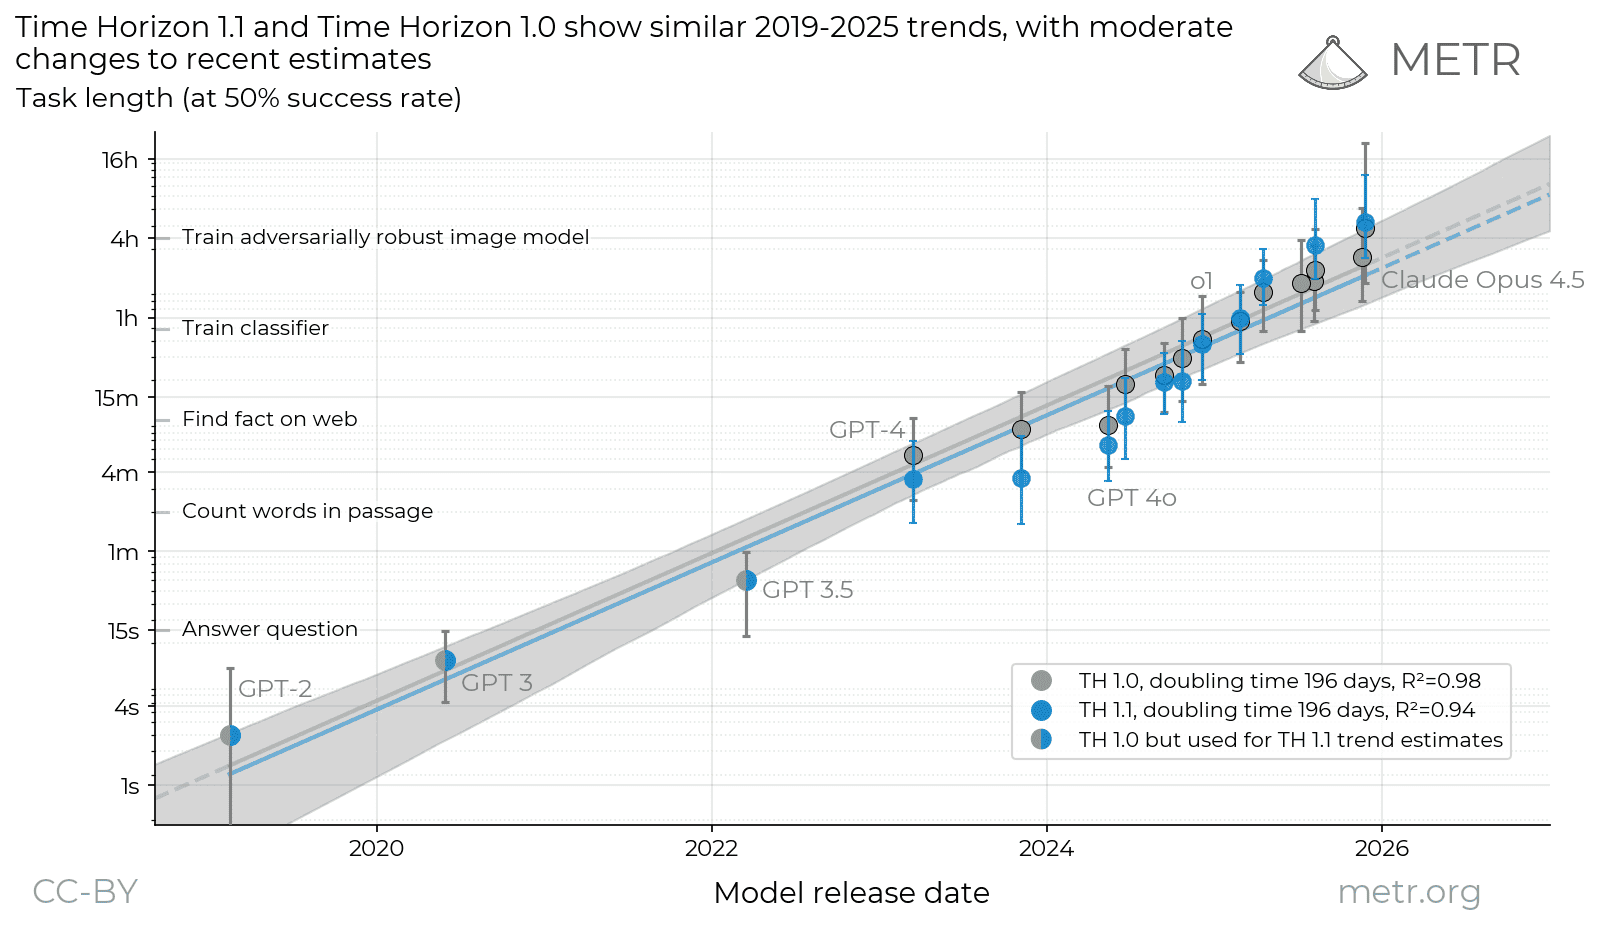
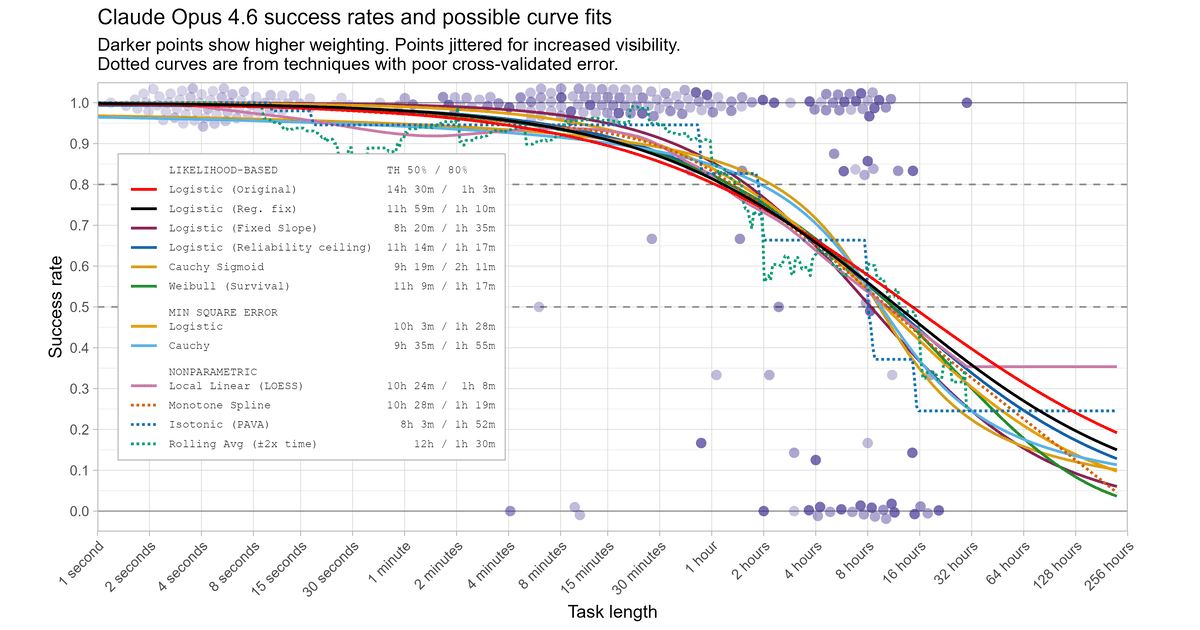
Adding harder tasks can change both a capability estimate and the apparent rate of progress. METR measures a model’s time horizon: the length of task, in human working time, that the model completes with 50% success. Its Time Horizon 1.1 update raises tasks estimated at eight or more human hours from 14 to 31, fixes problematic tasks and changes infrastructure. Estimates for stronger models tighten, though uncertainty remains wide.
Successive versions are therefore not interchangeable. Since 2023, the estimated doubling time is 131 days under TH1.1 versus 165 under the original suite, as older models’ estimates fell and recent ones rose. METR thinks the new tasks likely reflect a slightly different difficulty mix. Any claimed doubling time belongs beside its task suite and model set.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Checking sign-in…
Loading comments…