Measuring Time Horizon using Claude Code and Codex
- Source
- metr.org
- Date
Context
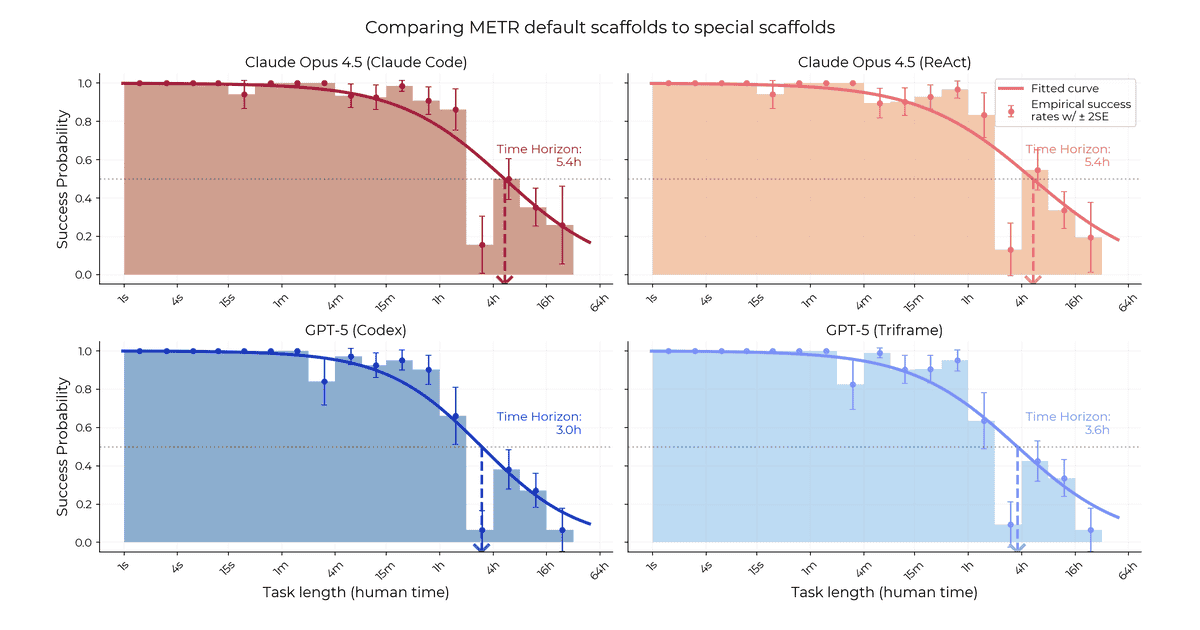
A coding assistant designed for interaction need not score better in an unattended . In METR’s comparison of agent software, GPT-5 in Codex and Opus 4.5 in Claude Code did not show a statistically significant time-horizon advantage over the evaluator’s default setups. Each model was compared across the surrounding software rather than against a different model.
The conditions limit what follows from that result. The tasks provided no human feedback, the integration wrappers had rough edges, and the GPT-5 comparison did not use the specialized GPT-5-Codex model. The study helps check whether the evaluator’s simpler setups miss a large advantage in these tests; it does not establish equivalence across everyday interactive coding work.
Checking sign-in…
Loading comments…